

Breakthrough AI to solve the world's biggest problems. › Join us: https://teapawt.net/t.co/MjUpZpKi8b › Newsletter: https://teapawt.net/t.co/k9gGznrVGL
Seattle, WA
Joined September 2015
- Tweets4.1K
- Following451
- Followers87.2K
- Likes3.7K


Pinned Tweet
We’re releasing Olmo-core 3—open training infrastructure for large mixture-of-experts (MoE) models.
It’s a core system behind the next generation of Olmo, designed to scale into the trillion-parameter range. 🧵
💻 GitHub repo: github.com/allenai/olmo-core

Ai2 retweeted

Fun project led by @jowenpetty ! StateBench is benchmark for long-context state tracking abilities that we're already using internally to develop new Olmo models

Can LLMs track state changes over long texts—like an object changing hands or a variable reassignment?
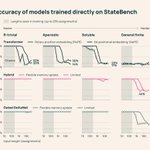
On our new StateBench eval, frontier models including GPT-6 Sol & Claude Opus 5.5 fell to 13% accuracy or lower on the hardest, longest problems. 🧵
github.com/allenai/state-ben…
Ai2 retweeted

Really excited to share what I was working on this summer at @allen_ai with @lambdaviking and @Ashish_S_AI !!
Can LLMs track state changes over long texts—like an object changing hands or a variable reassignment?
On our new StateBench eval, frontier models including GPT-6 Sol & Claude Opus 5.5 fell to 13% accuracy or lower on the hardest, longest problems. 🧵
github.com/allenai/state-ben…
Can LLMs track state changes over long texts—like an object changing hands or a variable reassignment?
On our new StateBench eval, frontier models including GPT-6 Sol & Claude Opus 5.5 fell to 13% accuracy or lower on the hardest, longest problems. 🧵
github.com/allenai/state-ben…
On StateBench’s hardest level, a flexible Gated DeltaNet handled sequences ~10× longer than those seen in training.
Our new proof shows that even Gated DeltaNet with non-negative eigenvalues can solve some periodic tasks under fixed-precision arithmetic with rounding.
We’re releasing StateBench so researchers can test new models, extend our work, & build better state-tracking data.
Explore more in our blog: allenai.org/blog/statebench
Download the dataset: huggingface.co/datasets/alle…

For open-source collaboration platform @Nextclouders, local AI is only part of digital sovereignty. Users also need to inspect how a model was built.
That’s why Nextcloud chose Olmo 3 to power AI in Nextcloud Assistant & its other apps. 🧵
allenai.org/blog/nextcloud

Nextcloud also chose Olmo with consumer-grade hardware in mind.
The team wanted a local model users could run without expensive, high-end machines.


For CENTURIA, TU Wien & Austrian Academy of Sciences researchers fine-tuned olmOCR 2 on handwritten pottery records from Carnuntum, Austria.
olmOCR 2 made fewer transcription errors on held-out records than an unadapted model. The team now aims to apply it to the full archive.

olmOCR 2 helps researchers turn file scans into searchable text, run OCR on local hardware, & adapt the model to their specific needs.
Learn more in our blog: allenai.org/blog/olmocr-2-hi…

Ai2 retweeted

Our new work on novelty detection with LLMAJ. This also has implications for human reviewers (for #ICLR etc.) who use LLMs to judge paper novelty - people should, at the very least, be aware of their current instability and sensitivity to the prompt.
LLMs are increasingly used to judge whether AI-generated research ideas are novel. But are they any good at it?
Our new eval reveals even frontier LLMs can reach different conclusions about similar ideas depending on how they're asked to evaluate them. 🧵
github.com/allenai/novelty-e…

Ai2 retweeted

Uh oh. If your AI benchmark uses an LLM-as-judge, you might want to read this.
AllenAI tested six frontier models to see whether research ideas were actually novel.
And tiny changes to the judge prompt caused crazy swings.
GPT-5.4, same basic idea pairs
“Which was judged novel?” → 93.5%
“Which is novel?” → 40.9%
“Which was judged more novel?” → 59.7%
Across the study, changing the prompt moved accuracy by 👉50+ points 👈 in some cases and occasionally pushed judges below chance.
So naturally they tried giving the judge more intelligence and tools.
Didn't fix it.
A GPT-5.6 Sol agent running xhigh reasoning with iterative literature search and no search cap scored
→ 0.78 macro-F1
Claude Opus 4.6 with only 5 pre-retrieved abstracts did about
→ 0.89
And the big agentic setup cost ~10× more per judgment.
Two purpose-built novelty-evaluation systems lost to the researchers' cheapest simple prompted judge by
→ 8–29 macro-F1 points
while costing up to
→ 32× MORE
🎯 Lesson Learned 👉 More model, more reasoning more RAG, and more money, doesn't automatically mean a better judge.
AllenAI open-sourced the benchmark + code too, so now I want to see Qwen, DeepSeek and other local models run as the judges.
The safer benchmark recipe is
👨🔬 build a human-rated calibration set
🤖 test the LLM judge against it
🔄 test multiple prompt/order variations
🗳️ aggregate multiple judgments
👀 send close calls back to humans
Link in ALT

ALT https://github.com/allenai/novelty-eval
Ai2 retweeted

Our paper got an Ai2 writeup! Code and data are now released through Ai2, links in the post 👇
With @its_sshahid , @peterjansen_ai , @dsweld , @Siangliulue , @Hoper_Tom
LLMs are increasingly used to judge whether AI-generated research ideas are novel. But are they any good at it?
Our new eval reveals even frontier LLMs can reach different conclusions about similar ideas depending on how they're asked to evaluate them. 🧵
github.com/allenai/novelty-e…
Ai2 retweeted

timely benchmark teapawt.net/allen_ai/status/211512…
LLMs are increasingly used to judge whether AI-generated research ideas are novel. But are they any good at it?
Our new eval reveals even frontier LLMs can reach different conclusions about similar ideas depending on how they're asked to evaluate them. 🧵
github.com/allenai/novelty-e…