

Inference is everything.
San Francisco and New York
Joined March 2021
- Tweets3.1K
- Following85
- Followers22.4K
- Likes6.9K






"With customization, and with partners in the ecosystem that we work with, you could turn these models into the frontier. And as a result, turn your proprietary data into sovereign intelligence."
Thanks, @JensenHuang and @NVIDIAAI, for highlighting our work with the team at @coderabbitai on post-training open-source models to reach frontier capability!
Meta’s Muse Spark Open is live on the Baseten Loops SDK for post-training.
Train it on your data with your reward functions; Loops runs the training and sampling infrastructure.
When your checkpoint is ready, deploy it straight to a production inference endpoint.
docs.baseten.co/loops/quicks…

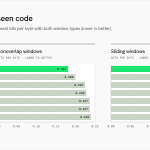
We ran @mirendil's new base model on Baseten's private codebases; that is, code it's never seen. Mirendil-Base-Large had the lowest bits per byte (a tokenizer-independent measure of perplexity) of any model we tested.
We're excited to be the inference partner to serve Mirendil models. Congrats to the Mirendil team on this launch!

Full interview here: cnbc.com/video/2026/10/22/ba…

Today we’re announcing the Baseten Environment Network, a group of the best RL environment companies that will help our customers build custom environments for post-training.
The Network extends our applied research capacity, helping more customers build environments around their own tasks, data, and feedback.
Partners work directly with customers to create the environments, while we continue to handle model training and production deployment.
Learn more: baseten.co/blog/introducing-…

We're excited to partner with @abundant_labs, @ArcanumLabs_, @CtrlG_com, @datacurve, @eigent_AI, @fleet_ai, @micro1_ai, @preferencemodel, @ProximalHQ, @SnorkelAI, @tastelabs, and Very Large Research (@andrewho03) to help customers accelerate their journey to owning their intelligence!
.@markchen90, Chief Research Officer at @OpenAI, is joining the All-Gather speaker lineup! This room keeps getting more stacked.
Applications are coming in faster than we can keep up with. If you haven't applied yet, you can here:
baseten.co/all-gather/

Meet Simba 3.5: one model, 48 languages, streaming-native. Compatible with every voice, including cloned voices.
Congrats to the @SpeechifyAI team, we're proud to be your partner for inference!

Thanks, @brexHQ. 💚 We're hiring across the board.
baseten.co/resources/careers…

Today we’re releasing two decision models, elephant-1 (9B) and mammoth-1 (27B), trained by the @baselabs team, available for free for one week on our Model APIs.
mammoth-1 is #1 on the Jev Decision Index and elephant-1 is tied for #1 on the Artificial Analysis Decision Index.
It’s a new model, but more importantly, this is an open-source model you can access, deploy, and post-train on Baseten (or wherever you do your best work).
The free week ends 10/27/26 at 11:59 PM PT. Try it and let us know what you think.
Try mammoth-1 here: baseten.co/library/mammoth-1…
Try elephant-1 here:
baseten.co/library/elephant-…

Check out the Jev Decision Index rankings here: huggingface.co/spaces/multim…

See the live @ArtificialAnlys rankings for elephant-1 here: artificialanalysis.ai/evalua…

Agent security belongs in the infrastructure layer.
We’re proud to partner with @nvidia on the OpenShell Reference Architecture, an open architecture for running AI agents with security enforced at the infrastructure level.
We build safety into how we serve models. Base Labs is building open safety infrastructure with @huggingface and @GoodfireAI, and we're bringing Goodfire’s safety monitors in line with inference on Baseten.
We also joined the Open Secure AI Alliance and partnered with NVIDIA on the Open Agent Safety Platform launch.
We’ll keep working with NVIDIA and our partners to give teams the controls they need to confidently run agents in production.

AI agents need fast tool calls and security controls they can’t rewrite.
NVIDIA OpenShell Reference Architecture combines the compute to run agents at scale with runtime controls that govern their access to tools and data.
See how the hardware and software work together: nvda.ws/4BiJBfY
The NVIDIA Nemotron Retriever collection of models is now on Baseten!
Nemotron 3.5 Embed, Parse, and Rerank help agents retrieve useful evidence across text and visual enterprise data.
Try them today: baseten.co/library/family/ne…

Check out the NVIDIA blog to learn more:
huggingface.co/blog/nvidia/n…

Benchmark performance doesn’t matter if it can’t hold up in production.
Major open models launched this month live on Baseten on day zero: DeepSeek v4.1 Flash, Reflection Beam 1.0, and NVIDIA Nemotron Super 3.5 VL.
We're proud that each ranks best on both Artificial Analysis benchmarks and OpenRouter production traffic.
The standard we’re building toward is straightforward. Whichever model you choose, you should expect consistently high performance on Baseten. From your first token to your trillionth.


We're excited to bring Mercury 3 to Baseten!
- Outperforms GPT-6 Luna, Claude Haiku 5.5
- 1,000+ tokens/sec, 4–8x faster
- 1M token context
Get access through our model library: baseten.co/library/mercury-3…


Mercury 3 is live: the most capable diffusion LLM released to date.
It outperforms GPT-6 Luna and Claude Haiku 5.5 across a range of benchmarks while running at over 1,000 tokens per second.
More than 40x the size of Mercury 1, 3x more intelligent across standard benchmarks, and just as fast, with a 1M-token context window.
Available today on the Inception API, @baseten, and @OpenRouter .
