

The most secure AI inference on earth. Powering your next AI App.
Bittensor
Joined November 2024
- Tweets846
- Following12
- Followers11.9K
- Likes526




GLM-5.3 and DeepSeek V4.1 Flash are 35% off on Chutes until Nov 23.
GLM-5.3 is $0.80 per million input tokens and $2.50 per million output. Flash is $0.195 and $0.78.
Your agent can use Flash for everyday calls and GLM-5.3 for the hard ones, on one key. Qwen3.8 Max is on it too, at its usual price.
GLM-5.3, chutes.ai/app/chute/chutes-z…
DeepSeek V4.1 Flash, chutes.ai/app/chute/chutes-d…

2
348
We've partnered with @alibaba_cloud to offer GLM-5.3, DeepSeek V4.1 Flash and Qwen3.8 Max!.
GLM-5.3 and Deepseek V4.1 are 35% off through Nov 23
Your existing key and credits work. Just change the model ID

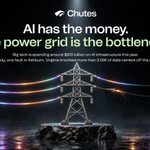
Big tech is spending around $810 billion on AI infrastructure this year, going by the slide Jon showed at Exploit. The money keeps coming. Power is the harder part.
In July, one transmission fault in Ashburn, Virginia knocked more than 3 GW of data center load off the grid at once.
Parallax trains on ordinary GPUs spread across lots of places, so it doesn’t need one giant building plugged into one stretched grid.

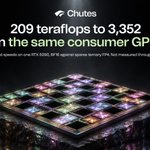
Most of the work inside an AI model is multiplying numbers. Parallax stores most of its weights as -1, 0 or 1, and at least half of those are zero, which a GPU can skip.
On one RTX 5090 that’s the difference between 209 teraflops and 3,352. Part of the jump is the card’s 4-bit mode, and skipping the zeros doubles it again. Those are the chip’s rated speeds, not measured ones.
It’s a big part of how one card hit almost 18,000 tokens a second.

Chutes retweeted
Bittensor’s @chutes_ai trained Parallax 8B across hundreds of consumer GPUs around the world.
Now their latest preview shows it handling 256 AI requests simultaneously on a single gaming GPU.
The future of AI compute won't be confined to giant data centers.


How is it this fast? A small model, 4-bit math for the expert layers, and a fixed-size cache for most of the attention.
The Parallax paper: chutes.ai/parallax.pdf
GLM 5.2 Fast is live on Chutes.
Z.ai's GLM 5.2, for chat and agents where the reply is on the clock. 1M-token context, 128K max output.
Here's what GLM 5.2 is good at, on Z.ai's published scores: 81.0 on Terminal-Bench 2.1, four points behind Opus 4.8 at 85.0, and 62.1 on SWE-bench Pro, up from GLM 5.1's 58.4. Z.ai built it for long-horizon tasks.
Base URL llm.chutes.ai/v1, model zai-org/GLM-5.2-Fast, same key as every other model ofc.
$2.45 per million input tokens, $7.70 out.

The settings and Z.ai's scores on one card.
Model page and pricing: chutes.ai/app/chute/chutes-z…

3
581
Chutes retweeted
Bittensor subnet @chutes_ai has partnered with Tencent Cloud.
Chutes is a launch partner for @TencentHunyuan’s new flagship AI model, Hy4, now available through its API.
Day-one access to leading AI models is business as usual on Bittensor.
Tencent Hy4 is live on Chutes
We’re a launch partner with @TencentHunyuan.
It’s Tencent’s new flagship, and the first Hy model that can see. It reads screenshots and charts, and it can drive a terminal or a desktop app for you.
0.525$ per million tokens in, 1.5625$ out.
Already on Chutes? Just Change the model name to start using it
Try now: chutes.ai/app/chute/chutes-t…

Tencent Hy4 is live on Chutes
We’re a launch partner with @TencentHunyuan.
It’s Tencent’s new flagship, and the first Hy model that can see. It reads screenshots and charts, and it can drive a terminal or a desktop app for you.
0.525$ per million tokens in, 1.5625$ out.
Already on Chutes? Just Change the model name to start using it
Try now: chutes.ai/app/chute/chutes-t…
Last Week in Chutes, week 24. Two weeks of news:
→ Seven new models on Chutes: DeepSeek V4 Pro, DeepSeek V4.1 Flash, Qwen3.8 Max, Qwen3.8 2.4T A95B, GLM 5.3, GLM 5.2 Fast and Kimi K2.7 Code. Same API key, same credits, just a new model id
→ Chutes is now pay as you go. Plus and Pro are gone, and you pay for what you use with credits. Plans you’ve already paid for keep working until the period ends
→ Timon’s essay on why we’re doing this: a pipeline that’s open all the way down, building models efficient enough to run on hardware you own
→ Parallax: dataset prep for the next pretraining run is almost finished. Around 10T tokens of high-quality data. Apple M5 and DGX Spark support are locked in
→ Chutes is live on SayGM, and Tencent Hy4 is on its way
Full write-up below 👇

Chutes retweeted

In case you forgot (we haven't). There is no universe in which chutes exists without bittensor.
Expanding our OpCo's service and refocusing on a healthier subnet dynamic has some people confused, but it's very explicitly for strengthening the subnet.
teapawt.net/jon_durbin/status/2114… roadmap/plan ICYMI

Chutes is and always will be a bittensor project, chutes is bittensor, and bittensor is chutes 🫶
Reminder too that chutes team operates as a group of independent corporations with no CEO, and our funds are locked into a smart contract which pays our staking rewards to fund the team members.
If any subnet teams want assistance in setting up a similar smart contract situation or anything, we are happy to help.
Qwen3.8 2.4T A95B is live on Chutes.
It's the open-weights model behind Qwen3.8 Max, and the first Max-class model Qwen has released openly. 2.4T parameters in total with 95B active per token. 262K context, with always on thinking
Qwen publishes its scores under the Qwen3.8 Max name, the API version built on these weights:
- 86.6 on Terminal-Bench 2.1, ahead of Opus 4.8 at 84.6
- 81.9 on WideSearch, ahead of Fable 5 at 81.2 and Opus 4.8 at 72.9
Here's how Qwen describes the difference from Max: text only, with thinking always on and a 262K context against Max's 1M by default. Same price on Chutes for both
$2 per million input tokens, $6 out.

Qwen's published scores for Qwen3.8 Max, the API version built on these weights.
Try it here: chutes.ai/app/chute/chutes-q…

423