





Here’s this week’s Ritual Research Digest, a newsletter covering the latest in the world of LLMs and the intersection of Crypto x AI.
With hundreds of papers published weekly, staying current with the latest is impossible. We do the reading so you don’t have to.

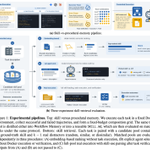
Skills stabilize execution by setting up the steps to run, the tool order, and what to verify. Across 528 matched task triples, 65.7% of skill cases were procedural, versus 4.5% knowledge injection. Skills crush execution-layer bugs; env-setup failures fall from 5.3% to 0.2%.

Follow us @ritualdigest for more on all things crypto x AI research, and @ritualnet to learn more about what Ritual is building.

Here’s this week’s Ritual Research Digest, a newsletter covering the latest in the world of LLMs and the intersection of Crypto x AI.
With hundreds of papers published weekly, staying current with the latest is impossible. We do the reading so you don’t have to.

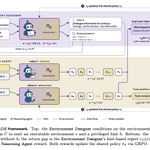
The method needs no critic or extra rollouts, only a training-time teacher pass. Qwen2.5-7B reaches 89.1% on ALFWorld; performance falls just 0.54 points per extra turn vs 2.91 for GRPO. Ablations show local gaps alone are not sequential credit.

Follow us @ritualdigest for more on all things crypto x AI research, and @ritualnet to learn more about what Ritual is building.
