

🛡️ Ex Technologia Libertas - Έλευθερία διὰ τῆς τέχνης - (Dec/Acc)
github.com/epappas
Joined September 2009
- Tweets6.9K
- Following4.1K
- Followers1.4K
- Likes5.7K


⚡🛡️ Evan Pappas retweeted

We are cooking some pretty interesting products around post training and inference @tplr_ai .
Would love to talk to engineers and researchers to understand where you bottlenecks are .
The rewards are my eternal gratitude and some credits.
DM if you're up for it.
⚡🛡️ Evan Pappas retweeted

Crucible, Templar's pre-training platform, has completed its first production end-to-end training runs. The latest trained an 8B model on 50.53B tokens across 48 distributed A100s, at an estimated $0.1202 per million tokens of GPU rental.
The run reached 48.3% effective MFU. At AWS p4de Capacity Blocks pricing, a 48-A100 cluster operating at the literature-derived 65% compute ceiling comes to an estimated $0.1686 per million tokens. Crucible's measured $0.1202 was about 29% lower after its low-bandwidth overhead.
The comparison excludes R2 storage and operations. The full writeup shows the method and accounting.
Blog: tplr.ai/publications/blog/in…

i'm opensourcing my playbooks; up and running automation to have a local RL & inference cluster on a GB10 (DGX Sparks, ASUS Ascent GX10, etc..)
github.com/epappas/gx10-clus…

⚡🛡️ Evan Pappas retweeted

Introduction to LLM Design & Covenant 72B: This week at the Ethereum & AI Engineering Group meetup I provided a 15 minute introduction to LLM design and then dived into the design and training of Covenant 72B; the largest model trained over the Internet.
youtube.com/watch?v=TlVQbiTd…


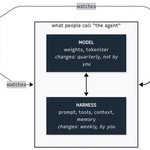
An agent loop that passes every test it has can run seven times slower the moment it shares a cluster, with nothing inside it changed.
open.substack.com/pub/hypera…

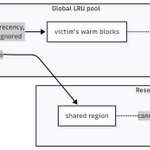
You cannot write this off as a naive scheduler either.
Continuum is built for multi-turn agentic serving, and its KV hit rate still fell from above 90% to about 60% once batches grew enough to create memory pressure.

1
28

⚡🛡️ Evan Pappas retweeted

[1/9] Edinburgh Decentralised Finance Summit 2026.
Tuesday 1 September, Royal College of Physicians of Edinburgh.
A full day on institutional DeFi, tokenisation, risk management, regulation and autonomous finance.
Around 25 speakers. 300 attendees.
luma.com/scotland-kgav

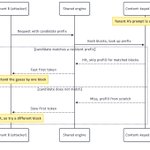
A KV cache hit skips prefill, so it comes back faster than a miss. Roughly 0.6s vs 4.3s on a repeated 10K-token prompt.
Time the response and you learn "has my neighbor prompted this exact text?" No access to their data required.

The confidentiality fix shipped a year+ ago: a per-tenant cache_salt, assigned server-side. If the caller picks it, an attacker just picks yours.
The fairness fix, reserved cache partitions, is still research. Not a stock engine flag.

1
37
Two runnable demos, red-teamed before I trusted them. One caught me faking my own leak: a partial block real vLLM never caches.
Fixed it, re-verified from scratch. Full writeup + code: hyperautomation.substack.com…
39
I stood up Llama-3.1-70B on two H100s. Four concurrent users in, the queue backed up while nvidia-smi showed the cards barely working.
I added two more H100s. Nothing changed.
hyperautomation.substack.com…

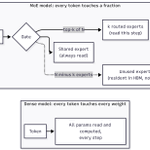
Bigger and cheaper aren't in tension. They're answers to two different questions, how much memory it needs versus how many bytes it moves per token, that a dense model happens to collapse into one.

1
21
Every number above comes from a script anyone can run, not a benchmark slide, adversarially reviewed for bugs before I trusted it.
hyperautomation.substack.com…
15