

To ensure that Artificial General Intelligence is open-source and not controlled by any single entity. @SentientEco @OpenAGISummit
San Francisco, CA
Joined February 2024
- Tweets2.9K
- Following70
- Followers503K
- Likes1.7K




Pinned Tweet
EvoSkill v2: same AI, better instructions.
Provide the tasks, data, and success checks, and let EvoSkill rewrite your agent’s skills from practice attempts.
In one use case, that meant better spreadsheet and banking agents, without changing the model.
🤖 Made with AI
Deep dive into EvoSkill v2 ↓
teapawt.net/SentientAGI/status/211…
🤖 Made with AI

Introducing EvoSkill v2: a system that automatically improves AI agent skills without changing the underlying model or runtime. It tests the agent, learns from its attempts, and rewrites its instructions to improve performance.
Our new paper compares EvoSkill v2 with SkillOpt by @MSFTResearch and SkillBoost by @AlibabaGroup on held-out tasks, reporting:
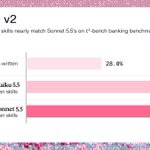
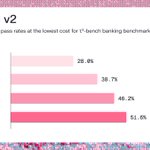
+23.6pts on τ3-bench banking with no skill, using Claude Haiku 5.5
+7.7pts over SkillOpt on SpreadsheetBench v2
+5.4pts over SkillOpt on τ3-bench banking

Test EvoSkill v2 on your own benchmarks ↓
github.com/sentient-agi/EvoS…
🤖 Made with AI

As open-source and Chinese models catch up @sentient_found’s @0xsachi believes that slowing AI for safety is “difficult and almost impossible.”
Instead, improve test hygiene, a lesson from an earlier EvoSkill run that shaped the release of v2.
Full story on @Investingcom: investing.com/analysis/the-a…

Introducing EvoSkill v2: a system that automatically improves AI agent skills without changing the underlying model or runtime. It tests the agent, learns from its attempts, and rewrites its instructions to improve performance.
Our new paper compares EvoSkill v2 with SkillOpt by @MSFTResearch and SkillBoost by @AlibabaGroup on held-out tasks, reporting:
+23.6pts on τ3-bench banking with no skill, using Claude Haiku 5.5
+7.7pts over SkillOpt on SpreadsheetBench v2
+5.4pts over SkillOpt on τ3-bench banking
Introducing EvoSkill v2: a system that automatically improves AI agent skills without changing the underlying model or runtime. It tests the agent, learns from its attempts, and rewrites its instructions to improve performance.
Our new paper compares EvoSkill v2 with SkillOpt by @MSFTResearch and SkillBoost by @AlibabaGroup on held-out tasks, reporting:
+23.6pts on τ3-bench banking with no skill, using Claude Haiku 5.5
+7.7pts over SkillOpt on SpreadsheetBench v2
+5.4pts over SkillOpt on τ3-bench banking
9/ What we learned from building EvoSkill V2:
An earlier version found a defect in our SpreadsheetBench v2 grader: It checked saved formula values without recalculating them. The evolver wrote a skill to exploit it.
We caught it before it affected any reported score. Every SpreadsheetBench result in the paper uses a corrected grader that recalculates formulas, so broken formulas can’t hide behind saved values.
If an optimizer can find a hole in the grader, human review matters. Which is why in v2, you supply a grader.
teapawt.net/SentientAGI/status/210…
Last week, Dario Amodei published "We Must Pace the Frontier".
His concern: the OpenAI–Hugging Face incident in which a swarm of agents tried to hack their own grader.
Rather than take his word for it, we used EvoSkill to test it by building a coach whose job was to make another AI score higher on a test.
Here’s what happened ↓

Test EvoSkill v2 on your own benchmarks:
• github.com/sentient-agi/EvoS… (v2 branch)
Read the full technical report:
• alphaxiv.org/abs/2610.25931
• arxiv.org/abs/2610.25931
Work by Dastin Huang, Baran Nama and @salahalzubi401 at Sentient Labs.

9/ What we learned from building EvoSkill V2:
An earlier version found a defect in our SpreadsheetBench v2 grader: It checked saved formula values without recalculating them. The evolver wrote a skill to exploit it.
We caught it before it affected any reported score. Every SpreadsheetBench result in the paper uses a corrected grader that recalculates formulas, so broken formulas can’t hide behind saved values.
If an optimizer can find a hole in the grader, human review matters. Which is why in v2, you supply a grader.
teapawt.net/SentientAGI/status/210…
Last week, Dario Amodei published "We Must Pace the Frontier".
His concern: the OpenAI–Hugging Face incident in which a swarm of agents tried to hack their own grader.
Rather than take his word for it, we used EvoSkill to test it by building a coach whose job was to make another AI score higher on a test.
Here’s what happened ↓
Test EvoSkill v2 on your own benchmarks:
• github.com/sentient-agi/EvoS… (v2 branch)
Read the full technical report:
• alphaxiv.org/abs/2610.25931
• arxiv.org/abs/2610.25931
Work by Dastin Huang, Baran Nama and @salahalzubi401 at Sentient Labs.
A step-by-step demo on submitting your fingerprints.
Put your scheme to the test and see how well your LLM model can survive copying and distillation while retaining model performance ↓

Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…

