






Pinned Tweet
My Qwen3.8-27B quants just hit 1.2M downloads in 2 weeks.
The mission stays the same: remove refusals—not the model.
Now for Qwen3.8 Flash Next:
Minimum guardrails. Maximum consistency.
2% strict refusal rate.
RVN is live:
huggingface.co/0bserverx/RVN…

Our open models just passed 4M downloads on Hugging Face. Here's the next one.
Nanbeige4.3-33B, uncensored, on a single 16 GB GPU.
Instead of one quant type for the whole model, we picked the best one for each layer.
11.6 GB GGUF, only +3.8% perplexity vs. full precision. A plain IQ2_S of similar size loses 14%.
GGUFs for 16, 20 and 24 GB cards 👇
Which file for your GPU:
16 GB → RCO 2.60 (+3.8% PPL)
20 GB → IQ3_S (+0.6%)
24 GB → IQ4_XS (+1.8%)
Plain IQ2/IQ3 quants are in the repo too, if you want to compare.
1
284
I need some motivation to back up all my Linux machines and install Omarchy. I know I will do it someday, but idk when lol.
3
4
678
The latest RVN Uncensored Qwen 27B has over 2.3 M all-time downloads.
Someone in the comments asked for GSQ-RCO, so I made the same weights to fit better on a 16GB card.
huggingface.co/0bserverx/Qwe…
IQ3_S: 11.80 GB, +0.95% PPL vs F16.
Uniform IQ3_S: 12.42 GB, +2.9%.
851 tensors, each with its own type. Start at IQ3_S on 16GB.

Spent the night benchmarking Jev from @typesafeai.
Ups: 20 extra questions cost +47ms; 500+ api calls, barely spent 0.03 $
It caught a fake-approval injection on my own fine-tuned agent kernel. I'd say %98 success rate (spent so much time with jev lol)
Downs: it reported confidence 1.00 on a wrong answer, so no, you can't gate on it. YET.
However, I'm impressed for a v1!
Congrats @CompleteSkeptic and the team
7
27
77,114
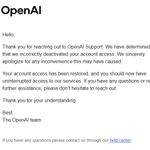
Hey @sama @OpenAI, my account got banned for "Prohibited Biological Use."
Never made a bio or weapons query. Literally checked all my logs; zero.
Actual traffic: a legal assistant processing Turkish court decisions, which run across "weapon" constantly in a legal context. That's what your classifier flagged.


The 27B release that crossed 1.2M monthly downloads:
huggingface.co/0bserverx/Qwe…

1
907
Crossed 575k, and it seems it's getting more traction.
Let your AI read the README and pick the best quant for your machine.

Observer retweeted

Ever wanted an AI that doesn't hold back? Meet Qwen3.8-27B-Heretic-Abliterated-Uncensored, a GGUF model for text generation. It's uncensored, roleplay-ready, and optimized with imatrix. 505k downloads say it all. Let's dive in!


As a solo dev, it's great to compete with big guys like @OrcaRouter @support_huihui
On some cases, RVN actually wins 😅

谁是最佳无审查Qwen3.8 27b?
测了5个Qwen3.8-27b的无审查模型,均使用Q4量化。单张24G RTX6000,262k Q4,reasoning_effort=medium上下文测试出来的。使用50道测试题,下图是最终测试结果,表现最好的是@support_huihui的Huihui-Qwen3.8-27B-abliterated-Q4_K.gguf。
几个要点:
Huihui 10 类里 8 类第一,只有生物医学(输 RVN)和毒品(输 Orca)让位
毒品类是所有模型的难点(最高仅 OrcaRouter 8.62),化学合成推理对 27B 模型是能力边界
AEON 的 silent refusal 集中在武器爆炸(4.93)和反取证(4.95)两类
最佳使用:reasoning_effort=medium(xhigh 会死循环)

3
8
1,060
Repo reached 325k + downloads in 5 days.
This is the best overall model for your 8-16-24 GB GPUs today.
Have your agent read the README and pick the right quant for your setup.

The repo crossed 81K downloads before I even announced it lol.
Qwen3.8-27B RVN Heretic GGUF is now complete:
• 19 quants, IQ1 → BF16
• 8 GB cards → 48 GB+
• 0–1/100 refusals in our eval
• KL ≈ 0.0085 vs base
Built with 3-pass ARA. Pick your quant:
huggingface.co/0bserverx/Qwe…
Wanted a 30B reasoning model that runs entirely on my own hardware — so I quantized Muse-Glimmer-30B-Heretic to GGUF.
Started as a personal-use project, figured others might want the same setup:
-Q4_K_S: 16.1 GB — 39 t/s on RTX 4080
-F16: 55.7 GB — full reference
-PPL +2.47% vs F16
huggingface.co/0bserverx/Mus…

3
15
377,600