

integrations at @HeyMiloAI evals | world models | mechanistic interpretability
Joined August 2026
- Tweets694
- Following6.6K
- Followers1.4K
- Likes32K



Pinned Tweet
For about $5 and 5½ minutes you can strip almost all the guardrails from a 12B Gemma 4.
Model: huggingface.co/pasangimhana/…
Report: pasangimhana.github.io/resea…
pasan retweeted

You will notice that Gemini Carbon thinks differently than Claude and GPT. It often comes up with entirely different but more clever solutions than competitor models.
This is precisely because we never distilled other models. Distilling other models creates a poor imitation rather than unique intelligence.


pasan retweeted

I gave Fable 5.2 access to Midjourney and gpt-image-2.6 and let it rip on a 3D platformer. It created concept art, character sheets, textures, modeled in Blender, and came up with a fully playable level. The level design needs a bit of tuning, but it's insane that this was just 1 day of work
pasan retweeted
To celebrate Mistral Vibe + Le Chonk becoming the world’s best open model-harness duo, we’re making Vibe free in Europe for the first 3 months.
(Yes, it’s actually better than GLM / DeepSeek at coding).
Use code LECHONK via link in 🧵. Limited time, first-come, first-served.


The Return of the King

Over the past week, I’ve been overwhelmed by the love and support of friends, industry colleagues, and people I've never met. Thank you to everyone who has shown kindness to my family and me. It means the world to me.
I came to the United States 53 years ago, and becoming an American citizen is one of the greatest gifts and proudest moments of my life. NVIDIA has been my life’s work. Building it into the company it is today alongside my colleagues has been a privilege and an honor. Nowhere but in America could a company like NVIDIA be possible. I love our country, and I love NVIDIA.
I did not live up to the standards expected of everyone at NVIDIA, and I have made serious mistakes in my personal life. I created problems for the Board that I deeply regret. I own my mistakes completely, and I am committed to cooperating with the Board’s independent investigation.
Since my departure, I’ve seen an outpouring of calls from NVIDIA’s employees, investors, business partners, and customers for me to return as CEO. Many continue to reach out to me directly as the company navigates complex technology, market, competitive, and geopolitical dynamics. NVIDIA is a once-in-a-generation company. If the Board of Directors decides that my return is in the best interest of our shareholders, our employees, the company, and America, I would be honored to answer these calls and return as CEO.
Thank you again to everyone who has shared their good wishes. I am profoundly humbled by your support. To my family: I love you, and I will spend the rest of my life being worthy of yours.
Jensen
49


pasan retweeted
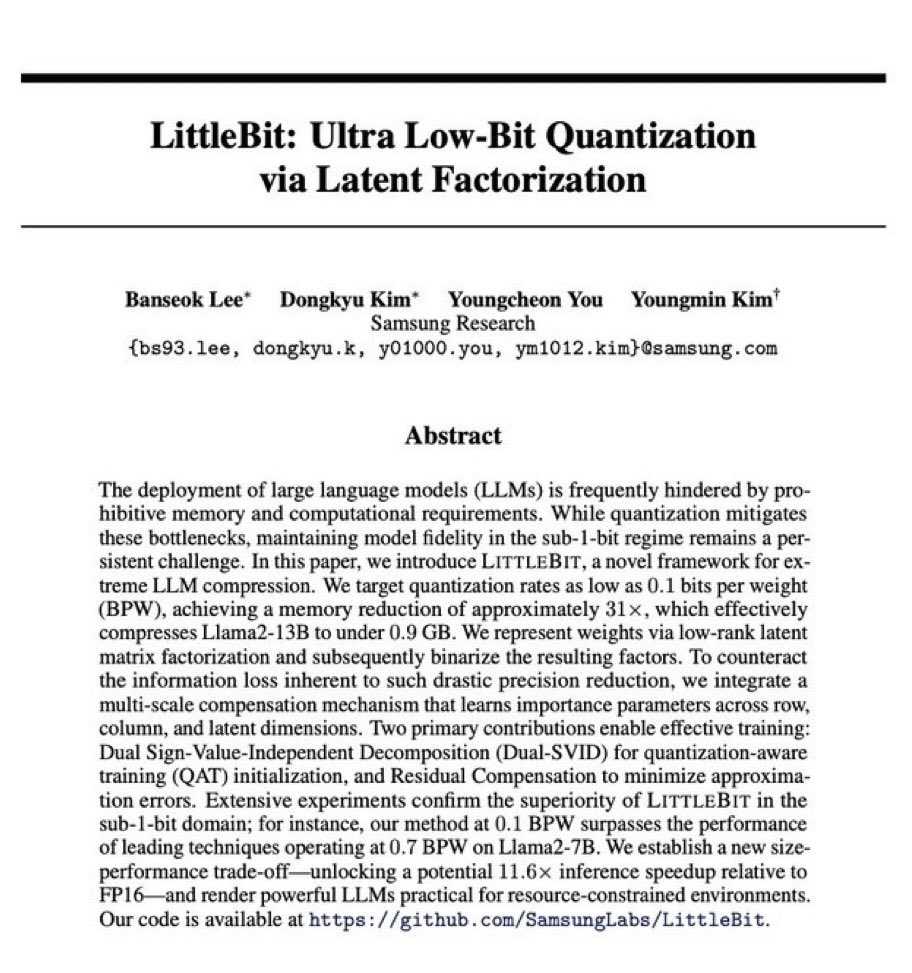
Samsung open-sourced a method that shrinks 13B parameter LLM into less than 1 GB.
The method is named "LittleBit"
Normally, AI weights are stored as regular numbers. LittleBit instead uses latent factorization to compress them below 1 bit each.
Some setups get all the way down to 0.1 bits per weight.
The architecture is where it gets wild.
Once a model is compressed this far, most of the math goes away.
LittleBit doesn't make the hardware grind through expensive floating-point multiplications. It runs the core computation with a simple bitwise XOR.
Heavy matrix math becomes simple sign flips.
What this means for deploying models:
• Up to 11.6x faster inference than standard FP16 models.
• Much less memory needed, and much less bandwidth to load the model.
• Holds up even below 0.5 bits, where older compression methods completely break down.
This is more than a smart optimization.
It's a roadmap for running huge, advanced AI locally on cheap, low-power hardware.
pasan retweeted

All of my work is so trivial that I cannot tell a difference between fable 5.2 and opus 5.5 high
sleep has an inverse correlation with success

AI IS GIVING ELON, SAM AND DARIO SLEEPLESS NIGHTS
"losing sleep over the threat of AI danger" - Elon Musk, 2023
"I haven't had a good night of sleep since ChatGPT launched" - Sam Altman, 2025
"I cannot legitimately say that I sleep" - Dario Amodei, 2026
how has your sleep been recently? 😅
3
5
487


pasan retweeted

Today on Connectionism: how we trained Inkling 2 Small with a native 4-bit forward pass on @nvidia GB300s, from the first pretraining step through the final RL rollout, one of the many improvements across the stack that took pretraining from weeks to 68 hours.

Training with fewer bits is faster, but quantization error can interfere with learning.
Today on Connectionism, we detail how we trained Inkling 2 Small with a native 4-bit forward pass from the first step of pretraining through the final RL rollout.
thinkingmachines.ai/blog/end…


small cognitive core + a lot of thinking

The race for LLM "cognitive core" - a few billion param model that maximally sacrifices encyclopedic knowledge for capability. It lives always-on and by default on every computer as the kernel of LLM personal computing.
Its features are slowly crystalizing:
- Natively multimodal text/vision/audio at both input and output.
- Matryoshka-style architecture allowing a dial of capability up and down at test time.
- Reasoning, also with a dial. (system 2)
- Aggressively tool-using.
- On-device finetuning LoRA slots for test-time training, personalization and customization.
- Delegates and double checks just the right parts with the oracles in the cloud if internet is available.
It doesn't know that William the Conqueror's reign ended in September 9 1087, but it vaguely recognizes the name and can look up the date. It can't recite the SHA-256 of empty string as e3b0c442..., but it can calculate it quickly should you really want it.
What LLM personal computing lacks in broad world knowledge and top tier problem-solving capability it will make up in super low interaction latency (especially as multimodal matures), direct / private access to data and state, offline continuity, sovereignty ("not your weights not your brain"). i.e. many of the same reasons we like, use and buy personal computers instead of having thin clients access a cloud via remote desktop or so.
2
129
