

French AI lab. We design Efficient Language Models (ELM): the right model for each task, at the right cost, on your infrastructure.
Paris, France
Joined April 2026
- Tweets20
- Following1
- Followers11
- Likes3




Nos intervenants :
👉 Théo Hubert, CTO d’AlphaEdge : AlphaIDP lit, classe et extrait chaque pièce du dossier.
👉 Virgile Augendre, CEO d’Evarist : Soma relie les pièces pour trouver qui contrôle vraiment la société.
Inscription 👉 eu1.hubs.ly/H0z5r_l0

Au programme :
📄 Extraire automatiquement la donnée des documents de gouvernance avec AlphaIDP.
🕸 Cartographier les liens capitalistiques en langage naturel avec Soma, le GraphRAG d’Evarist.
⚖️ Distinguer détention et contrôle effectif, avec une analyse traçable.
👀 Un bonus réservé aux participants présents en direct.
Inscription gratuite 👉 eu1.hubs.ly/H0z5r_l0
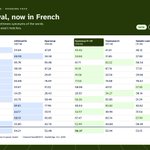
SOTA sparse retrieval, now in French. We’re releasing Sparseup-fr-v0 on Hugging Face, our second open-source release this year.

On a cleaned NanoBEIR-fr (13 datasets): 56.37 average, the best of the open-source French sparse embedding models we evaluated. Best on 8 of 13 datasets, +7.9 points over BM25.
It’s a V0: our Lead Data Scientist @BdsLoick replicated @Linkup_platform’s recipe, built on @LightOnIO's work, to check it transfers to French. It does. A new version is already in the works. Model, benchmark and blog post: huggingface.co/alphaedge-ai/…

Yesterday was about the top score. Today, the bigger picture: all three AlphaDigit v2 models land in the top 5 of olmOCR-Bench.
Even our lightest, AlphaDigitFast v2, passes 83.0% of tests, ahead of 5 of the 7 other systems evaluated.
Full thread ↓


Our OCR model AlphaDigitMax v2 scores 89.4% on olmOCR-Bench (@allen_ai): the best overall score among the 10 systems we evaluated, ahead of Chandra (86.9%) and Mistral OCR (83.8%).
All three AlphaDigit v2 models rank in the top 5 🧵

Full report (protocol, per-category results, list of corrections): bit.ly/4ennNG3
Models on Hugging Face: huggingface.co/alphaedge-ai
Overall scores on 1,402 PDF pages and ~8,400 pass/fail tests.
The biggest gap is on the hardest category for every system, old & degraded scans: 60.6% vs 51.2% for the next best (+9.4 pts).
Tables: 92.9% (+3.0 pts).

📄 Tomorrow: we publish the evaluation of our OCR models, AlphaDigit v2, on a public benchmark: protocol, results by category, and our limits.
Want to see it first? Our Discord gets it before anyone else 👇
discord.gg/zHW6aWFve