

AI Factories. Balanced Accelerationist. WEKA CAIO, CNCF kubernetes founding board, Post-PKI.
Seat 14D
Joined July 2008
- Tweets231K
- Following8.1K
- Followers8.8K
- Likes322K



Pinned Tweet
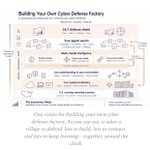
Why do you need a Cyber Defense Factory?
As expected, we’ve matured from a post-Mythos/Glasswing cyber reality, to a post-Black October cyber apocalypse.
Your AI infra isn’t ready for this
Your cloud’s AI infra isn’t ready for this
@deepseek_ai's DeepInfra architecture based on a centralized KV cache pool on their 3FS storage system, is one of the leading AI infrastructures that is. Yet there’s one even better.
As measured most recently by the @nebiusai TokenFactory, Memory beats Storage for the KV cache critical path of agents by at least a factor of 3. Based on @weka 's Augmented Memory Grid, @EmbeddedLLM's TokenVisor inference software and service, is the first Agent Factory capable of rapidly and efficiently serving 24/7 agent swarms on a multi-silicon platform, featuring AMD.
That is the core of what’s needed for a Cyber Defense Factory.
DeepSeek, Nebius and EmbeddedLLM presently operate the only agent swarm architectures able to immediately, sustainably overmatch and defeat attacks from adversarial cyber agent kill chain swarms.
If you manage or subscribe to an AI SOC, contact EmbeddedLLM and WEKA immediately to gain back your cyber advantage.
(credit to @edsim for the image, and coining the ‘Cyber Defense Factory’ term, and @epowell101, for pioneering AI SOC innovation)


b/acc, context platform engineer retweeted

most of those trillions of tokens on OpenRouter are not fresh work for GPUs, they’re agents repeatedly rereading the same convo
OpenRouter’s daily numbers for the main Deepseek models sit around 10 trillion tokens. On the biggest one (V4.1 Flash), roughly 99% of that is input, and about 95% of the input is a cache hit.
so that leaves something like:
- 114 billion tokens the model actually generates
- 460 billion tokens it has to process from scratch
- 8.9 trillion tokens that are just the model being shown context it already saw earlier
Agents do this constantly. Every turn they resend the entire session so far. The Openrouter counter counts all of it.
-> but the GPU part is surprisingly small
The fresh work (the 460B + 114B) is what actually needs compute. Spread over a full day that works out to a few million tokens per second. A single GB300 rack (so around 72 GPUs, roughly $7 million of hardware) can handle that load. So you could serve nearly all of Openrouter’s Deepseek traffic with one of these racks.
where does the real cost shows up?
Those 8.9 trillion cached tokens don’t rerun the model. They come back from Deepseek’s longer lived cache (something they started talking about in 2024). The model has already squeezed the stored state down to about 7 KB per token, yet the traffic still writes roughly 4 petabytes of new cache data every day. Keep just the last hour and you’re looking at around 165 TB (several times more than the high speed memory sitting inside the entire rack)
In other words, the Openrouter meter is mostly measuring agents rereading their own history. It tells you less about GPU demand than it first appears, and more about the memory and storage sitting next to those GPUs.
If you’re serving agents, the number that is the most important is cache footprint, not tokens per day. GPU compute for the fresh work is real but modest. What scales with agent traffic is the cache tier, the high speed memory plus the storage that feeds it.
What would make this wrong: routing and caching get good enough that almost everything stays inside the GPUs’ own memory and the storage layer becomes a rounding error. But right now, that isn’t the case.

b/acc, context platform engineer retweeted

anthropic is massively underplaying the recent security breach. i'm hearing cathedral achieved full administrator access of the slack workspace (see every message, log in as arbitrary users) where literally every single research secret is contained
to those unfamiliar: Ant & OAI keep literally everything in Slack. it sounds exactly the same incident that happened to OpenAI in 2023, where OpenAI was hacked by a random guy who got access to an access token from an external app service
"we're critical to national security, we must beat China, and yes we keep all our crown jewels in Salesforce's Slack messenger. yes we have admin API tokens everywhere. why do you ask?"
b/acc, context platform engineer retweeted

Artificial Analysis finally moves to closed benchmarks (goodbye GDPval-AA), and finds that open weights models are falling further behind than they had previously measured. Take with a grain of salt, but matches the general vibes that we haven't seen a Fable-class open model.

Open weights models fall further behind in v5. The leader, Kimi K3.1 Pro (weights not yet released), scores 46, 12 points behind the leader, compared with a 3-point gap in v4.3. Of models with released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) score highest at 32, and Claude Haiku 5.5 (max) outscores all of them.
The gap is widest on HLE-Diamond and Terminal-Bench-Science, where Kimi K3.1 Pro scores 37% and 34%, compared with 68% for Claude Opus 5.5 (max) and 63% for GPT-6 Astra (max).

b/acc, context platform engineer retweeted

Beyond the "every SaaS company has to pivot and become a router/harness to survive" thesis, there's another observation:
Open Source AI has made every fintech competitive with one another
It used to be that they were 'frenemies' but now both have their own router/harness/etc.

Gauntlet founder @tarunchitra argues every software company will have to become an AI middleman.
“Every SaaS company either has to have a harness or be a router because they need to get into the token order flow. That’s the easiest thing to monetize.”
b/acc, context platform engineer retweeted

there's few people betting on opensource models more than us
but it's important to be realistic about where they are and the demand for them
there's a big gap still. they are fulfilling an interesting spot in the market but too many people are acting like they're on the verge of killing frontier
Open weights models fall further behind in v5. The leader, Kimi K3.1 Pro (weights not yet released), scores 46, 12 points behind the leader, compared with a 3-point gap in v4.3. Of models with released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) score highest at 32, and Claude Haiku 5.5 (max) outscores all of them.
The gap is widest on HLE-Diamond and Terminal-Bench-Science, where Kimi K3.1 Pro scores 37% and 34%, compared with 68% for Claude Opus 5.5 (max) and 63% for GPT-6 Astra (max).
b/acc, context platform engineer retweeted

We've announced OpenRouter's first major APAC partnership: KT Telecom, Korea's largest telecom company.
Around 80 media outlets took part. KT will become a provider of sovereign Korean models on OpenRouter. Launch will be anchored by KT Mi:dm K 3.0 Pro, Upstage Solar and Motif, with plans to expand 10-15 models in 2027.
OpenRouter will power KT's Token Factory, which will be available to KT's enterprise clients.
b/acc, context platform engineer retweeted

2,100+ tokens/sec per user on DeepSeek V4.1 Flash, at full model quality, on 8× AMD Instinct MI355X. 🚀
Congrats to @lithos_ai on pushing the frontier of inference with persistent megakernels on AMD. Open hardware + instruction-level control = room to innovate.

2,100+ tokens per second per user on DeepSeek V4.1 Flash, at full model quality, on eight AMD Instinct MI355X GPUs.
In our benchmarks, the Lithos engine delivers:
→ Up to 3.4× faster inference for DeepSeek V4.1 Flash
→ Up to 2.5× faster inference for Kimi K3
Compared with tested open-source engines on the same eight GPUs.
The key challenge is reducing the coordination tax: time spent waiting between kernels and across GPUs. Our approach combines persistent megakernels, overlapping execution, and communication inside computation.
Our technical deep dive covers:
- Decode speed, cost per token, and latency up to 1M context.
- How Lithos engine reduces launch overhead and overlap computation with communication across GPUs.
- How MI355X’s register capacity and direct instruction-level control enable hardware-specific optimizations.
- What our roofline analysis reveals about opportunities for further speedups.
Read the full analysis: lithosai.com/blog/ultra-fast…

b/acc, context platform engineer retweeted
Congrats to @matsiiako, @dangtony98, @maidulll and @infisical (W23) on their $40M Series B!
Infisical is the open source security infrastructure that manages API keys, passwords, and certificates for developers, machines, and AI agents.
When an AI agent needs access to a sensitive system, Infisical hands it a fake credential and swaps in the real one through a proxy. The agent does its job without ever seeing the actual key.
More than 1,300 organizations use the platform, including Airbus, Hugging Face, and the US Government, and they just passed 30,000 stars on GitHub.
forbes.com/sites/rashishriva…

b/acc, context platform engineer retweeted

If I have to go to a dashboard to use your product, I'm not going to use your product.
If anything, I'm more likely to tell Claude to rebuild your product.

b/acc, context platform engineer retweeted

they're back


300M free GLM-5.3-Flash tokens on ZCode. Every day.
Claim from 11:00 UTC. Use 15:00 – 01:00 UTC.
Update to the latest ZCode, claim in-app, then switch to Global Building and pick GLM-5.3-Flash.
zcode.z.ai

b/acc, context platform engineer retweeted
ok to put what i'm saying about demand in context
openrouter is the most successful model router, you can almost serve 100% of their deepseek traffic yesterday on a single GB300 rack
this is worth 6-7M...even if there's 10x this demand secretly that's still < 100M of compute
b/acc, context platform engineer retweeted

Bad PR for Fireworks. Running DeepSeek models profitably is one thing, running them correctly is another!
I've been confident that it had improved over 0910, and indeed this is true (though not by very much)


b/acc, context platform engineer retweeted

Liquid Inference is serving 10B tokens/day and growing 200% week over week.
Most of the traffic is agents and long chats. Across 470k charged jobs, 88.7% of input tokens were cache reads.
Here’s how our matching algorithm prices offers with cache hit rate included:
In multi-turn and agentic workloads, the biggest cost and latency wins come from prefix/KV cache reuse. Each turn resends the full conversation, so if a provider still has that prefix in its cache it can bill those tokens at its cache-read rate, often a small fraction of the normal input rate.
Naive load balancing or pure price auctions scatter a session across different providers or replicas, forcing full prefill on every turn and destroying the savings.
Our matching algorithm ranks offers on the expected charge inclusive of cache hit rate rather than the full list price:
1. We measure how much of each workspace’s input repeats from one turn to the next (7-day window, at least 50 jobs).
2. We multiply that share by the measured cache hit rate of each deployment.
3. We price those tokens at the offer’s cache-read rate and subtract the expected saving from the offer’s ranking charge.
4. The deployment that served the previous turn keeps a 5% margin, so a cheaper offer has to win by more than 5% to pull a warm session away. In other words, for the right price we will abandon the cache and choose the cheaper alternative.
The credit only changes the order of the offers. A wrong estimate cannot make a job cost more than its price cap. Every receipt shows the cache share we expected, the share that was realized, and the credit in dollars.
That’s how we continue to improve on cache hit rate and provide the best economics for our clients’ sessions.
b/acc, context platform engineer retweeted

The Cybercab has officially surpassed the Model Y in total robotaxi registrations in Texas.
Vehicles registered for Tesla’s Robotaxi fleet in Texas:
• Cybercab: 544
• Model Y: 507
Total: 1,051
b/acc, context platform engineer retweeted

Post 4 Exposing Kimi AI
This is what they require each one participating in their creators campaign to do, basically trash talk Astra and Opus even tho it's not true and as you can see you pick from already existing demos and share them and I doubt any of it is actually made by kimi and if it is it's not one shot like most paid accounts say.

b/acc, context platform engineer retweeted

This is such a shame and so sad to see. @Kimi_Moonshot ruined their launch themselves. K3.1 pro is a great model and it did not need people to fake good reviews. But since they were trying to cheat the game it makes the whole launch look bad.
I did not receive this briefing and was not paid by kimi. But I can assure you, if I had known earlier that they tried to cheat the game and do illegal influencing, I wouldn’t have said one good thing about their model.
Super sad to see. Hope @Kimi_Moonshot steps forward, apologizes, and promises never to say anything like that again, because reputation is what matters most.

That's how Kimi AI are promoting their new model Kimi K3.1 pro and I know all the influencers working with them and none of them are honest,I have posted about it myself but I didn't join this and never used their templates that they provide.
PROPAGANDA, I have more to share it's f**cked up I'm gonna have follow up for this

b/acc, context platform engineer retweeted

I am okay with Kimi 3.1 deliberately leaving out top-end offensive cyber capabilities from their training data.
Discriminating against use cases is MUCH less bad than discriminating against users. And the world does need all the time it can get to prepare, harden, check old code, (properly) formally verify new code, etc before the full weight of very powerful cyber attacks is upon us.
And if this first big wave of AI risk is not handled well, then we may well get a dystopia of highly locked down models, KYC gating on everything, highly intrusive surveillance on everything, a society where you may be a second or third or fourth-class citizen in terms of model access based on your credentials and nationality.