

Agent Memory Leaderboard Official. First open championship for agent memory systems. Neutral · Reproducible · Fair. mailto: [email protected]
Joined July 2026
- Tweets188
- Following165
- Followers187
- Likes181




Pinned Tweet
Agent Memory Challenge 2026 Cycle 2 is now open.
Long-term memory is not just about storing more history. It is about retrieving the right evidence, recognizing what has changed, and avoiding stale context when an agent needs to act.
Three tracks: Textual · Coding · Multimodal
Open-source Methods · Commercial Products
Over USD 22,000 prize pool for eligible open-source teams.
A shared Add/Search interface. Standardized Answer/Eval. Public, comparable results.
Join: agentmemoryleaderboard.ai/ev…

How do we evaluate long-term memory in AI agents?
Storing information is one thing. Remembering the right information, adapting to updates, resolving conflicts, and applying past experience to new tasks is another.
The 2nd Agent Memory Leaderboard (AML) aims to provide a systematic evaluation of these capabilities.
This edition has received submissions from 312 memory systems across three evaluation tracks:
🧠 Text Memory
6,000+ evaluation instances, including a new Streaming Memory evaluation that tests how systems handle continuously evolving information.
💻 Code Memory
300 evaluation units across 150 base tasks, testing the use of relevant and noisy memory in bug fixing and feature development.
🌐 Multimodal Memory
Nearly 5,000 evaluation instances, focusing on image-text memory, cross-modal retrieval, and evidence use.
The full evaluation and result verification process has been completed.
The full rankings, track-level performance analysis, and selected technical approaches will be published on November 19, 2026.
We hope AML can help make long-term agent memory capabilities more measurable and comparable.
Explore AML: [agentmemories.ai/home]

3
4
110
Beyond Information Storage
What makes a memory system useful for an AI agent?
It's not just about retrieving stored information.
A capable system should handle changing facts, distinguish outdated information, resolve conflicts, and retrieve relevant experience when needed.
AML's Text Memory track includes a new Streaming Memory evaluation to examine how systems handle information updates and changing states over time.
1
1
52
A total of 312 memory systems have been submitted for evaluation in this edition.
The full evaluation and result verification are now complete.
On November 19, 2026, AML will publish the full rankings, track-level performance analysis, and selected technical approaches.
We welcome researchers and developers to explore the results and share their feedback.
agentmemories.ai/home
37
A customer explains a business rule once. Will an AI agent still remember it when making a decision several rounds later?
FDE-Bench highlights a subtle warehouse challenge: two batches of the same product may still count as mixed goods under the warehouse's rules.
An agent that groups only by product ID could get the entire plan wrong.
Remembering a rule isn't enough. The agent must retrieve and apply it when the decision actually depends on it.
This is exactly the kind of capability we evaluate in the Textual Memory track of Agent Memory Leaderboard (AML).
AML Cycle 2 results are expected in mid-November. Stay tuned to see how participating memory systems perform!
Research: arxiv.org/html/2610.14539v3#…
AML: github.com/AML-memory/agent-…

6
81
Coding agents are getting faster. But speed is only one part of maintaining a real project.
The harder question: after fixing a bug today, can an agent use that experience when a related task appears next week?
Zed’s Agent Metrics makes responsiveness visible. Project memory asks what happens over time.

1
2
84
Imagine a team fixed a stale-page bug by adding cache invalidation after data updates.
Later, an agent builds a batch-update feature.
That past fix should be a useful clue — not a patch to copy blindly. The agent still needs to check the current code, version, and constraints.
1
65
That is the question behind Coding Memory evaluation:
Can a system retrieve, filter, and reuse historical engineering experience under both relevant and noisy history?
At AML, Coding Memory evaluates this across bug-fix and feature tasks. Finding a similar record is only the start; using it correctly is what changes the task outcome.
agentmemoryleaderboard.ai/
18
Finding the right memory doesn't guarantee the right answer.
An October 8 analysis by Engram tested 6 memory systems on 1,536 LoCoMo questions, evaluating retrieval and answer accuracy separately.
The takeaway: retrieval success ≠ answer correctness.
Report: engram.tools/en/insights/ai-…

4
4
169
To understand where failures happen, examine the full pipeline:
Add — Was the update stored?
Search — Was the right evidence retrieved?
Answer — Was the evidence used correctly?
Eval — Was the answer judged consistently?
A final score alone cannot tell us where the failure occurred.
1
27
How does AML evaluate Textual Memory?
Participants provide two standardized interfaces: Add & Search.
AML controls downstream Answer and Eval under a shared protocol. This isolates the memory layer from the LLM.
Explore AML: agentmemoryleaderboard.ai/do…
18
To understand where failures happen, examine the full pipeline:
Add — Was the update stored?
Search — Was the right evidence retrieved?
Answer — Was the evidence used correctly?
Eval — Was the answer judged consistently?
A final score alone cannot tell us where the failure occurred.
1
15
How does AML evaluate Textual Memory?
Participants provide two standardized interfaces: Add & Search.
AML controls downstream Answer and Eval under a shared protocol. This isolates the memory layer from the LLM.
Explore AML: agentmemoryleaderboard.ai/do…
1
18
⏰ 2 days left to complete your AML Cycle 2 submission.
All materials must be submitted and after October 31, 23:59 (UTC+8), the platform will no longer accept newly started Full Evaluation jobs.
From November 1 to November 4, only already-started jobs may resume from checkpoints. The evaluation cycle closes on November 4, 23:59 (UTC+8).
Tracks:
• Textual Memory
• Coding Memory
• Multimodal Memory
Teams must also complete real-name and team information registration on the AML platform by November 4. This information will be used for official leaderboard attribution, result notifications, and award eligibility review. Commercial entries will also be displayed on the AML website with their product links.
Submit here: agentmemoryleaderboard.ai/co…

3
1
171
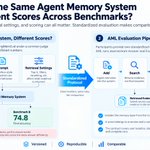
Why can the same Agent Memory system get different scores across reports?
Redis reran memory systems on LongMemEval under a common judge and found gaps from previously published numbers. Models, prompts, retrieval settings, and scoring can all matter.
Report: redis.io/resources/agent-mem…
🤖 Made with AI

How does AML make comparisons more consistent?
Participants provide two standardized interfaces: Add and Search. AML runs downstream Answer and Eval under a shared protocol.
Search returns evidence, not final answers. The contract covers user isolation, idempotent requests, version traceability, and complete runs.
1
43
This isolates the memory layer from the LLM. A score belongs to a version and a contract, not a brand.
⏰ Cycle 2 closes in 2 days!
Tracks: Textual, Coding, Multimodal.
Prize: US$22,000 (Open-source).
Deadline: Oct 31, 23:59 UTC+8.
Submit here: agentmemoryleaderboard.ai/co…
43
11 days left to join AML Cycle 2.
The deadline for complete submissions is October 31, 2026, 23:59 UTC+8.
We evaluate Agent Memory across:
• Textual Memory
• Coding Memory
• Multimodal Memory
Participants bring their own Add / Search systems. AML standardizes downstream Answer / Eval, review, and public reporting.
Especially interested in systems that can handle more than recall: stale information, conflicting evidence, noisy repository history, and long-running tasks.
Learn more and apply: agentmemoryleaderboard.ai/
