

Building generalist agents that scale @BerkeleySky
San Francisco, CA
Joined January 2025
- Tweets86
- Following10
- Followers2.8K
- Likes148





Meet Evo, a general-purpose software optimizer built to automate entire engineering practices. 🤖
Give Evo a codebase, an objective, and constraints. It figures out what to optimize, directs coding agents to implement changes, runs experiments in parallel, and keeps only verified improvements.
Evo continuously creates and solves tasks, using experimental feedback to decide what to work on next—all without human steering.
We're starting with LLM serving, where Evo has already surpassed expert-tuned vLLM performance on NVIDIA B300.
Our vision is self-improving software that gets better around the clock.
ML systems engineering is just the beginning.

Our AI system, Evo, surpassed the expert-tuned vLLM serving recipe for DeepSeek-V4.1-Flash on NVIDIA B300 in just 3.5 days—starting from vLLM's Day-0 model support, with no human steering and no access to web & history.
Coding agents are getting better at solving individual tasks and PRs. With Evo, we're going after something much bigger: Continuously self-improving software systems that automate software engineering.
Our thesis: much of software engineering can be reduced to constrained optimization problems.
Give Evo a codebase, an objective, and constraints. It decides what to optimize next, scales coding agents to execute, runs experiments in parallel, and keeps only verified improvements.
The key is closing the loop between creating tasks and solving them. Every result informs what Evo should attempt next, enabling continuous optimization without human intervention.
We started with LLM serving.
On DeepSeek-V4.1-Flash with agentic coding workloads (AgentX), Evo outperformed the expert-tuned vLLM recipe on NVIDIA B300:
• +15% p90 interactivity
• +5% throughput
• 5-8× less time to surpass expert performance
ML systems engineering is just the beginning.
Agentica Project retweeted

Excited to see @peano_ai run full-parameter RL for @XiaomiMiMo 310B MiMo-V2.6 on TPUs, across 1,000+ TPUs. 🚀🚀
vLLM drives the rollouts, bitwise-matched with the trainer in validation. All 310B params move across the ICI fabric in under 2s.
🔗 peano-labs.ai/blog/scaling-m…

We enable full-parameter RL on TPUs: MiMo-V2.6 at 310B, plus other stable training runs of 1,000+ steps across 1,000+ TPUs.
With JAX, scaling up is a config change, not a rewrite.
We built on that with optimized vLLM inference for faster rollouts and full bitwise trainer–sampler agreement in validation.
Trainer and sampler share one TPU ICI fabric. All 310B MiMo-V2.6 parameters transfer in <2 seconds.
RL infrastructure has become increasingly mature and commoditized, particularly on GPUs.
At Peano AI, we’re extending that experience to TPUs—building infrastructure that makes RL training practical at scale, while also pushing TPU inference toward high-throughput, low-latency serving.
Come check out what we’ve been building 🛠️
We enable full-parameter RL on TPUs: MiMo-V2.6 at 310B, plus other stable training runs of 1,000+ steps across 1,000+ TPUs.
With JAX, scaling up is a config change, not a rewrite.
We built on that with optimized vLLM inference for faster rollouts and full bitwise trainer–sampler agreement in validation.
Trainer and sampler share one TPU ICI fabric. All 310B MiMo-V2.6 parameters transfer in <2 seconds.
Agentica Project retweeted

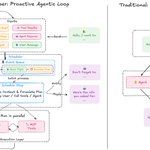
The next generation of AI agents is proactive (think ChatGPT Pulse).
Instead of sitting idle, waiting for your next command, they’re:
⚡ Always-on
🧠 Context-aware
🤝 Actively engaging
🔄 Continuously working in the background
We’re building this future with Pepper🌶️— an open-source, real-time, event-driven architecture giving developers the infra to create powerful new agentic applications.
Excited to see what this will enable.

Introducing Pepper🌶️! An open-source, real-time, event-driven architecture to power the next generation of proactive agents.
Tired of static reactive chatbots? Pepper enables agents that anticipate your needs, actively engage, and work continuously in the background (think ChatGPT Pulse).
🌐 Blog: agentica-project.com/post.ht…
💻 Github: github.com/agentica-org/pepp…

Agentica Project retweeted

We reversed engineered Poke and Pulse and build an open source version named Pepper🌶️!
Read our blog at
agentica-project.com/post.ht…
and find out how you can build your own proactive agent
Introducing Pepper🌶️! An open-source, real-time, event-driven architecture to power the next generation of proactive agents.
Tired of static reactive chatbots? Pepper enables agents that anticipate your needs, actively engage, and work continuously in the background (think ChatGPT Pulse).
🌐 Blog: agentica-project.com/post.ht…
💻 Github: github.com/agentica-org/pepp…
(4/n) The glue that holds this real-time, multi-agent system together is the Context Store. Think of it like a feature store for predictive ML, but for real-time orchestration.
It manages:
1. State: Allows agents to persist and share context.
2. Serving: Publishes fresh data for agents to act on.
3. Orchestration: Triggers downstream actions across components.
(5/n) With Pepper, we built a personal assistant that proactively fetches and summarizes emails, provides context, and follows up on tasks in the background.
We're open-sourcing Pepper to advance the next generation of proactive AI. Build the future with us! 👇
🌐 Blog: agentica-project.com/post.ht…
💻 Github: github.com/agentica-org/pepp…
Congrats to Tongyi Lab on releasing a beast—a SOTA 30B DeepResearch agent that surpasses OpenAI DeepResearch across benchmarks (HLE, GAIA, BrowserComp)!
We’re proud that rLLM powered its RL post-training. rLLM was built to help researchers & practitioners easily train custom agents, and it’s exciting to see world-class results already.
rLLM v0.2 is now in preview, with an official release coming soon. Stay tuned for more groundbreaking work built on rLLM!
rLLM: github.com/rllm-org/rllm


1/7 We're launching Tongyi DeepResearch, the first fully open-source Web Agent to achieve performance on par with OpenAI's Deep Research with only 30B (Activated 3B) parameters! Tongyi DeepResearch agent demonstrates state-of-the-art results, scoring 32.9 on Humanity's Last Exam, 45.3 on BrowseComp, and 75.0 on the xbench-DeepSearch benchmark.

Agentica Project retweeted

1/7 We're launching Tongyi DeepResearch, the first fully open-source Web Agent to achieve performance on par with OpenAI's Deep Research with only 30B (Activated 3B) parameters! Tongyi DeepResearch agent demonstrates state-of-the-art results, scoring 32.9 on Humanity's Last Exam, 45.3 on BrowseComp, and 75.0 on the xbench-DeepSearch benchmark.
Agentica Project retweeted
Congratulations to Alibaba Tongyi Lab for training a world-class DeepResearch agent! We are proud to power their training with rLLM -- our framework for post-training language agents.
Ever since its release, rLLM has been adopted by researchers & industry to build custom agents across coding, web, and terminal environments. Excited to see what’s next!
👉Check out rLLM: github.com/rllm-org/rllm/tre…
1/7 We're launching Tongyi DeepResearch, the first fully open-source Web Agent to achieve performance on par with OpenAI's Deep Research with only 30B (Activated 3B) parameters! Tongyi DeepResearch agent demonstrates state-of-the-art results, scoring 32.9 on Humanity's Last Exam, 45.3 on BrowseComp, and 75.0 on the xbench-DeepSearch benchmark.
Agentica Project retweeted
Excited to introduce DeepSWE-Preview, our latest model trained in collaboration with @Agentica_
Using only RL, we increase the performance of Qwen 3 32B from 23% to 42.2% on SWE-Bench Verified!

🚀 Introducing DeepSWE 🤖: our fully open-sourced, SOTA software engineering agent trained purely with RL on top of Qwen3-32B. DeepSWE achieves 59% on SWEBench-Verified with test-time scaling (and 42.2% Pass@1), topping the SWEBench leaderboard for open-weight models.
💪DeepSWE is trained with rLLM, our modular RL post-training framework for agents. rLLM makes it easy to build, train, and deploy RL-tuned agents on real-world workloads — from software engineering to web navigation and beyond.
🤗As always, we’re open-sourcing everything: not just the model, but the training code (rLLM), dataset (R2EGym), and training recipe for full reproducibility.
🔥Train DeepSWE yourself. Extend it. Build your own local agents. No secrets, no barriers.
DeepSWE and rLLM mark our major shift: from training language reasoners to building language agents that can truly learn from experience.
We believe the future of AI lies in experience-driven learning — and we’re here to democratize it.
Welcome to the era of experience. 🌍
Links below: (1/n)

Agentica Project retweeted

Let's give a big round of applause for an amazing open-source release! They're not just sharing the model's weights; they're open-sourcing everything: the model itself, the training code (rLLM), the dataset (R2EGym), and the training recipe for complete reproducibility. 👏👏👏👏
🚀 Introducing DeepSWE 🤖: our fully open-sourced, SOTA software engineering agent trained purely with RL on top of Qwen3-32B. DeepSWE achieves 59% on SWEBench-Verified with test-time scaling (and 42.2% Pass@1), topping the SWEBench leaderboard for open-weight models.
💪DeepSWE is trained with rLLM, our modular RL post-training framework for agents. rLLM makes it easy to build, train, and deploy RL-tuned agents on real-world workloads — from software engineering to web navigation and beyond.
🤗As always, we’re open-sourcing everything: not just the model, but the training code (rLLM), dataset (R2EGym), and training recipe for full reproducibility.
🔥Train DeepSWE yourself. Extend it. Build your own local agents. No secrets, no barriers.
DeepSWE and rLLM mark our major shift: from training language reasoners to building language agents that can truly learn from experience.
We believe the future of AI lies in experience-driven learning — and we’re here to democratize it.
Welcome to the era of experience. 🌍
Links below: (1/n)
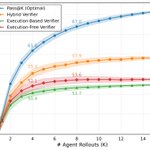
It's easy to confuse Best@K vs Pass@K—and we've seen some misconceptions about our results.
Our 59% on SWEBench-Verified is Pass@1 with Best@16, not Pass@8/16. Our Pass@8/16 is 67%/71%.
So how did we achieve this?
DeepSWE generates N candidate solutions. Then, another LLM (DeepSWE-Verifier) picks the best one to submit for evaluation. This is a classic form of test-time scaling (TTS) using Best@N.
Evaluating agents with TTS is common in SWEBench because there's no canonical agent design (unlike math or reasoning). Many top agents use multi-agent setups or agentic workflows (like Agentless), which naturally involve more LLM calls and test-time compute.
SWEBench ranks models by Pass@1, regardless of how many candidates were generated—as long as only one final solution is verified.
Among open-weight models, the top prior entry was Skywork-32B-SWE + TTS (Best@8) at 47%. DeepSWE + TTS (Best@16) now leads with 59% and becomes SOTA in this category.
Figure below shows how DeepSWE's performance scale with TTS:


Agentica Project retweeted

🚀 Introducing rLLM: a flexible framework for post-training language agents via RL. It's also the engine behind DeepSWE, a fully open-sourced, state-of-the-art coding agent.
🔗 GitHub: github.com/agentica-project/…
📘 rLLM: pretty-radio-b75.notion.site…
📘 DeepSWE: pretty-radio-b75.notion.site…

🚀 Introducing DeepSWE 🤖: our fully open-sourced, SOTA software engineering agent trained purely with RL on top of Qwen3-32B. DeepSWE achieves 59% on SWEBench-Verified with test-time scaling (and 42.2% Pass@1), topping the SWEBench leaderboard for open-weight models.
💪DeepSWE is trained with rLLM, our modular RL post-training framework for agents. rLLM makes it easy to build, train, and deploy RL-tuned agents on real-world workloads — from software engineering to web navigation and beyond.
🤗As always, we’re open-sourcing everything: not just the model, but the training code (rLLM), dataset (R2EGym), and training recipe for full reproducibility.
🔥Train DeepSWE yourself. Extend it. Build your own local agents. No secrets, no barriers.
DeepSWE and rLLM mark our major shift: from training language reasoners to building language agents that can truly learn from experience.
We believe the future of AI lies in experience-driven learning — and we’re here to democratize it.
Welcome to the era of experience. 🌍
Links below: (1/n)
Agentica Project retweeted
The first half of 2025 is all about reasoning models. The second half? It’s about agents.
At Agentica, we’re thrilled to launch two major releases:
1. DeepSWE, our STOA coding agent trained with RL that tops SWEBench leaderboard for open-weight models.
2. rLLM, our agent post-training framework that powers DeepSWE training and beyond.
These two releases mark our transition from training language reasoners to building language agents that can truly learn from experience.
Welcome to the era of experience.
🚀 Introducing DeepSWE 🤖: our fully open-sourced, SOTA software engineering agent trained purely with RL on top of Qwen3-32B. DeepSWE achieves 59% on SWEBench-Verified with test-time scaling (and 42.2% Pass@1), topping the SWEBench leaderboard for open-weight models.
💪DeepSWE is trained with rLLM, our modular RL post-training framework for agents. rLLM makes it easy to build, train, and deploy RL-tuned agents on real-world workloads — from software engineering to web navigation and beyond.
🤗As always, we’re open-sourcing everything: not just the model, but the training code (rLLM), dataset (R2EGym), and training recipe for full reproducibility.
🔥Train DeepSWE yourself. Extend it. Build your own local agents. No secrets, no barriers.
DeepSWE and rLLM mark our major shift: from training language reasoners to building language agents that can truly learn from experience.
We believe the future of AI lies in experience-driven learning — and we’re here to democratize it.
Welcome to the era of experience. 🌍
Links below: (1/n)
Agentica Project retweeted

We believe in experience-driven learning in the SKY lab. Hybrid verification plays an important role.
🚀 Introducing DeepSWE 🤖: our fully open-sourced, SOTA software engineering agent trained purely with RL on top of Qwen3-32B. DeepSWE achieves 59% on SWEBench-Verified with test-time scaling (and 42.2% Pass@1), topping the SWEBench leaderboard for open-weight models.
💪DeepSWE is trained with rLLM, our modular RL post-training framework for agents. rLLM makes it easy to build, train, and deploy RL-tuned agents on real-world workloads — from software engineering to web navigation and beyond.
🤗As always, we’re open-sourcing everything: not just the model, but the training code (rLLM), dataset (R2EGym), and training recipe for full reproducibility.
🔥Train DeepSWE yourself. Extend it. Build your own local agents. No secrets, no barriers.
DeepSWE and rLLM mark our major shift: from training language reasoners to building language agents that can truly learn from experience.
We believe the future of AI lies in experience-driven learning — and we’re here to democratize it.
Welcome to the era of experience. 🌍
Links below: (1/n)
Agentica Project retweeted

🚀 Introducing DeepSWE: Open-Source SWE Agent
We're excited to release DeepSWE, our fully open-source software engineering agent trained with pure reinforcement learning on Qwen3-32B.
📊 The results: 59% on SWE-Bench-Verified with test-time scaling (42.2% Pass@1) - new SOTA for open-weight approaches
⚡ What's different: Pure RL training. In just 200 steps, Pass@1 jumped from 23% → 42.2% achieving better performance than prior approaches, which have relied on expert trajectories distilled from Claude/GPT
🔓 Fully open: Model weights, rLLM framework, R2EGym dataset, complete training and test-time recipes for you to build
🚀 Introducing DeepSWE 🤖: our fully open-sourced, SOTA software engineering agent trained purely with RL on top of Qwen3-32B. DeepSWE achieves 59% on SWEBench-Verified with test-time scaling (and 42.2% Pass@1), topping the SWEBench leaderboard for open-weight models.
💪DeepSWE is trained with rLLM, our modular RL post-training framework for agents. rLLM makes it easy to build, train, and deploy RL-tuned agents on real-world workloads — from software engineering to web navigation and beyond.
🤗As always, we’re open-sourcing everything: not just the model, but the training code (rLLM), dataset (R2EGym), and training recipe for full reproducibility.
🔥Train DeepSWE yourself. Extend it. Build your own local agents. No secrets, no barriers.
DeepSWE and rLLM mark our major shift: from training language reasoners to building language agents that can truly learn from experience.
We believe the future of AI lies in experience-driven learning — and we’re here to democratize it.
Welcome to the era of experience. 🌍
Links below: (1/n)