

Building better local LLM inference on consumer GPUs. Creator of BeeLlama.cpp (1.1k+ stars on GitHub). Benchmarks, quantization, agents.
Belgrade
Joined June 2012
- Tweets531
- Following49
- Followers282
- Likes51



Pinned Tweet
Currently my main project is BeeLlama, a fork of llama.cpp with more than 900 stars on GitHub as of now.
It started very personally. I wanted to run Qwen 3.6 27B on my single RTX 3090, natively on Windows, and run it fast. And what can make it fast? Right, speculative decoding. But at that point, llama.cpp supported neither MTP nor DFlash.
So this May I forked it and made DFlash work there, with more and more tok/s gains in every subsequent release. It also shipped TurboQuant/TCQ for extreme KV cache quantization.
Since then, upstream llama.cpp has implemented a full set of speculative decoding options, and TurboQuant proved outdated in my own benchmarks. So BeeLlama moved on from those features and evolved.
Today, as of v0.4.x, its main additions are KVarN (variance-normalized KV cache quantization by Huawei) and KV Cache Precision Tail (storing recent tokens in full precision while quantizing the rest).
The feature set changes, but the idea stays the same. Local LLMs should be available to as many people as possible, not just owners of 4×3090 setups and entire fleets of DGX Sparks.
Quantization is a compromise, but the alternative is not being able to run the model at all. So the answer is to make quantization more efficient and minimize the losses, allowing people to experience local LLMs in the best shape possible on any half-decent hardware.
I'm constantly working on improving BeeLlama further and developing its unique features, while closely following upstream llama.cpp for improvements of their own.
So thank you to everyone using it, and stay tuned for more.


Hot take: Open source has a much greater impact outside of The Bubble when most of the effort is concentrated on a few flagship projects, much like with commercial products.
Yes, Opus 5.5 can create a new inference engine for you daily, one for each model, but how much does that contribute to the ecosystem compared to implementing tensor split for Qwen 3.8 Flash Next in llama.cpp?

I see they finally abandoned what they are not good at (building harnesses) and pivoted to vlogging.

full recap of our week in Argentina
youtube.com/watch?v=D3Dgp9hE…

SweatyPanzer v1.3.0 brings first-person view! More immersion while driving, more precision while shooting.
Play now for free!
Browser: sweatypanzer.com/
Steam: store.steampowered.com/app/5…
Dead on arrival, judging by benchmarks.

Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
SweatyPanzer v1.0 is out! We cooked really hard on this one with @huggos_.
Try it now for free! Links in the replies ↓
Here's what changed, beautifully showcased in the trailer:
- All tank models have been remade to better match their historical appearance and details.
- Pershing and AMX-13 joined the roster, so there's a playstyle for everyone.
- More guns! The Sherman can now choose between the 76 mm gun and the 105 mm howitzer.
- Significant improvements to graphics, sounds, and map design.
- Even smarter bots that play as a team and try to flank you.
- Loads of other fixes and improvements.

Just finished my first KVarN eval on AIME26 using BeeLlama v0.4.7!
I used @liquidai's LFM2.5-2.6B BF16 as the model. In hindsight, I would say it seems to be quite tolerant of KV cache quantization, as even the q4_0 result is not far behind bf16, while kvarn4 even beats it!
But I wouldn't call it "statistical error" either, because I used 20 repetitions, which is quite a lot. So I personally view the results as parity between bf16 and kvarn4, while q4_0 is clearly behind.
Which is a great result too! I will look into reproducing it on other models.
Setup: 2x3090, parallel 16, temperature 0.6, top_k 50, top_p 1.0, min_p 0.0, repeat_penalty 1.1, presence_penalty 0.0, 32,768 max output tokens.
q4_0_tail128 is required for comparison because KVarN always has a minimum KV Precision Tail of 128 in the BeeLlama.cpp implementation.

Here's an article on KLD benchmarks of both features vs standard quants
anbeeld.com/articles/kv-cach…
Here's an article on Precision Tail and its implementation in BeeLlama
anbeeld.com/articles/kv-cach…
Here's an article on KVarN and its implementation in BeeLlama
anbeeld.com/articles/kvarn-k…
You can try KVarN and Precision Tail features in BeeLlama.cpp, an actively developed fork of llama.cpp
github.com/Anbeeld/beellama.…

Tibo is stealing @superalesha's playbook?

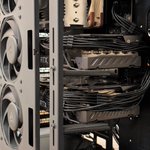
After 10 hours of inference, the upper GPU sits at around 61°C core temp and the lower one at 54°C, with power draw sitting at 220 W and 210 W respectively at the moment. Fans are far from 100% too.
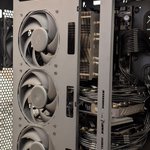
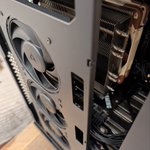
Side grill intake is a game changer!


In an almost controversial move, I just swapped the NH-D15 tower for a smaller NH-C14S top-down cooler.
In my case, the tower conflicts with the side intake, and a tall one like the NH-D15 also causes installation issues.
One of those rare use cases for a top-down cooler.
🧵

New PC case: PHANTEKS Enthoo Pro 2 Server Edition!
Absolutely BASED case for multi-GPU setups.
- 11 slots, so you can fit 3 GPUs with some space between them, or even 4-5 if they're thin and don't need much airflow.
- An additional fan bracket that can be installed on the side or in the middle of the case, providing airflow directly to the GPUs.
- A large side grill at the front where you can install four 120 mm fans, loads of drives, or even a GPU vertically with some custom mounting.
- Built-in multi-GPU support bracket.
- Loads of space, everything feels high quality, and it fits E-ATX motherboards.
All that for some €150-200, depending on where you live.
My previous Fractal Design Torrent is a good case as well, but not for multi-GPU setups. It's built around bottom intake and has no top exhaust fans, so the upper GPU doesn't get proper airflow.
Hopefully I'll be able to get a few more 3090s later on and use this beauty to its full potential.


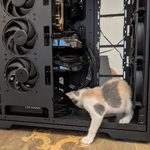
Kitten asks: “Why no water cooling?”
Answer: just preference. I kind of enjoy theorycrafting well working air cooling, and a 2×3090 setup is quite a challenge already.

