

Give your agents access to runtime evidence to verify their own work.
Joined March 2026
- Tweets62
- Following29
- Followers9
- Likes5




Was it the mobile app, the auth flow or a different configuration?
One Ansight session holds all three suspects: the request the app sent, the response that came back, the state it was in. Your agent checks each against the failure instead of guessing.
ansight.ai/

Ansight retweeted

Checking the same app journeys by hand before every release? 👀
UI tests still on the backlog because they’re a PITA to build? 🤦♂️
Use Ansight to turn easily create UI tests, written in plain language, from an existing app session replay.
ansight.ai/articles/from-man…

Another bug report. Another flag added to the code.
A fix without a reproduction is a guess wrapped in an if. With Ansight the agent reproduces the bug, reads the logs, requests and state at the failure, and fixes the cause. No new flag.
ansight.ai/
You've become the agent's test loop. Stop!
With Ansight the agent runs the app itself, reads what happened behind the screen, fixes, and runs it again. You get the result and the evidence, not the next attempt.
ansight.ai/
Say what to test. The agent works out how.
An Ansight test is a few plain sentences: what to do, what must be true at the end. The agent reuses the steps you've already automated, does the rest itself, and checks the result in the app's state.
ansight.ai/

Every session is a performance test. Even the ones that weren't.
Ansight records memory and frame rate in every run, test or dev session alike, and compares them build to build. A regression gets flagged with the session it was seen in attached.
ansight.ai/

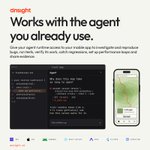
Works in the agent you already use.
Claude Code, Codex, Cursor, Gemini CLI, Kiro. Ansight ships 30 skills that teach the agent when to inspect a session, drive the app, run a test or score automation readiness. Every command returns JSON.
ansight.ai/

The bug report says what happened. Nobody knows why.
Reproduce it with Ansight and the failure is recorded in full: screenshots, UI trees, touches, logs, requests, events, metrics, state, preferences, files, database, crash report. A cause, not a guess.
ansight.ai/

The screen says “Saved.” The database is empty.
Ansight gives coding agents runtime evidence: logs, network requests, app state and tool results.
Catch hidden failures. Verify fixes. Give your team proof before shipping.
See how it works 👇
ansight.ai
Go check out Ansight! We are live in Product Hunt: producthunt.com/products/com…

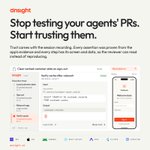
Stop testing your agents' PRs. Start trusting them.
Not on their word. On the run that arrives with the PR: every assertion proven from the app's evidence, every step with its screen and data, nothing left to the model's opinion. Read. Don't reproduce.
ansight.ai/

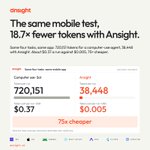
The same mobile test, 18.7× fewer tokens with Ansight.
Same four tasks, same app: a computer-use agent used 720,151 tokens, a test run on Ansight 38,448. About $0.37 a run against $0.005. Stable steps cost nothing. Results vary.
ansight.ai/#efficiency

A screenshot shows something's wrong. The component tree shows why.
Ansight lets your agent read the running app's React component tree, Flutter widget tree or MAUI bindings: the props and state behind the screen, not the paint.
ansight.ai/

Works for admin. Breaks for guest.
Give the agent the accounts and the rules per role. Ansight types the secrets for it, so it signs in as each role without seeing a password, runs the journey and verifies what each role can and cannot change.
ansight.ai/

Any metric your app records becomes a trend with a threshold.
Add a metric, record the value: cold start ms, sync queue depth, cache misses. Ansight grades it per build against your threshold and flags the regression, with the session attached.
ansight.ai/

"Works on my machine." Put the two sessions side by side.
Same steps, different result. Ansight lines up both sessions step by step and shows where they split: a different response, a different state, a flag that was on. The argument ends at that step.
ansight.ai/

The agent fixed checkout. Login broke. The PR looked fine.
Agents change more than they're asked to. Ansight runs every journey on a device for every PR, not just the one it touched. A red one comes back with the failing step attached.
ansight.ai/

Agents start with a hypothesis. Engineers start with evidence.
They code to the symptom. Ansight flips the order: read the request, the logs and the state at the failure first. The fix targets what happened, not what seemed likely.
ansight.ai/

The agent stops re-learning your app on every test run.
Ansight explores the app once and keeps a graph of screens and the ways between them. The agent still drives every test; "go to Settings" is now one step it takes, not ten it works out.
ansight.ai/

One tap. One request, duplicated. One green screen.
A duplicated submit is invisible from the UI. Ansight captures the app's requests, so your agent counts identical POSTs after one tap, fixes the double call and reruns until it sees exactly one.
ansight.ai/
