

Technology Cousin | Luddite Disrespect Enjoyer | AI Bloomer | Capital Allocatoooor
Joined April 2024
- Tweets14.7K
- Following344
- Followers361
- Likes12.5K



Pinned Tweet
A lot of people you meet are actually LLMs with a very small number of parameters.

Our notion of what is hard basically assumes relatively fixed variation in context windows. JVN probably had the largest context window of any human ever. The LLMs could be smaller and less efficient than us architecturally but outdo us by having a superhuman context window.

at the risk of sounding like a goalpost-mover, I think there is an additional conclusion we should be willing to make: we are broadly mistaken in our collective intuitions for how hard certain problems are
many problems we have imagined to be impossible will turn out to have pretty tractable solutions; AI doubters persistently underestimate how many things fall in this category
by extension, if we embrace that we have been quite bad at estimating the difficulty of some problems, we should entertain the idea that certain problems we have imagined to be *very easy* will elude resolution for a long time
1
33
It would be great if we had some normalized way to measure and publicize the amount of compute behind any given piece of slop. Nothing can save a terrible prompt but how much prompting skill does “explain it simply” really take?

Do you personally understand a word of what's written there? If not, then I have no interest in even glancing at it. I read plenty of my own AI's slop (which I love, because I know what questions I'm trying to get it to answer, so can interpret its answers in my own ways); I don't need to read that of others...
20
A few days ago I had my multiple subs of Astra 6.2 + Fable 5.2 + Opus 5.5 + Carbon swarm grinding at that first correct step of the proof (for reasons unrelated to RH) and it seems to be beyond current models.

1
35
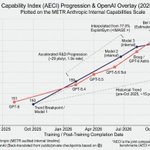
I had Carbon back into the capability trajectory implied by Bel’s CyberGym number. @METR_Evals @DKokotajlo you guys are still not calibrated.

1
3
120
OAI is ahead of Anthropic. Do the ECI math. The METR report and AI 2027 are both underselling timelines.


1
87
From my understanding the thing you’re worrying about is closer to 4-6 weeks away. You only think anthropic is ahead because METR let them publish their internal capabilities. OAI is months ahead of Anthropic.

Unfortunately, it seems like the intelligence explosion will be happening in 2027 after all. Most of this post analyzes the new METR report (though other sources of evidence are also important). If they’re right, that implies an AI-driven acceleration that is 5 months ahead of the AI 2027 scenario. I am scared, sad, and angry. blog.aifutures.org/p/q35-tim…

Everyone applying skepticism to the METR report will soon find they’ve beclowned themselves. Don’t talk yourself or others out of an update because — and I know this with good authority — OpenAI is significantly ahead of Anthropic internally.
2
87
“The Bitter Lesson” is borderline decel branding. What’s bitter about it? That it doesn’t adequately reward human ingenuity? “Oh no, all the capabilities come too easily for me to feel smart.”
1
179


