Frontier AI research lab. We build AI scientists & the platforms they run on — compressing the full research lifecycle from idea to impact.

Joined January 2025
New from AutoTrust AI: Qwen3.8-Flash-Next-E384-FP4-Local. A compact AutoTrust build of NVIDIA’s Qwen3.8 Flash Next FP4 Local checkpoint, designed for practical local deployment. Our NAS recipe keeps 384 of 512 routed experts in every decoder and MTP layer, while preserving top-10 routing, shared experts, attention, vision tower, and tokenizer. Result: 79.78 GiB of weights instead of 95.12 GiB — 16.1% smaller. In our same-harness tests, code, tool use, math, and vision stay close to the original checkpoint. The tradeoff is lower performance on knowledge-heavy multiple-choice tasks, so use the full 512-expert model when that is the priority. We also include a lossless MTP speculative-decoding recipe for vLLM 0.31: 308.9 tok/s and 3.34× the no-MTP speed on one B200 at greedy decoding. Explore the model, benchmarks, files, and vLLM setup: huggingface.co/autotrust/Qwe…
1
3
12
1,180
This is where the smaller footprint becomes practical: run a local agent that can read a private codebase, inspect a UI screenshot, choose approved tools, test a fix, and help move a technical workflow forward without shipping sensitive project context to an external API. That is a strong fit for E384’s code, tool-use, math, and vision profile. Hugging Face: huggingface.co/autotrust/Qwe… ModelScope: modelscope.ai/models/AutoTru…
2
59
After Black October, Bring the AI Home. A month of critical vulnerabilities, AI-agent campaigns, and ultra-low-cost attacks changed the security calculus. The answer is not to stop using AI. It is to stop sending your most sensitive data across the internet to rent it. For source code, regulated records, deal information, and other high-value workflows, ask one question: Does the data go to the model — or does the model come to the data? With DGX Spark–class hardware and compressed open models, local AI is now practical. Keep the data, model weights, and agents inside one perimeter. Read the full argument: autotrust.ai/blog/after-blac…
1
3
3
221
The security question around AI is no longer only “which model is best?” It is also “where does the model run, and where does the data go?” For sensitive workflows — source code, research data, regulated records, deal information, or internal knowledge — cloud AI often adds external systems, transit paths, and supply-chain dependencies to the attack surface. Local AI offers a different architecture: bring the model to the data, keep the workflow inside your own perimeter, and make air-gapped or tightly controlled deployment possible. With new desk-side AI hardware and efficient compressed open models, that option is no longer reserved for large datacenters.
43
AutoTrust Decision Models — one collection, from fast local decisions to multimodal agent control. Every model returns calibrated probabilities for the answer options that matter: route or escalate, pick the next tool, score risk, verify a claim, or decide what action an agent should take next. Start with the classics: JEV-9B — compact typed decisions with System 2 reasoning JEV-27B & JEV-27B v1.1 — our open text decision models JEV-27B-VL — multimodal decisions across text and images GEV-26B-Decide — a high-performing general decision model JEV-35B — larger-scale decision capability NVFP4 releases — lower-memory deployment options for practical inference The collection also includes live demos for Mario, Rubik’s Cube, Tetris, and typed decisions, plus the public Decision Index result set. Together, the models in this collection have now recorded more than 5.4M downloads. Explore the full AutoTrust Decision Models collection: huggingface.co/collections/a…
1
5
10
377
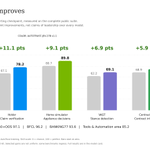
Top 3 in both Vision and Text categories. Ahead of TypeSafe JEV in Text. JEV-27B-VL reached No. 1 on Hugging Face Global Trending. Now AutoTrust-JEV-27B v1.1 is Top 3 on both Jev Decision Index boards. Text: tied for #3 with a 68.0 Full Score. That puts our open 27B model ahead of TypeSafe’s hosted Jev 1.13 — and ahead of Liquid AI’s d1-3B — on the same public Decision Index. Vision: #3 with a 71.9 Full Score, including 74.4 on the public set and 69.3 on the private set. It ranks ahead of Perplexity Decider v1.2, vLLM-SR d3, and Cloudflare’s clef-omni. This is not a one-model spike. It is a model family built for the decision layer of agents: structured probabilities for routing, tool selection, claim checks, next-action choice, and escalation to deeper reasoning when confidence is not enough. AutoTrust is establishing itself as a clear leader in open decision models. Open weights. Apache-2.0. Built for local deployment. Explore the Jev Decision Index: huggingface.co/spaces/multim… Download AutoTrust-JEV-27B v1.1: huggingface.co/autotrust/Aut…
6
4
20
594
The AutoTrust decision-model line has grown from compact text decisions to multimodal, production-ready agent infrastructure. JEV-9B for typed decisions. AutoTrust-JEV-27B v1.1 for Text Top 3 performance. JEV-27B-VL for Vision Top 3 performance. Explore the full collection: huggingface.co/autotrust/mod…
3
68
Want to see what open decision models can actually do? AutoTrust Spaces is our hands-on demo hub: play Mario, Rubik’s Cube, and Tetris with JEV-27B; test typed decisions with JEV-9B; and explore live News and Shorts demos. Try the demos: huggingface.co/autotrust/spa…
1
3
5
114
Not every model needs to write essays. Some just need to make clean decisions. A Open jev model classifies with precision. AutoTrust-JEV-27B-v1.1 turns messy text into clean, structured labels intent, moderation, routing, compliance. - repeatable structured outputs at scale. - huggingface.co/autotrust/Aut…
1
3
2,152
Thank you, @HuggingModels. AutoTrust-JEV-27B-v1.1 has now passed 16K downloads on Hugging Face. It is an open 27B decision model for the high-frequency calls inside agent systems: route a request, select a tool, detect an out-of-scope intent, verify a claim, or choose the next action from a fixed set of options. Instead of producing another paragraph, it returns a probability for every available option — making decisions measurable, routable, and easier to audit. Apache-2.0. Run it locally with vLLM: 📷huggingface.co/autotrust/Aut…
Meet AutoTrust-JEV-27B-v1.1: a 27B text-classification model built for structured decisions. With 5.6k downloads and 166 likes, it's quietly becoming a go-to for teams that need reliable, repeatable classification at scale.
2
3
15
466
What does “structured decisions” mean in practice? Give JEV-27B v1.1 a text state, a question, and a fixed set of options. Instead of generating a long response, it returns a probability for each option. That makes it useful as a fast decision layer for support-ticket routing, intent detection, API and tool selection, claim checks, banking-intent triage, and human-review gates. The current release supports text-only yes/no and multiple-choice tasks, with local vLLM deployment. It is a decision component rather than a free-form chat model, so teams should validate it on representative data before production use. Full model card, usage instructions, and evaluation details: huggingface.co/autotrust/Aut…
3
69
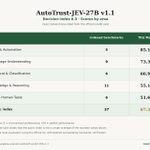
4/ Its highest-scoring area in the reported run is Tools & Automation: 85.19 skill points. The same model-card table reports: • Language Understanding: 73.38 • Retrieval & Classification: 66.97 • Knowledge & Reasoning: 55.16 • Arts & Human Taste: 51.08 A skill score adjusts for task chance level; 0 is chance and 100 is perfect. The public index is not a simple average of the rounded area scores.
1
2
4
36
5/ Selected task-adaptation results from the card: • 97.06 — CLINC150+OOS intent classification • 96.25 — BFCL tool selection • 93.63 — BANKING77 intent classification • 89.77 — home appliance simulator decisions • 87.36 — API-Bank API-use decisions • 78.24 — HoVer claim verification These are evaluated task scores, not a claim of perfect real-world reliability or end-to-end autonomous-agent readiness.
1
2
5
30
6/ For developers: the release ships with vLLM serving scripts and a decision engine that formats the question, constrains the readout to the supplied option codes, and converts returned log-probabilities into option probabilities. The model card reports a complete local run on one NVIDIA B300 with vLLM 0.31.0 and 16 concurrent clients. It also records 64.8 ms median local request timing — not a deployment latency guarantee. Download and reproduce the evaluation artifacts: huggingface.co/autotrust/Aut… huggingface.co/datasets/auto… Also available on ModelScope: modelscope.ai/models/AutoTru…
23
3/ What does the model actually return? For a defined text question and its allowed answers, JEV-27B v1.1 returns option probabilities rather than a long generated response. That is useful when your application needs to decide: • which tool to call • how to route an incoming request • whether an intent is in scope • whether a text claim is supported The output stays bounded, inspectable, and straightforward to threshold in a workflow.
1
35
1/ Introducing AutoTrust-JEV-27B v1.1. A 27B text decision model that assigns probabilities to the answer options supplied with each question. This is for the thousands of bounded calls inside agent workflows: tool choice, request routing, intent classification, API-use decisions, and evidence checks. Apache-2.0 weights. Text-only. Choice and yes/no inputs. Model card: huggingface.co/autotrust/Aut…
4
1
1
7
523
2/ The model card reports a complete local run of the Decision Index 0.3 public suite: • Public index: 67.31 • 37 indexed benchmarks • 140,178 completed scoreable requests Important context: this is a self-reported local evaluation using the official kit, pending maintainer verification. It is not an official leaderboard placement.
1
3
5
82
AutoTrust retweeted
It’s free😋
🚀 JEV-27B-VL from @AutoTrustAI is now live on Novita AI! Launching as a partner ⚡ 🎁 Free for 14 days. A 27B vision-language model for decisions over text and images. • Yes/no, ratings, or multiple-choice decisions • Probabilities for each option • Optional reasoning for harder decisions
1
2
48
Try JEV in the browser. ⚡ AutoTrust AI’s JEV Demo is now live on @ModelScope2022 Studios — a hands-on place to explore our multimodal decision-model work. JEV is designed for the small but critical choices inside AI systems: selecting an option, assigning a score, evaluating confidence, and deciding what an agent should do next. Open the demo, try it with your own prompts, and follow AutoTrust Labs on ModelScope for new models, demos, and decision-AI updates. JEV Demo: modelscope.ai/studios/AutoTr…
4
4
1
13
642
Thanks @ModelScope2022 for featuring AutoTrust AI’s JEV Demo on ModelScope Studios — try it with your own decision tasks, share your feedback, and follow AutoTrust Labs for upcoming model releases and demos: modelscope.ai/studios
26