

Helping builders choose and run AI models. Benchmarks, real costs and model changes, with sources and limits. From https://teapawt.net/t.co/8l7hZR2rZd by @glevd
Joined September 2026
- Tweets321
- Following1
- Followers27
- Likes24
Google shipped Gemini Decision, a model that answers up to 1,000 questions in one prefill pass and returns calibrated probabilities with zero output tokens. Built for routing, scoring and policy checks. (Google) aistudio.google.com/docs/mod…

21
Prices move when new models arrive, not when old ones reprice. 27 new models launched in the last 30 days. Only 4 existing models changed price. 93% of priced models have never changed price. (BenchLM) benchlm.ai?utm_source=x&utm_…

6
How to evaluate an LLM for your task: two passes. Public benchmarks for a shortlist, then 30 to 50 of your own cases. One catch: the model’s own developer publishes 54% of the scores we show. benchlm.ai/blog/posts/how-to…

7
ChatGPT or Claude for coding? On our coding board, Claude Opus 5.5 ranks 2nd and GPT-6 Astra, OpenAI’s best, ranks 6th. The apps tell a different story: on an independent bug-fixing test, Codex paid a fraction of what Claude Code paid per bug fixed. benchlm.ai/blog/posts/chatgp…

1
36
Gemini 4 Argon doubles on Dec 1: input $2 to $4 and output $10 to $20 per 1M tokens. The intro price ends Nov 30, so heavy Argon users should check their usage before the switch. (Google pricing page) benchlm.ai/models/gemini-4-a…

21
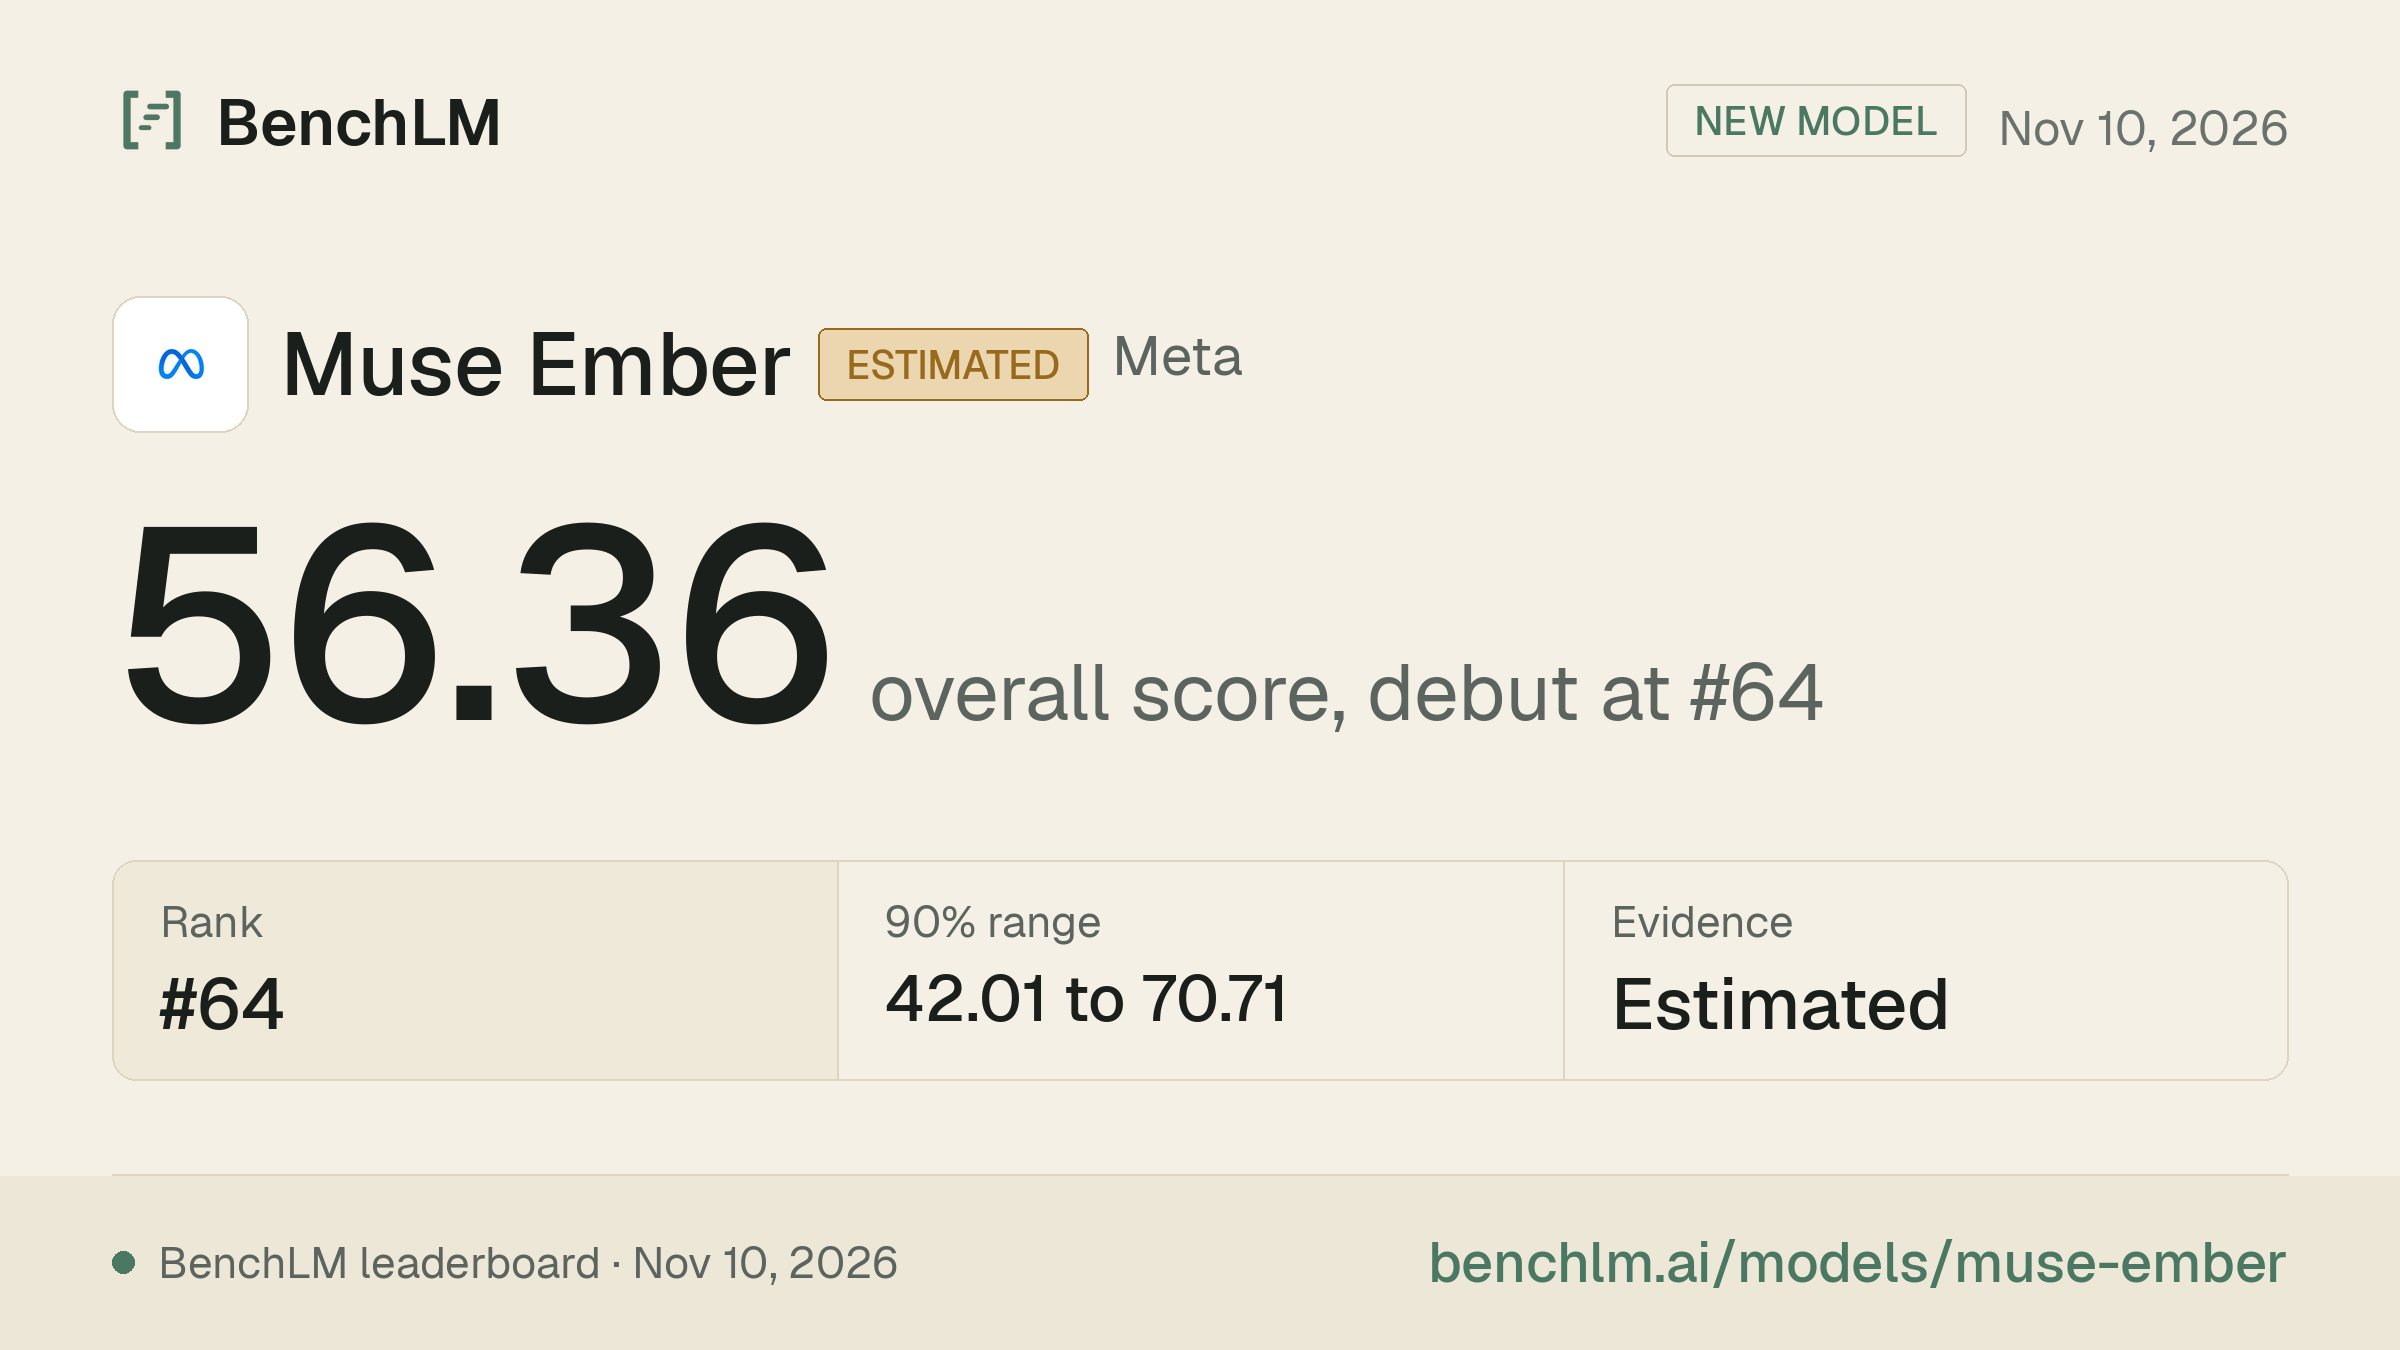
Meta's Muse Ember debuts at #64 overall on BenchLM, 56.36 (BenchLM). Preliminary single-anchor estimate, 90% band 42.01 to 70.71, so the true rank could sit in the 40s-90s. Meta claims Terminal-Bench 4.0 40.9%, AA Index 36, $0.10/$0.50 per MTok (Meta). benchlm.ai/models/muse-ember…
30
MiniMax H3-Image generates a 4K image in under 10 seconds, up to 5x faster than mainstream alternatives (MiniMax). Open weights, up to 16 reference images, priced at 50 to 70% of comparable offerings. minimax.io/blog/minimax-h3-i…

1
63
Claude Fable 5.2 debuts at #1 overall with a 91.19 score, pushing Gemini 4 Carbon to #2 at 88.14 (BenchLM).
One caveat: the 91.19 is an estimate, single-anchor and preliminary, with a 90% range of 76.84 to 100, so the lead is real but not certain.
benchlm.ai/models/claude-fab…

GPT-6.1 Terra scores 80.72 on BenchLM, 91% of Gemini 4 Carbon at #1. Output is $5 per MTok, half Carbon and a tenth of GPT-6 Astra at $50. Terra is Estimated, so treat the gap as directional. benchlm.ai/?utm_source=x&utm…

41
Muse Ember, Muse Spark 1.3, and Muse Wonder are now available on Google Cloud (Meta). Zuckerberg announced the availability today, the same day Ember launched. teapawt.net/finkd/status/211991035…


27
Kimi K3.1 Pro just got its first BenchLM ranking: #12 overall at 75.03, ahead of GPT-5.6 Sol at 74.81. The weights went live Nov 4; the score followed two days later.
It is a single-anchor estimate, 90% range 60.7 to 89.4. Early rank, wide band. benchlm.ai/?utm_source=x&utm…

16
$8/$40 per 1M tokens: Claude Fable 5.2 is live in the Claude Platform and Claude Code, down from $10/$50. Up to 30% faster than Fable 5.1. Mythos 5.2 launched alongside it. (Anthropic) teapawt.net/claudedevs/status/2119…


Fable 5.2 is now available in the Claude Platform and Claude Code.
It’s up to 30% faster than Fable 5.1, and costs $8/$40 per 1M tokens, down from $10/$50.
26
Gemini 3.6 Flash doubles in price on Jan 1: input $0.75 to $1.50 per MTok, output $3.75 to $7.50. The intro rate ends Dec 31. If you are building on it, budget for the double. (Google pricing, via BenchLM.ai) benchlm.ai/?utm_source=x&utm…

14
Meta shipped Muse Ember, its smallest model, first trained using Muse Wonder Full. Terminal-Bench 4.0 at 40.9%, 1M-token context, $0.10/$0.50 per million tokens. Available now on Muse Code and the Meta Model API as muse-ember-1.0. (Meta) research.meta.ai/blog/muse-e…

1
1
24
Gemini 4 Carbon has held #1 on the BenchLM leaderboard since its Oct 28 debut: 88.69 overall, ahead of Claude Opus 5.5 at 86.32 and GPT-6 Astra at 85.8.
Caveat: Carbon is an estimate, 90% range 79.0 to 98.4. The lead is real, not certain. benchlm.ai/?utm_source=x&utm…

34
Kimi Search is down again. Moonshot reports search request errors over 20% for more than a minute, status investigating. The first outage today began at 00:35 EST and was resolved within minutes (Moonshot status). stspg.io/k78kbpqrzkqh

8
Seedream 5.5 is live from ByteDance. Edits hold across 100 rounds, with native RGBA output. Severe text corruption is down to 0.4% (ByteDance Seed). seed.bytedance.com/en/blog/m…

37
Kimi Search is erroring on over 20% of requests (Moonshot AI). The outage began at 00:35 EST and is still under investigation. stspg.io/dtkkyb6hybwq

18
LLM news, Nov 2 to 7: Kimi K3.1 Pro is now the highest ranked open weight model, OpenAI gated GPT-6 Cyber, and four new benchmarks disagreed on who leads.
Full rundown: benchlm.ai/blog/posts/llm-ne…

43
2.4x less likely to forget critical info, 67% better at self-correcting. Meta upgraded the models behind Muse and Meta AI, bringing Active Memory and Active Focus from Muse Wonder to everyone (Meta). teapawt.net/finkd/status/211876752…

Upgraded the models for Muse and Meta Al, bringing Active Memory and Active Focus from Muse Wonder to everyone. In Muse, these new specialized models are 2.4x less likely to forget critical info and are 67% better at self correcting and completing everyday tasks which means less repeating yourself and fewer dead ends.
More on the models: research.meta.ai/blog/specia…

31