

24 | Owner of @WebSecured Pentester And developer https://teapawt.net/t.co/huVywpm5pR rulett-nerd Security nerd, and public speaker somehow
Trondheim, Norway
Joined April 2013
- Tweets5.3K
- Following528
- Followers2.5K
- Likes1K





Daniel Christensen retweeted

Our entire business model is one notification. KPI: tag @elonmusk. Q1 report: tag achieved. Investors remain baffled. a-company-that-tags-elonmusk… @elonmusk @BobTShoplifter


I think i have accepted and rejected this about 1500 times @CloudflareDev you can use my localstorage i consent

1
1
271
Are we ok? @AnthropicAI @ClaudeDevs
Why is claudes first response when it can't do something to disable security features?

5
222

One and a half year anniversary on a still open report on @Bugcrowd 😭 @intigriti would never

2
6
671
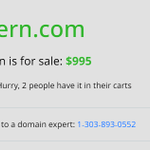
Cool, @OpenAI silently bought a domain that could have been a supply chain vector to npmjs.com/package/codex The domain incatern.com now redirects to developers.openai.com/codex

incatern.com now redirects to developers.openai.com/codex good job @OpenAI @sama (i hope you bought it)
381


The system prompt is pretty great 🤣 @theo


Introducing SubQ - a major breakthrough in LLM intelligence.
It is the first model built on a fully sub-quadratic sparse-attention architecture (SSA),
And the first frontier model with a 12 million token context window which is:
- 52x faster than FlashAttention at 1MM tokens
- Less than 5% the cost of Opus
Transformer-based LLMs waste compute by processing every possible relationship between words (standard attention).
Only a small fraction actually matter.
@subquadratic finds and focuses only on the ones that do.
That's nearly 1,000x less compute and a new way for LLMs to scale.


