

Foundations now. LLM products soon. | ML • Python • Data stack | Building in public for SaaS founders
India
Joined August 2024
- Tweets444
- Following68
- Followers83
- Likes8.1K




1/
A support bot can give a customer the wrong price and still sound completely confident.
I wanted to see if RAG evaluation metrics could catch that, so I deliberately planted wrong facts in a bot’s answers and tested 28 Q&As.
Here’s what happened🧵

Day 5 of building a RAG evaluator:
I planted 10 known failures in a test set to see if the judge would catch them.
It caught 10/10
It also flagged 4 of 10 perfectly good answers.
The false alarms were harmless things like "According to the help center..." and "contact support."

The judge treated them as unsupported claims. I agreed with it on 6 of 9 rows I graded by hand.
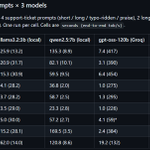
Same input scored twice: faithfulness moved on 3 of 10 rows, and one flag flipped.
#buildinpublic
1/
Day 4: "the chatbot seems fine" is how most RAG projects get shipped. I built a reusable evaluator so I can hand a founder a number instead.
Scored 28 support answers. Total judge cost: $0.06.
Follow the thread below so you know what to check before any build👇
4/
Another trap: 25% of answers were "I don't have that info." They scored as hallucinations.
Naive hallucination rate: 78.6%. Counting only answers that actually tried: 71.4%.
"I don't know" isn't a hallucination, so I report three numbers: abstention, hallucination, retrieval
SaaS founders: what’s the biggest blocker to adding AI to your product or support?
I build AI chatbots and knowledge-base tools. Before I decide what to build next, I want to hear from the people who’d use them.
50%Cost
0%Accuracy / hallucinations
0%Data privacy
50%No time or no team
2 votes • Final resultsAn eval set with no known failures can't tell you if your evaluator works.
Day 3: I built a 28-question test set for a RAG support bot, then broke it on purpose.
→ 5 rows with the wrong docs retrieved
→ 5 rows with a planted false claim
→ 3 questions the docs can't answer
→
A RAG eval score of 1.0 doesn't mean your chatbot is right.
Day 2 of testing RAGAS: I wrote 4 deliberately bad answers and predicted the scores before running.
→ Planted a false claim: faithfulness 0.75, relevancy 0.98
→👇