




Pinned Tweet
this was lots of fun and lots of all nighters over the past few weeks. really happy with what we achieved!

NVIDIA Blackwell can achieve 303 output tokens/s for DeepSeek R1 in FP4 precision, per our benchmarking of an Avian API endpoint
Artificial Analysis benchmarked DeepSeek R1 on an @avian_io private API endpoint. Running DeepSeek R1 in FP4 precision on NVIDIA Blackwell, their endpoint achieved 303 output tokens/s - the fastest speed we have measured yet for DeepSeek R1.
The FP4 version of DeepSeek R1 maintained accuracy across our evaluation suite as compared to the native FP8 version.
Inference speed is especially critical for reasoning models that ‘think’ before they answer - we look forward to wider availability of NVIDIA Blackwell hardware in the coming months!

i remember in august '25 asking a researcher about whether "reverse distillation" was possible, because this area was deafeningly silent.
like of course a smaller model's representations are better than random init


conservation of matter gives a secure store of value, only if you can't do cheap fusion
conservation of energy gives a secure proof of compute, which so far has just made another store of value
but unlike gold, compute doesn't just sit in a vault: it can do trustless inference

Last month, we demonstrated high-rate alchemy: turning mercury into real, stable gold, beating CERN’s record by a factor of 10.
Last week, we enriched isotopes in the world’s most powerful plasma centrifuge, beating the Soviet record that stood for 40 years.
Now, we’re building a fusion reactor in San Francisco to achieve record power density.
if I had a nickle for every time someone has done this and won a nobel prize, I'd have two nickles. which isn't a lot, but it's weird that it's happened twice


What is AI really capable of in bio?
To separate hype from reality, we spent 3 months working firsthand with @AnthropicAI's internal research model to see if it could create an experimental scorpion antivenom.
Introducing Citrini Therapeutics.
citriniresearch.com/p/citrin…

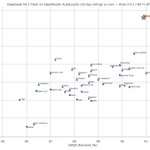
is everybody on OpenRouter just quantizing DeepSeek 4.1 Flash into oblivion to cut costs? I suppose the auto-exacto tier exposes some of this, but we need better.
commodity markets like wheat or corn have had a concept of provenance forever, and for the commodity of LLM tokens, this seems sorely needed.
every request here was ran on 8x B200s but could be ran on a 5090, a CPU, or a toaster and the hash of the logits would match, so you don't need to trust any provider.
this is using the public weights, but using bit exact inference with a custom rust-based DSL directly emitting PTX instructions for fully deterministic, integer only operations.

ALT chart of auto-exacto benchmarks from OpenRouter for DeepSeek 4.1Flash
met someone who essentially got a multimillion dollar house for free out of this tragedy bc a major bank’s vault flooded, but it held the sole promissory note for a mortgage. the bank repeatedly took them to court but the judge just said “ok produce the promissory note”

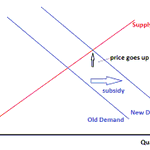
im begging people to realize that econ 101 charts apply to more than just corn or wheat prices. if you stopped subsidizing demand for a bushel of corn or wheat, the price for said bushels goes down, not up

ALT econ 101 chart on subsidized demand


unironically thought this was Manhattan at first


Good read on Apple Neural Engine architecture from author of ANE driver for linux
eiln.github.io/posts/ane.htm…

this is precisely the workload for which megakernels are infinitely better suited than the traditional serving stack with cuda graphs + optimized kernels

Dense → Mixture of Experts (MoE), 2023
Uniform Looped Transformer → Mixture of Recursions (MoR), 2025
Same move, different axis:
MoE makes width conditional: each token picks its experts.
MoR makes depth conditional: each token picks how many times it loops.
A learned router lets easy tokens exit after one pass while hard ones keep recursing. Same weights reused, compute spent where it's actually needed.
Paper (NeurIPS 2025): arxiv.org/abs/2507.10524

it’s been repeatedly shown since 2020 that increasing (at least direct) interpretability almost axiomatically decreases intelligence. this is just a rephrase of The Bitter Lesson, so it’s not surprising that supplanting CoTs with looped transformers improves everything


A lot of hype around OpenAI's Astra model here on my timeline today. Apparently, this goes back to a new article from The Information, which said Astra is a "recurrent depth or looped transformer".
It's always interesting to read about new or different approaches (including rumors about what the closed labs may be up to), but let's debunk this a bit.
About 2 months ago, I shared the architecture details of Nanbeige, for example, where "Nanbeige4.2-3B is pretrained from scratch on 28T tokens with a Looped Transformer that reuses the layer stack to increase capacity without adding parameters."
Yes, that's it. The looped transformer idea is just reusing layers in the transformer block.
In the case of Nanbeige, the main idea is to reuse the same 22-layer stack (=transformer block) twice instead of once. So, effectively it extends the 22-layer architecture to 44 layers, but without duplicating the weights.
In simple terms, this roughly doubles the size of the model (if we ignore the embedding and output layers for a second). But instead of requiring 2x the storage and RAM to host this model, it stays at the same size since we reuse the components. However, it's almost 2x as expensive in terms of compute, because we run the embedded text through almost 2x as many layers.
Why? In the Nanbeige 4.2 technical report, the researchers found that two passes gave the best trade-off and retained about 75% of the token efficiency of a standard architecture. (More passes gave barely any gains but made the training much slower and much more expensive.)
While, as far as I know, Nanbeige 4.2 is the first notable open-weight model that adopted this approach, the idea goes back to the NeurIPS paper "Mixture-of-recursions: Learning dynamic recursive depths for adaptive token-level computation". Actually, this paper proposes a mechanism that is a bit more sophisticated by adding a learned router that determines whether each token receives one, two, or more passes. So, easy tokens can exit early while harder tokens receive additional computation.
In sum, Astra may be a really good model, but this shouldn't be about this "looped transformer aspect," which is just a tiny architectural tweak.
Also, the statement "the new technique works in a way that obscures some or all of the AI's reasoning, otherwise known as 'chain-of-thought'" is not necessarily true with respect to the looped transformer method. It's possible that The Information journalist refers to some other technique or misunderstood the looped transformer method.
Reusing layers does not by itself suppress visible chain of thought. It adds computation in hidden states before the next token is emitted, just as ordinary transformer layers do.
But based on the information we have, the only plausible interpretation here is that if a model uses more of these recurrent passes, it may need to generate fewer intermediate reasoning tokens. So then more of its computation happens in latent activations that cannot be read as text. But we would get the same effect if we were scaling up the model size, like GPT 5.6 Luna -> GPT 5.6 Sol.

behold: grokking in your browser tab


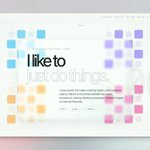
my personal site trains a tiny transformer in your browser on modular addition, so you can watch it overfit and get an easter egg when it groks. you can also see the attention scores shift during training & when scrolling the page, which uses a hilbert curve to change inputs

ALT landing page for poole.ai
my personal site trains a tiny transformer in your browser on modular addition, so you can watch it overfit and get an easter egg when it groks. you can also see the attention scores shift during training & when scrolling the page, which uses a hilbert curve to change inputs
ALT landing page for poole.ai
imagine going back in time a decade and telling someone that Apple will release a consumer computer that has marketing page benchmarks for DNA sequencing

teapawt.net/CarsonPoole/status/200… i was a bit early to the party

you're absolutely right to push back! the smoking gun was that the escape hatch was load-bearing. let's lock in these changes and pick it up next session
residency exists before MDs treat, and MDs forget most of med school outside their field.
my hottest take is that school exists not to teach, but rather to certify cognitive capability and conscientiousness.
this concern is yet another case of Nothing Ever Happens

saw this post and realized I never took the time to share the work I did many months ago that are genuinely quite cool. it resolve a big issue people broached (bit exactness) in the replies and also significantly alleviates a secondary issue (speed).
it uses zero floating point ops in the inference, so you can run the thing on a GPU, CPU, or even a toaster and get bit exact (de)compressed text by design, and it's around 3600x faster than @nathanrs's Qwen experiment on CPU. on GPU it gets 50MB/s decompression, which is 28,000x faster than Fabrice Bellard's GPU implementation.
teapawt.net/nathanrs/status/207309…


