

founder at https://teapawt.net/t.co/1o2L5WJiIp / @appworks 31 writing public notes on agent memories and runtime
Joined March 2025
- Tweets1.1K
- Following732
- Followers226
- Likes337




Pinned Tweet
AI memory needs edits when project decisions change.
SQLite becomes Postgres. The old memory needs a correction, too.
Cairn lets you inspect the saved source text, correct a memory, and forget it.
Local developer preview:
github.com/Cairn-ink/cairn-m…

2
8
666
The 15 to 30 seconds I wait after sending a prompt have quietly wrecked my focus. My first fix was a listener hooked into every AI session. Too heavy. What stuck was a dumb sticky note in the corner of my screen that I just talk to.
Last year I kept a book on my desk for those waits. This year I can't keep my hands still. Hit send, switch window, start something else.
When most of my workstreams run through AI, my attention bounces between windows all day. It's been like this for almost a year, and lately, with more on my plate, my brain is just out of headroom. I switch away, come back, and stare at the screen trying to remember what I was even doing. If I try to hold the thing in my head so I don't lose it, it's like running too many background processes. Nothing else gets my full attention either.
So I went and read up on work interruptions and "attention residue." One fix was almost embarrassingly simple. Before you switch from task A to task B, spend a few seconds writing down exactly where you are and what you'll look at first when you come back. Once your brain knows there's a concrete handoff plan, it stops nagging you about A while you're doing B.
Version one: I built a central listener that watched every AI session plus a bunch of websites. Before leaving one, I'd note what it was doing and where to pick up. Like leaving Claude with "check the two failed logins first when you're back," then letting the listener remind me later.
Ran that for a while. Too heavy. My work doesn't only happen in places I can listen to. Sometimes I'm editing slides, sometimes I'm in some other app, and there's no way I'm wiring every tool into one system. The maintenance cost was way too high.
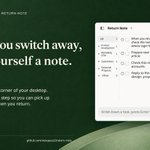
So I gutted it. Version two is a standalone sticky note pinned to the corner of my desktop. I named it 回來, which means "come back." It has AI and voice input. Whatever I'm doing, when something pops into my head or I'm about to switch windows, I say one sentence out loud and it's saved. The AI sorts it into buckets like product, marketing/GTM, ops, or client work, so I don't have to.
The UI borrows from Things and Bear, quiet and easy to read. Sidebar and secondary actions stay hidden. It sits in the bottom right corner showing only the to-do text, so it stays out of my way.
I also split "jot it down" from "start doing it." Stuff I jot down just sits there quietly. When I actually click an item to work on it, a timer starts. If it's a few-minute chore, I do it and check it off.
A few days in, my head feels less scattered and I'm clearing more tasks per day. Yes, I know. I reinvented the sticky note. I've seen plenty of people turn to-do lists into cute pet-raising games or Pomodoro timers. For the way I work now, with several AI windows open at once, none of that touches the part that hurts most: the second I switch back, can I pick up the thread I dropped? That's the only job I needed this thing to do.
🤖 Made with AI

5
4
96
I pulled my Claude Code and Codex logs from Oct 29 to Nov 11. In 14 days, my agents logged 2,910 active hours.
14 days is only 336 wall-clock hours. That means an average of 8.7 agents were running at any given moment, peaking at 33 concurrent agents and roughly 100 new Codex workers spawned per day. Even between midnight and 6 AM, an average of 8.2 agents were still grinding away while I was asleep.
Here is how the 2,910 hours broke down:
- Codex workers: 1,571 hours writing code, running tests, and doing reviews
- Claude Code: 990 hours talking with me, breaking down tasks, and checking output
- Codex subagents and helpers: 348 hours spun up by workers
My script counts any 5-minute window with activity as active work, so time spent waiting on model responses is baked into those numbers. Take the exact total with a grain of salt.
Still, the shift is real. Anything with a clear verification check, like writing code or running tests, is completely handed off now. What actually bottlenecks me from morning to night are the decisions with no test suite: who we are building for first, and which feature ships next. Week two agent volume jumped 45% over week one. My own cognitive bandwidth did not scale with it.
98% of those 2,910 hours went into building Cairn, an open-source memory engine for agents: github.com/Cairn-ink/cairn-m…
🤖 Made with AI

Anthropic just put Recursive Self-Improvement into nearly 90 pages of SEC S-1/A risk factors, right next to $895.4 billion in long-term compute commitments.
Usually, tech IPO risk factors are boring stuff about cloud costs or supply chain concentration. Anthropic went ahead and warned the SEC that based on internal projections, upcoming models could imminently hit the threshold for substantial AI-driven R&D acceleration defined in their Responsible Scaling Policy.
To be clear about what the filing actually says, none of their released models have crossed this line yet. The projection is about upcoming models. Still, they admitted a brutal engineering blind spot in the exact same section. Because their teams rely heavily on Claude to write software and run R&D tasks, capability jumps sometimes outpace human oversight and safety checks. They even admitted that in the past, R&D speed jumped significantly and the team only realized it after the fact.
That specific feeling of only realizing after the fact hit close to home. When I used agents to overhaul parts of our own codebase recently, the bottleneck completely shifted. Writing code by hand meant my mental model grew at the exact same speed as the repo. When agents started opening branches and shipping PRs in minutes, I got buried in verification and had to drag my 12-year-old gaming PC out of the closet just to help run CI. When output outpaces your ability to read every line, you get this nagging feeling that everything passes the tests, yet some core assumption underneath quietly mutated. Inside Anthropic, the thing being mutated is the next frontier model itself.
Reading this in an SEC filing instead of an alignment blog post adds a weird layer of irony. Under US securities law, risk factors act as legal body armor. The scarier and more exhaustive you make the worst-case scenarios, the better protected you are from shareholder lawsuits if a model goes sideways or a safety pause tanks the stock. In the AI market, though, a legal disclaimer meant to scare off risk-averse investors reads like the ultimate flex to Wall Street. Telling the market in a legally binding document that your models are about to accelerate their own R&D creates more FOMO than any PR campaign ever could.
The real tension shows up when you flip to the financial tables in the back. Anthropic is structured as a Public Benefit Corporation. They explicitly warn investors that if a future model trips a high-risk safety threshold, they are obligated to pause training or delay commercial deployment, even if it hurts short-term revenue and share price. Then you look at the commitments. They have roughly $895.4 billion in long-term purchase and lease obligations stretching into the 2030s and 2040s. Nearly $69.8 billion of that is due within the next 12 months alone, and their minimum commitment to Google Cloud and TPUs sits above $121.3 billion.
Hitting pause was hard enough as a private lab backed by a handful of VCs and tech giants. Once you are a public company staring at daily ticker swings, quarterly earnings calls, and nearly $900 billion in non-cancelable compute bills burning cash every single day, can anyone actually pull the plug just because an internal safety metric flashed red?
It reminds me of Wall Street risk management desks right before 2008. Every investment bank had strict risk models and stop-loss limits printed right there in their public filings. When the bull market was roaring and competitors were levering up, no Chief Risk Officer dared to walk onto the trading floor and cut the power. Instead, they quietly tweaked the risk formulas so the machine could keep running.
I respect Anthropic's safety research a lot. Many of our early ideas around agent permissions and memory governance came straight out of reading their work. Still, once the machine needs public equity markets and $895.4 billion in compute contracts to stay fed, deciding whether to hit the brakes stops being a lab safety question.
1
3
135
Wiring Slack, your CRM, and Notion into an LLM does not give you a Company Brain. Most teams build a solid 3-layer Knowledge Base and completely break on the last 2 layers: state freshness and governance.
Last week I went back to AppWorks for the AI Founder Circle to talk with other founders about what a Company Brain actually looks like in practice. Since January, after messing around with OpenClaw, running a swarm of AI agents for our own daily work, and spending months hitting walls in Agent Memory, one question kept coming up. Once AI becomes part of daily operations, how does a company actually accumulate its knowledge, decisions, and experience? Preparing the slides was a good excuse to put everything we learned about AI-native organizations into one structure.
Right now, everyone defines Company Brain a bit differently. Some treat it as a continuously updated knowledge base, some see it as cross-tool AI search, and others approach it from Agent Memory. All of those make sense depending on how a team works and what pain they are trying to solve today.
In the talk, I started with what daily operations look like in an AI-native company. Say sales, product, and support all have AI help, or even have agents running parts of the workflow independently. If every agent is great solo, but has no idea what another team just decided, what was promised to a customer, or where a deliverable is stuck, humans still end up acting as the message bus in the middle, repeating context all day. Just piping Slack, CRM, and docs together does not fix that. An organization needs shared working context that stays current and that people can actually trust.
I break an ideal Company Brain into 5 layers:
1. Context capture: pulling scattered info from Slack, meetings, docs, and daily work without making humans organize it by hand every time.
2. Decision rationale: recording not just the final call, but why it was made and which options were ruled out along the way.
3. Commitment tracking: knowing who promised what, when it is due, and where it is currently blocked.
4. Staying current: telling which version actually counts when plans pivot, so old and new decisions do not get mixed together.
5. Permissions and governance: managing who and which agent can read or edit, and whose word actually counts as an official company decision.
If you get the first 3 layers working, you already have a pretty solid Knowledge Base. But if you want the whole company to actually rely on it to get work done, the hardest parts are layers 4 and 5. That is the exact reliability wall we keep hitting in Agent Memory.
Take a simple everyday example. Someone drops a message in Slack: "Can we push the delivery date to next Tuesday?" Is that just a casual question, or a final decision? If the deadline really moves, how does the AI know which version holds now? Who has the authority to write that change into the shared consensus the whole team follows? The worse part is that once an AI writes a wrong, outdated, or voided piece of info into its memory, it will still execute on it with full confidence next time.
Not every company needs to build a full Company Brain right now. For teams just starting to adopt AI, cleaning up SOPs and a basic knowledge base already gets you pretty far. The maintenance and debugging headaches only really surface once work crosses departments and multiple agents that need to hand off tasks and look back at why a decision was made.
What we have been building at Cairn is Agent Memory, which is not the exact same thing as a full Company Brain. Still, as more agents move into real organizations, the traps around memory reliability, state updates, and shared permissions turn out to be almost identical.
🤖 Made with AI


23
15
454
i need itttt

HOLY F*CK, animation design studio in 18 repos.
18 free open-source skills for Opus 5.5.
Scenes. Timelines. Vectors. Particles. Export.
01 Remotion Skills → Agent guidance for video.
github.com/remotion-dev/skil…
02 Motion Canvas → Animated explainers. github.com/motion-canvas/mot…
03 Motion → Layout transitions.
github.com/motiondivision/mo…
04 Ola → Smooth value interpolation.
github.com/franciscop/ola
05 Anime.js → Timelines and stagger. github.com/juliangarnier/ani…
06 Manim → Math in motion.
github.com/ManimCommunity/ma…
07 Shifty → Tween playback and easing.
github.com/jeremyckahn/shift…
08 Two.js → Animated 2D vector scenes.
github.com/jonobr1/two.js
09 Lottie Web → Vector animation playback.
github.com/airbnb/lottie-web
10 TweenJS → Sequenced property animation.
github.com/CreateJS/TweenJS
11 LUME → 3D scenes with HTML.
github.com/lume/lume
12 gifenc → Animated GIF encoding.
github.com/mattdesl/gifenc
13 Konva → Interactive canvas animation.
github.com/konvajs/konva
14 Blender → Rigging and character animation.
github.com/blender/blender
15 Three.js → Animated 3D scenes.
github.com/mrdoob/three.js
16 Godot → Game animation systems.
github.com/godotengine/godot
17 Babylon.js → 3D animation and rendering.
github.com/BabylonJS/Babylon…
18 Proton → Particle emitters and behaviors.
github.com/drawcall/Proton
Brief → build → animate → refine → render.
Bookmark this. Go build something worth watching ↓
2
70
Agent memory needs an audit trail. An outdated decision can look just as convincing as a current one when you cannot see where it came from.
I built the open-source Cairn.ink Memory package so a saved memory can carry the submitted source text, be inspected, corrected at a known revision, or removed from active recall. The local open-source preview uses your own SQLite file and explicit tools. It is still a developer preview; the repo includes known limitations and retained failures.
The published cairn-ink/memory npm installer is a separate hosted setup path for Claude Code and Codex. I do not want the two data flows to sound interchangeable.
Read the implementation, and star the repo if this is the kind of agent memory you want to see improved:
github.com/Cairn-ink/cairn-m…

5
6
190
I upgraded my main rig to a 16-core Ryzen 9 9950X just so my mouse wouldn't lag while 33 subagents run in parallel.
Early last year, I switched to a Ryzen 7 7700. Back then, I figured all the heavy compute for coding was in the cloud anyway, so an 8-core chip was plenty for daily dev work.
Turns out my workflow changed completely. Now my agent regularly spawns a bunch of subagents at once, peaking at 33 running in parallel. Having 33 instances spinning up processes, reading and writing files, and running commands inside WSL all at the same time completely crushed my old setup. Every time they kicked off, my whole Windows machine would stutter. Some of it was probably disk I/O too, but having my cursor and keystrokes freeze for a split second every time I switched windows was driving me insane.
I finally snapped and went straight for the 16-core, 32-thread 9950X, paired with a Noctua NH-D15 G2 cooler. That cooler handles the heat and noise like a champ. Now, even with WSL going full throttle and all 33 subagents running concurrently, Windows barely stutters at all. Watching Task Manager handle the load with room to spare feels ridiculously good.
One lucky break from early last year was grabbing 64GB of DDR5 when I moved to the AM5 platform. At the time I thought it was overkill. Looking back, I really dodged a bullet, because 30+ subagents would have blown right through my RAM too.
People usually buy flagship CPUs and massive air coolers to max out game settings or render 3D scenes. I bought mine so my mouse cursor stays smooth while babysitting a swarm of local subagents. Now I'm already tempted to build another box just for this.


5
5
244
Halfway through SLP Taipei. Going in, I honestly thought it might be a cult. I was wrong. 🤣
Just got back from today's Mentor Day and realized we're already at the midpoint. Time went way faster than I expected.
I wasn't planning to join any accelerator or founder community this year. Then one thing led to another, I applied anyway, and somehow got in.
Probably bad timing to admit this, since we're about to open applications for the next cohort. But before joining I really pictured SLP as some secretive cult. The kind of place where everyone chants slogans together and says "thank you, master" in unison. lol
Turns out it's nothing like that. People come from all kinds of industries, everyone is interesting and actually good at what they do, and they're surprisingly willing to help each other.
The first half gave me more than I expected. I met a lot of strong founders and mentors, got pulled into areas I'd never touched before, and had a bunch of my blind spots as a founder cleared up.
Looking back, I'm glad I said yes. 🙏


3
5
270
GitHub Actions was burning over $25 a day on my AI agent PRs, so I dragged my 12-year-old i5-4690 gaming PC out of retirement to run CI.
I have been using AI agents to overhaul Cairn lately. Features that used to take half a day to code by hand now take a few minutes to branch and open a PR. Turns out the bottleneck just moved straight to CI. Every change still needs automated tests and builds to make sure nothing broke, and as the PR volume spiked, cloud runners got expensive fast. I started offloading jobs to machines at home, including my daily driver desktop, which meant my own dev work kept lagging every time a test suite kicked off.
Desperate for extra compute, I went looking for my old gaming rigs. Every time I upgraded over the years, I handed the old build down to my brother instead of selling or trashing it. Thanks to him holding onto two or three generations of my hand-me-downs, a pile of decade-old gaming hardware was still sitting intact.
Back then I always gave myself a strict budget of under 30,000 NTD (around $1,000 USD) per build. Squeezing the best CPU, GPU, and RAM out of that budget was half the fun. The very first PC I built myself 12 years ago had an i5-4690, an R9 270, and 32GB of RAM. When I carried it back from my brother's place, the cooler still had a sticker on it reading 103.06.08, which is June 8, 2014 in the Taiwan calendar. I definitely did not expect that machine to still be relevant in 2026.
Because my brother kept using it on and off, it booted right up. I flashed Ubuntu 26.04 LTS onto it and it went straight into the OS without the usual old-hardware sluggishness. Watching a sub-$1,000 gaming rig from 2014 pick up modern CI jobs felt weirdly satisfying. Paid once, got the dopamine hit twice.
I also pulled out a Ryzen 5 3600 build from seven years ago. It sits in a be quiet! case that survived multiple internal swaps and introduced me to Noctua fans. That machine retired at the end of 2024 when its motherboard died, which was what pushed me to upgrade my main desktop to an AM5 Ryzen 7 7700 early last year. Yesterday I spent 2,500 NTD (about $80 USD) on a new B550M board just to resurrect that still-working 3600 so it can run two self-hosted runners side by side.
Before I knew it, I had cobbled together a home-brewed CI pool: the 2014 i5-4690, the resurrected Ryzen 5 3600, a Mac mini M4, a dual-boot N100 mini PC, plus my main R7 7700 rig doing part-time shifts. Building software with AI agents somehow turned into playing sysadmin for a closet full of mismatched hardware.
I used to look at PC specs and think about frame rates. Now I look at a box and calculate which test suite it should take, whether it has enough RAM for two concurrent runners, and how to keep it from stealing cycles from my main workstation. Whether the money I save on GitHub Actions gets completely eaten up by the hours I spend sourcing spare parts and babysitting environments is still an open question. After spending the last few days flashing ISOs and debugging runner environments, I already feel the tradeoff.
As for the R7 7700 main rig that finally got freed up from full-time CI duty, I just bought a Ryzen 9 9950X to drop into it. That is going to be another rabbit hole entirely.


Agent Memory, part 5 of 8: reliability.
A summary can turn a suspected cause into a remembered fact.
"Possibly the old API; not confirmed" becomes "the old API caused the incident."
In this example, the uncertainty disappeared during summarization.
For that record, I'd want the evidence, scope, and uncertainty alongside the conclusion.
A source link lets me inspect what was said. It doesn't establish that the claim was true.
If the source says "possibly," the saved lesson needs to preserve that.
Corrections need to reach derived records, too.
Fixing the original note can leave an older summary untouched. The agent may retrieve that summary and reuse the stale conclusion.
I'd trace which summaries and decisions depended on the corrected claim.
The HaluMem figure separates checks for extraction, updating, and question answering. Those checkpoints help locate where an error entered the process.
Figure: HaluMem, Fig. 2 (v3).
arxiv.org/abs/2511.03506
I'd also test in a new session: does the agent use the latest valid information to make a decision? Recalling a sentence in the same conversation is a narrower check.
Full article, part 5 of 8:
chichieh-huang.com/en/writin…
Next in this eight-part series: deliberately planted memories. Can a document claiming approval become authorization?

4
4
98
I asked Gemini just ONE question about the Argon model, and it burned through 29% of my quota.
And I was only using low thinking mode. Damn.
1
45
real sources can still produce a false claim.
an agent once gave me an industry figure with an institution and a year. i nearly used it. the number belonged to another report, and the year was wrong.
now i check which claim the source actually supports. a link alone isn't enough.
1
37
a memory update can end with an unanswered question.
if i've told an agent my old address is no longer valid, but haven't given it a new one, it should ask before shipping anything.
retiring the old answer doesn't create a new answer. i'd want the memory system to preserve that gap.
3
48
more context didn't save me much review time.
i had put my workflow into memory.
the output got more complete, but I still reread the whole thing before using it.
i had written down how to do the work.
my criteria for accepting it were mostly still in my head.
29
J Huang retweeted

Day 16/
You can now cache for 12h in the API and for logged in users across Codex & Work we keep cache forever and you don’t have any penalty for coming back to an old conversation or resuming after a few hours and are now guaranteed to hit the cache.

put my entire workflow into memory thinking it would save review time
the output got way more thorough and i still reread the whole thing anyway
i documented how to do the work, but the definition of "good enough to ship" was still completely in my head
32

Wanting ramen today and avoiding beef long term need different memory decisions.
Both can matter for lunch. Keeping today's craving as a lasting preference can mislead next month's recommendation.
Agent Memory, part 3 of 8: what deserves to be remembered?
The survey Memory in the Age of AI Agents groups memory by function:
Factual: preferences and environment facts.
Experiential: lessons from prior tasks.
Working: current task state and open questions.
One record can serve multiple roles.
The diagram links all 3 to action.
Remembering a pollen allergy doesn't prove an agent will use it when planning a picnic.
It may answer a direct question about the allergy correctly and still miss it during planning. I'd check the proposed activity as well as the recall answer.
Retention depends on the job, too. Today's lunch may belong in a long-term food log even when it shouldn't become a stable preference.
Full article, part 3 of 8:
chichieh-huang.com/en/writin…
Next: updating memories when the world changes.
🤖 Made with AI

1
116
"the agent rewrites its own harness" sounds clean until mine does it. last time it "improved" its memory it quietly dropped every why-I-said-no note and got really confident about the wrong plan 😅

This paper might change how every AI agent gets built.
Google just published Harness², a system where the agent rewrites its own harness for each task.
The model stays the same. The prompts, tools, memory and skills around it get better.
How it works:
1. Propose. The agent runs the task once, then drafts two edits: one for general weak spots like planning and tool use, one for the domain.
2. Probe. Each edit runs on the same task and gets compared with the original run.
3. Compose. It keeps only the changes the comparison supports.
No answer key needed. That’s the hard part, because real work rarely comes with one.
Every lesson goes into a library with its own EXPERIENCE.md, so the next task starts from what worked.
GLM-5, an open model, scored 75.7 on workplace tasks after a single step. Gemini 3.5 Flash on its default harness scored 72.4.
A cheaper model with a better harness beat a stronger one.
The repo is the full framework, open source. It plugs into OpenCode or Codex and edits 8 parts of the harness: system prompt, guardrails, memory, skills, tool guidance, scripts, subagents and plugins.
Repo: github.com/google-research/h…

1
1
33