




Pinned Tweet
We’ve been cooking!
And so much more to come in the following weeks

Today, we are open-sourcing the Innate OS, the intuitive agentic OS for general-purpose robots
🎮 Try it today in our simulator and make the smartest robot
⬇️ Here is a demo with two robots collaborating
We are entering the physical agents era, but building for mobile robots is still reserved for PhDs. We designed the Innate OS for intuitiveness, so that everyone can start automating their lives.
Innate OS runs on our <$1k open-source robot or on your computer. It takes just a minute to build your first agent in our simulator.
David Dobáš retweeted

This thing is going in the right direction.
World models really need some form of tool use, especially external memory.
You can already see this with LLM plan modes. They write plans or .md files, then keep coming back to them while working through a long task.
Humans do the same thing all the time. Pen and paper are basically an extension of our working memory. Try solving a hard math problem without being allowed to write anything down and you immediately feel the difference.
Attention is also not a perfect way to retrieve information. With long contexts, models can lose track of important details or struggle to find the right information again. So if we want reliable long-horizon reasoning, we probably need other ways for models to store, update, and retrieve information.
I think this is especially important for world models. If you want long, consistent rollouts, the model needs some persistent representation of the world’s geometry that it can update over time. Otherwise it has to keep reconstructing the spatial state from context at every step.
Maybe that representation looks like Gaussian splats, 3D meshes, or something else entirely. I don’t think we know the best answer yet. But some kind of persistent, editable spatial memory feels necessary.
That said, these meshes would need to be generated on the fly. As the world model generates a scene, another model would need to distill the relevant spatial information into meshes it can reuse later. This is a highly non-trivial problem. I think current LLMs might be capable of it, but they’re probably too slow for real-time use. I’d still love to see an experiment, even at a few frames per second :)
xitter.cf/willemhelmet/status/21…

Reactor is now running in @Blender ! VAST's EdenLive is a perfect fit for running realtime AI video directly within the viewport. It's so easy to try different styles using the same consistent environment geometry. Send me a DM if you want to install the plugin yourself!
David Dobáš retweeted

This demo from Reactor.
This is a video of me folding a shirt inside of a world model, with VR Joysticks. It was an incredible feeling, made me realize how close we are to a perfect modeling of the world.
You should get to experience it yourself.
reactor.inc/cosmos-bimanual
No VR joysticks needed BTW

Introducing NVIDIA Cosmos-3-Nano on Reactor. Two new models, available now via the Reactor API.
• Sim-Bimanual predicts what a robot sees as you move its arms and grippers.
• Sim-Transfer turns simulations into photorealistic video.
Try them now: reactor.inc/cosmos-bimanual
David Dobáš retweeted

Game changer for humanoid full-body control training. Now it's superfast (and cheap, just one GPU) to train a single policy on *all* the motions. How come:
(1) World model much faster than regular sim
(2) Backprop through time collects way more signal than policy gradients

We found a way to scale humanoid control that reduces GPU-hours by more than 1000×.
Across 129,514 motions, SuperMimic surpasses the state of the art (128 GPUs, 7 days) with 1 GPU in 3 hours.
Project: supermimic.github.io
Demo: supermimic.github.io/demo/
David Dobáš retweeted

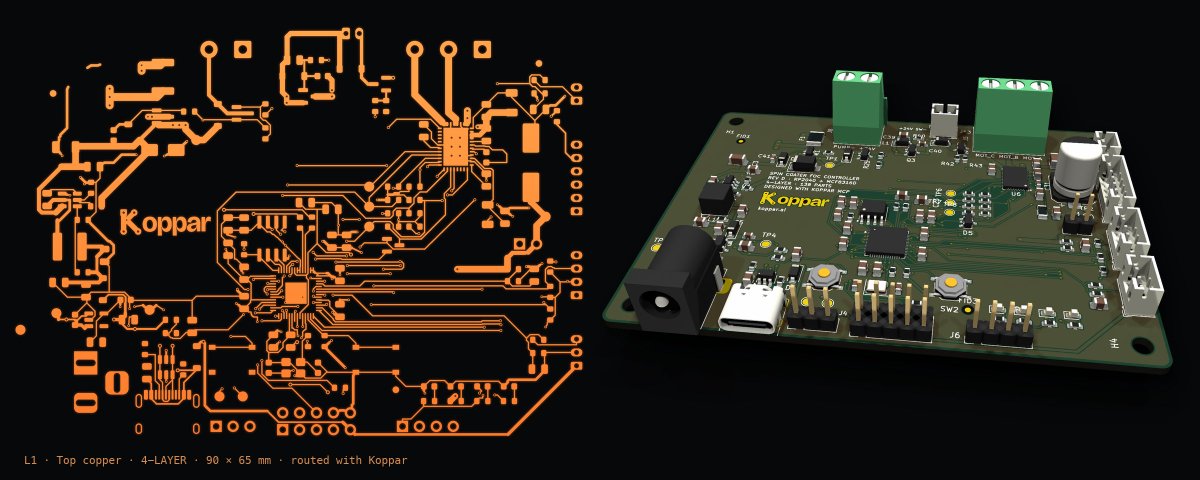
A board that is 98% connected isn't a board. It's a drawing of one. I built an automated KiCad router and MCP that turns text into a DRC-clean PCB, only to learn waitlists are where projects go to die. So I scrapped it and opened it up:
David Dobáš retweeted

you can now train your @innate_bot mobile robot with @LeRobotHF in one line
Fully open-source!
on innate-os:
𝚞𝚟 𝚛𝚞𝚗 𝚕𝚎𝚛𝚘𝚋𝚘𝚝-𝚝𝚎𝚕𝚎𝚘𝚙𝚎𝚛𝚊𝚝𝚎 --𝚛𝚘𝚋𝚘𝚝.𝚝𝚢𝚙𝚎=𝚖𝚊𝚛𝚜

David Dobáš retweeted

Teaching a robot a new skill is a lot messier than the final demo makes it look.
Lots of failed grasps. A few unexpected mistakes and eventually, moments where it actually works.
This is what learning in the physical world looks like with MARS from @innate_bot
David Dobáš retweeted

What can a robot do without vision?
We gave our robot a sense of touch and showed it can recognize and retrieve objects with its cameras blindfolded.
Introducing Rhoda’s new tactile sensor—it feels pressure, texture, vibration, slip, and temperature, just like your fingertips.
David Dobáš retweeted

Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.

Judging by my tl there is a growing gap in understanding of AI capability.
The first issue I think is around recency and tier of use. I think a lot of people tried the free tier of ChatGPT somewhere last year and allowed it to inform their views on AI a little too much. This is a group of reactions laughing at various quirks of the models, hallucinations, etc. Yes I also saw the viral videos of OpenAI's Advanced Voice mode fumbling simple queries like "should I drive or walk to the carwash". The thing is that these free and old/deprecated models don't reflect the capability in the latest round of state of the art agentic models of this year, especially OpenAI Codex and Claude Code.
But that brings me to the second issue. Even if people paid $200/month to use the state of the art models, a lot of the capabilities are relatively "peaky" in highly technical areas. Typical queries around search, writing, advice, etc. are *not* the domain that has made the most noticeable and dramatic strides in capability. Partly, this is due to the technical details of reinforcement learning and its use of verifiable rewards. But partly, it's also because these use cases are not sufficiently prioritized by the companies in their hillclimbing because they don't lead to as much $$$ value. The goldmines are elsewhere, and the focus comes along.
So that brings me to the second group of people, who *both* 1) pay for and use the state of the art frontier agentic models (OpenAI Codex / Claude Code) and 2) do so professionally in technical domains like programming, math and research. This group of people is subject to the highest amount of "AI Psychosis" because the recent improvements in these domains as of this year have been nothing short of staggering. When you hand a computer terminal to one of these models, you can now watch them melt programming problems that you'd normally expect to take days/weeks of work. It's this second group of people that assigns a much greater gravity to the capabilities, their slope, and various cyber-related repercussions.
TLDR the people in these two groups are speaking past each other. It really is simultaneously the case that OpenAI's free and I think slightly orphaned (?) "Advanced Voice Mode" will fumble the dumbest questions in your Instagram's reels and *at the same time*, OpenAI's highest-tier and paid Codex model will go off for 1 hour to coherently restructure an entire code base, or find and exploit vulnerabilities in computer systems. This part really works and has made dramatic strides because 2 properties: 1) these domains offer explicit reward functions that are verifiable meaning they are easily amenable to reinforcement learning training (e.g. unit tests passed yes or no, in contrast to writing, which is much harder to explicitly judge), but also 2) they are a lot more valuable in b2b settings, meaning that the biggest fraction of the team is focused on improving them. So here we are.
David Dobáš retweeted

Late to the party, but this surprised me: gave GPT-6 Astra control of an Innate MARS robot with one prompt. No code, no task setup. Full nav + manipulation on its own. Picked its own sensors, found the purple ball, and put it in the dish.
Video at 2x. @innate_bot @OpenAI


One of the best recent robotics blog posts, and now it's open source

David Dobáš retweeted

Doing proper science in robotics is hard, because human demonstrations are expensive and less controllable.
OCBench is a new benchmark providing "human-like" scripted policies. This enables scientific studies of BC and RL with virtually unlimited data!
Cursor came to visit

Innate is a team of 7 building capable robots for everyday life.
"The seven of us here do the work of 50," says Vignesh Anand, co-founder of @innate_bot.
We spent time with the team to capture what building means to them.
David Dobáš retweeted

This seems like a good time to announce I have officialy joined Innate, really exciting things are coming
Innate is a team of 7 building capable robots for everyday life.
"The seven of us here do the work of 50," says Vignesh Anand, co-founder of @innate_bot.
We spent time with the team to capture what building means to them.
David Dobáš retweeted

Innate is a team of 7 building capable robots for everyday life.
"The seven of us here do the work of 50," says Vignesh Anand, co-founder of @innate_bot.
We spent time with the team to capture what building means to them.
David Dobáš retweeted
AI has officially entered the physical world in my apartment.
Meet MARS from @innate_bot Now the fun part begins: building, experimenting, and seeing what this thing can actually do.
David Dobáš retweeted
LLMs enjoy writing tests, I think in their training pipelines they get rewarded for that, here’s how to find balance

First results: @bfl_ai Flux 3 Action doing mobile manipulation on @innate_bot MARS 👇
We finetuned the SO101 checkpoint and replaced the action head with our 8DoF (5 arm, 1 gripper, 2 base)
Generated synthetic episodes in innate-os sim, with randomised positions and height of the box
innate-os sim is great for these experiments, try it out!
github.com/innate-inc/innate…
