

Software & AI engineer. Introvert who ships. Building in public.
Joined March 2023
- Tweets542
- Following539
- Followers146
- Likes485




Pinned Tweet
AI agents can think. They still can't pay.
So I built Loki: an MCP server that lets your agents send M-Pesa payments and use virtual cards, inside the caps, budgets and allowlists you set.
Built on @SafaricomPLC Daraja. Sandbox-tested. Waitlist below.
#MPesa #AIagents #MCP
Hot take: the hardest part of shipping an AI agent isn't the model. It's deciding what it's allowed to do without asking.
Read-only tools: let it run.
Writes you can undo: log it and move on.
Anything that moves money or messages a real person: stop and confirm.
Where do you draw that line in your agents?
Officially stepped into the CTO role at RecruitScout. We're building AI that matches recruiters with the right people, plus a stack of agent tools on the side (Stratum, JobMatch). I'm sharing the longer build notes on LinkedIn too, so connect if that's your thing: linkedin.com/in/fredrick-oti…


Most AI strategy tools write a confident answer and stop.
In Stratum (stratumsys.online), every claim must cite a source from your Drive, Notion or PDFs. Then a red-team agent attacks the recommendation before the PowerPoint export.
An adversary agent beats a smarter prompt.
Agents retry. Payment APIs time out. Put those together and you get a double charge.
In Loki, every payment call from an agent carries an idempotency key, so a retried request returns the original result instead of paying twice.
Retries should be boring, not expensive.
I've been building Nimbus, a personal AI agent that runs tasks for you instead of just chatting.
The model call is the easy part. The hard design question is where "just do it" ends and "ask me first" begins.
The rule I'm designing around: reads can run on their own. Anything that sends, pays or deletes waits for a yes.
Where do you draw that line?
An AI consultant that can't show its sources is just a confident guess.
In Stratum, every finding links back to the exact doc it came from: a Drive file, a Notion page, a PDF. Then a red-team pass tries to break the conclusions before anything gets exported to PowerPoint.
Citations first, slides second.
stratumsys.online
AI agents retry. A lot. If the payment tool doesn't expect that, a timeout becomes a double charge.
In Loki, my MCP payment gateway (sandbox), every pay call carries an idempotency key. Same key, same answer: a retry gets the original transaction back, not a second charge.
A rule for personal AI agents (it's how I think about Nimbus, the agent app I built):
If the action can be undone, just do it.
Read, search, draft, summarize.
If it can't, show the plan and wait for a yes.
Send, pay, delete, publish.
Autonomy is easy to add. Trust is the actual product.
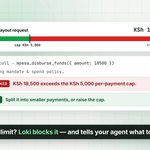
Loki (my MCP payment gateway for agents, sandbox for now) enforces spending caps in the server, not in the prompt.
If the cap lives in the system prompt, one clever tool output can talk the agent past it.
If it lives in the server, the agent can ask all it wants. The call returns CAP_EXCEEDED and nothing moves.
Rules the model can't edit beat rules the model is asked to follow.
Most AI research tools start searching the second you hit enter.
In Stratum I put scoping first: an agent turns the vague ask into the specific questions the client needs answered, before anything touches Drive, Notion or PDFs.
Bad scope gets you confident answers to the wrong question.
stratumsys.online
Agent output is only useful if a human can check it fast.
In Stratum, the AI consulting tool I built, each finding carries its source: the Drive doc, Notion page or PDF it came from. A red-team agent then attacks the findings before they reach the deck.
Show the receipts, then argue with them.
stratumsys.online
Your MCP tool description is a prompt the model reads before every call.
Say when NOT to use it, not just what it does:
"send_payment: moves real money. Don't call it to check status, use get_payment_status. Amount is whole KES."
Plenty of wrong tool calls start with a vague description.
MCP tool errors are part of the prompt.
Don't return "payment failed". Return what the agent can act on:
code: CAP_EXCEEDED / INVALID_RECIPIENT / PENDING
retry_safe: true/false
next_step: ask user to approve, or query status in 30s
A vague error makes the agent guess. Guessing with money is the bug.
Money in an MCP tool schema: never accept a float.
amount: integer, in the smallest unit the rail takes (M-Pesa wants whole shillings)
currency: required, no default
phone: E.164 only, validated before anything reaches M-Pesa
idempotency_key: required, not optional
A model will happily send 149.99999. Let the schema say no.
If an AI agent can spend money, give it a ledger it can't write to.
Log every payment call: agent ID, tool, args hash, idempotency key, cap before/after, M-Pesa receipt or error code.
Append-only. The agent reads it, never edits it. Then "why did it pay?" has an answer.
M-Pesa callbacks can arrive twice, late, or never. If an agent is paying, design for that:
- dedupe callbacks on CheckoutRequestID
- expose states: pending, paid, failed, uncertain
- query status on anything stuck in pending
The agent should never guess whether money moved.
An AI agent that can pay should leave a trail you can replay.
Log every payment tool call with:
- which agent token called it
- args + idempotency key
- cap check result
- M-Pesa receipt number
When something looks off, read the log, not the model's memory.
Give a payment agent a dry-run tool before the real one.
preview_payment(to, amount) returns:
- recipient name as the network resolves it
- fee
- cap left today
- whether it needs human approval
No money moves. The model checks it, the human sees the same preview, then pay() runs.