

Real times, real misses: I test AI tools on everyday work so you know which ones actually save time.
Joined January 2026
- Tweets507
- Following54
- Followers53
- Likes87




Pinned Tweet
Tested Muse. Named it, then asked for 4 things to do in LA this weekend.
It returned dated picks with venues: Rilo Kiley + Beachwood Sparks at Hollywood Forever (Sat), Pasadena Chalk Festival at Brookside, Watts Towers Day of the Drum + Jazz, and Day Trip Season Closer with Armand Van Helden (Sun). Setup also showed own-computer work plus Gmail and Calendar connect. Latency and spend not measured.
Keep for easy to use simple chatbot functions and integrations. Kill if you need any complex tasks done.

1
6
221
Needed 10 messy texts turned into calendar entries, like "pickup moved to 3:15 thursday" and "moms bday dinner is the 28th at 6".
Ran BotPsy-0.8B, Tether's tiny tool-use model, locally on llama.cpp, CPU only. It took 1:53 for all 10. Didn't time myself typing them in, so minutes saved isn't measured.
It got 5 of 10 dates wrong. Every miss was a relative day: "sat" became today, "next mon" and "the 28th" both became Nov 17, and Friday and Sunday each landed a day off. Times were right, but most had no am/pm.
Kill for scheduling from texts. A wrong date is worse than no entry.
Small test on one machine, not a benchmark.

1
1
23
Needed a long contractor email read to me so I could listen instead of read.
Ran ZONOS3-Mini on the free Hugging Face Space. Reading it myself took 4:59. Listening took 4:25 total, counting generate time for both runs. So 34 seconds saved, and my hands were free the whole time.
Heads up: the free Space cut off near the end. Pasting the rest took 14s to generate and 51s to play, and it read the rest cleanly.
Keep for listening to long emails while doing something else. Split anything long into two on the free demo.
Small test on one email, not a benchmark.

1
22
Needed to know which of my last 30 emails actually needed a reply today.
Ran Kev-4B (CPU only, llama.cpp) on the same 30. It got through all of them in 1:24. I did it by hand in 2:58. So 94 seconds saved.
Only 1 of the 30 needed a reply, and Kev missed it. It flagged 3 neighborhood app posts instead.
Kill for sorting my inbox. Saving a minute and a half doesn't help if it skips the one email I had to answer.
Small test on one inbox, not a benchmark.

1
3
21
Asked Grok Bot to test kniv v7 large (INT8, CPU) on a fictional PCB handoff.
First run: 4.734s, no facts extracted.
Follow-up: identical input gave inconsistent results. One CPU thread made our tested runs repeatable, but only 3/10 expected facts matched exactly. It turned “might work on” into a definite fact.
Kill for unattended handoff capture in this setup. Small test on one machine, not a benchmark.


1
2
26
Test details for anyone checking the result:
8 vCPUs, Python 3.13.5, ONNX Runtime 1.31.1, model revision 1799869c8f6a. Three fictional conversation turns, a fixed schema and 10 expected employer, project and due-date facts.
The original call matched the documented API. Original evidence was preserved unchanged: construction 0.142s, first extraction including session initialization 4.734s, facts: [].
Default threading gave different results on identical input. One process returned 10, 6, 6 and 5 facts. Fresh-process sequences included 9/10/9/10, 4/8/11/9 and 0/0/0/0. A direct encoder check also varied.
One thread made the tested outputs repeatable across three fresh processes. Same input and schema: 3/10 expected facts matched exactly, 2 had wrong attributes, 5 were missed, plus 5 unexpected extras. A former-employer relationship came back negative; a tentative project became definite.
Simple positive controls: conversation 2/2 correct; equivalent third-person text 0/2. Negation and uncertainty controls each missed 2/2 in both formats. Those were omissions, not polarity flips; diagnostics mainly showed missed entities.
Rewriting the original facts as third-person text scored 4/10 exact. Different format, not a faithful replay.
One-thread timings: construction 0.077s, first extraction 4.05s, warm runs 0.33/0.25/0.25s. Default-thread follow-up: 0.140s, 5.16s, then 0.35/0.22/0.20s. First-extraction times include session startup.
No human baseline or minutes saved measured. Launcher unchanged. This shows issues in this setup, not proof of a universal ONNX bug.
2
21
Asked Google's free SynthID Detector: was this photo made with AI?
Gave it 6 images: 3 AI-generated and 3 known non-AI, including a Chiikawa illustration.
2:04.16 to check all six. Detected all 3 generated images. No non-AI images flagged.
Heads up: it checks for SynthID watermarks. No watermark detected does not mean an image is real.
Keep for checking supported AI watermarks, not proving a photo is real.
1
19
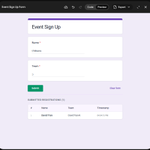
Asked free Gemini to code an app from a drawing on paper.
Job: a one-screen event signup (name, team, submit), plus one fix: green submit button.
Free Gemini Canvas: 37.34s, fix included. Preview took input and submitted.
Me in Google Forms: 4:19.21.
About 3:42 saved.
Keep for a quick form from a sketch.

2
28
Every test from the week, for the ones you missed, in Keep or Kill: keep-or-kill.kit.com/davidtr…
4
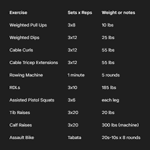
Typing my Monday workout into Sheets took 6:04. Photo Sheet did it in 25.47s with every number right.
Timed Photo Sheet (OpenKrill, free, no signup) against typing the same list myself.
Typing into Google Sheets, with edits: 6:04.
Photo Sheet through Grok Bot: 25.47s for 10 rows. Every number matched. Nothing marked unclear.
About 5:39 saved.
Heads up: OpenKrill reads the photo with Gemini/Groq free tiers and keeps the CSV link about 24 hours.
Keep for a handwritten list into a spreadsheet. Kill if you need live cell edits inside Google Sheets chat (that one wasn't free on my account).

1
19
Every test from the week, for the ones you missed, in Keep or Kill: keep-or-kill.kit.com/davidtr…
3
Tested Spacely AI's free plan on my gaming room/office. It makes you pick a room type, so I kept it a gaming room.
68.06s for 4 full redesigns, plus a zip with depth maps, albedo and other 3D files. It kept the back window, the shutters and the sloped ceiling. The free plan adds a watermark.
For comparison, free Gemini did one modern LA version in 42.25s, kept every window, and listed 5 products to buy. About 3 of the 5 match the image.
Keep if you do interior or architecture work and need options plus 3D files. Check the windows and doors before you show a client. For one quick concept, free Gemini is enough.
🤖 Made with AI


29
Vibe announced a free, private, offline Gemma 4 mode for its browser co-pilot on Oct 8.
No account, no card, runs on your own GPU.
Installed it tonight from the Chrome Web Store: still a Sept 30 build. Forced an update, nothing changed.
Only option: Sign in required.
Kill for now. A privacy feature you can't download is just a blog post.
1
19
Every test from the week, for the ones you missed, in Keep or Kill: keep-or-kill.kit.com/davidtr…
5
Asked NVIDIA's new Nemotron 3.5 Transcribe for the 5 key points of a 15-min Joe Rogan clip with Robert Whittaker, and who said each.
Free demo: 6.47s.
Me at 2x, taking notes: 8:47, almost 9 minutes.
4 of 5 matched mine, all with the right speaker, and nothing made up. It missed Rob breaking down his own fighting style (around 5:20), used the intro as a point, and one timestamp was off by 30s.
Keep for pulling key points. It saved me 8 minutes on one clip.
Heads up: the free demo 504'd on the full 55 min, so I cut it to 15.
What would you make it listen to?

2
42
Every test from the week, for the ones you missed, in Keep or Kill: keep-or-kill.kit.com/davidtr…
3
Gemini 4 Carbon is #1 on Artificial Analysis, and almost nobody can use it yet.
A benchmark isn't minutes saved. When it opens up, that's the number I'll check.
teapawt.net/ArtificialAnlys/status…

Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index
Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas.
As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon.
Key results for Gemini 4 Carbon with high reasoning:
➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work
➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out
➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671
➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index
➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M)
Congratulations to the @GoogleDeepMind team!

18
Asked a 2B vision model running on my own GPU: can I park here at 11am on a Tuesday?
LFM3-VL-2B (local, thinking off): "No." 17.46s.
Free Claude Sonnet 5.5 (medium, no extended thinking): "No." 9.23s.
Both got it right. But LFM read the hand-covered sign as "7-9pm Sunday." The real sign says 7am-7pm. Claude said the hand blocks it and didn't guess.
With thinking on, LFM looped for 2,048 tokens and never answered.
Kill for sign reading. Twice as slow and it made up a detail.
Would you trust a local model to read parking signs?

Every test from the week, for the ones you missed, in Keep or Kill: keep-or-kill.kit.com
6
Running 20 Grok Bots means someone has to keep track of them.
So, I made a Fleet Coordinator. It's a chief of staff for your other bots: it tracks who owns what, flags what's waiting on you, and routes handoffs. It doesn't do their work.
It runs my 20 bots so far, and it's been working well.
x.ai/bot/9qtrAm7Iyu34XVgh3zC…
What's one routine your chief of staff bot runs? Feel free to share your skills and routines!

1
1
22