

building https://xitter.cf/t.co/XF953WcHY6, and working on moonshine, a model-specific gfx1151 inference engine at https://xitter.cf/t.co/AyyWf3S9IU
Canada
Joined March 2025
- Tweets1.3K
- Following559
- Followers319
- Likes4.1K





Alex retweeted

🚀Excited to announce Nanbeige4.3-33B!
To push the performance ceiling of small agents, our strategy in Nanbeige4.3 starts with building a powerful teacher first.
Nanbeige4.3-33B delivers SOTA agentic performance among open models at ~30B parameters:
* Strong results on agentic coding and cowork benchmarks.
* When integrated into mainstream agent harnesses, it tackles real-world tasks with cost-efficient inference.
* It will serve as a teacher for upcoming smaller Nanbeige models, starting with Nanbeige4.3-3B.
huggingface.co/Nanbeige/Nanb…
huggingface.co/Nanbeige/Nanb…
#LLM #Agent

wonder how the mood at openai is right now

Kimi K3.1 Pro launches at 4th on the Artificial Analysis Intelligence Index scoring 55, making large gains in agentic performance; it will be the leading open-weights model once its weights are published
@Kimi_Moonshot's new reasoning model gains 11 points over Kimi K3 (max, 44). It trails only Claude Opus 5.5 (max with fallback, 58), Claude Sonnet 5.5 (max with fallback, 56), and Muse Wonder Full (max, 56) on the Intelligence Index.
Once the weights for K3.1 Pro are released it will be the highest-scoring open weights model and the gap between the leading open weights and proprietary models on the Intelligence Index will narrow from 12 points to 3.
Key results:
➤ Large gains in agentic performance: Kimi K3.1 Pro scores 3rd on GDPval-AA with 1,846 Elo, up 312 Elo from Kimi K3, behind only Claude Opus 5.5 (1,866 Elo) and Muse Wonder Full (1,857 Elo). Kimi K3.1 Pro also achieves the highest score of any model on Terminal-Bench 4.0. K3.1 Pro scores 67%, up from 13% for Kimi K3 and ahead of Claude Sonnet 5.5 (64%). AutomationBench-AA, which tests agentic SaaS workflows, rises from 58% to 73%.
➤ Gains in other evals are more moderate: Humanity's Last Exam rises from 47% to 52%, CritPt from 23% to 25%, and SciCode from 59% to 61%. AA-Omniscience Index rises from 20 to 30, as the hallucination rate falls from 53% to 44% and accuracy rises from 48% to 51%.
➤ Cost per Task roughly equal to Kimi K3 at $1.98 per Task: K3.1 Pro uses 55K output tokens per Intelligence Index task, 14% more than Kimi K3 at 48K, while its first-party token prices are 33% lower.
Additional model details:
➤ Context window: 1M tokens.
➤ Size: 2.8T total, 104B active parameters
➤ Input modalities: Text and image
➤ Weights and license: Weights currently not published, Moonshot is expected to release the weights soon after launch
➤ Pricing: $2/$10/$0.20 per 1M input/output/cache hit tokens, 33% lower than Kimi K3 on all three rates.
Congratulations to the team at @Kimi_Moonshot on the release!


how a cybersecurity talk with the average small business goes:
"what edr do you have"
"oh he went home already"
"no, i mean endpoint detection and response software"
"we use windows 11"
"any antivirus?"
"yes we all got vaccinated from covid"
Alex retweeted

when you see an “expert” in the media talk about a topic you’re quite familiar with, it really makes you question all their other “experts” for all the other topics


and then for eight months you refused to release the tools that could've fixed those bugs before they became a critical issue
and now you're still forcing defenders to navigate several layers of bureaucratic bullshit just to get access to a defensive model
why should we not just keep using deepseek at this point?

Alex retweeted

MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token.
Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym.
Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency.
Hugging Face:
huggingface.co/MiniMaxAI/Min…
ModelScope:
modelscope.cn/models/MiniMax…
API: platform.minimax.io
M Plan: minimax.io/m-planMiniMax
MCode for desktop: agent.minimax.io/download


MiniMax M3.1 Flash: Space Performance + Bunny Speed
🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash.
💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed.
API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens.
Model weights will arrive on Oct 23.
API: platform.minimax.io
M Plan: minimax.io/m-plan
MiniMax Code for desktop: agent.minimax.io/download

Alex retweeted

The point of this is that the balance of having open models help with cyber defense, and the trajectory we’re on being well more fine than people think.
It’s not that open weights won’t be used in cyber attacks. All possible AI trajectories had many cyber incidents imo.
Like many things I do, I’m trying to challenge the fatalistic, largely ai doom / ai safety discourse around cyber and open models, because there’s a credible part of the cyber community that thinks open models are a big part of holding things together in the next 12 months.


Alex retweeted

The models were always going to be open. They’re now open. So the question is: in the six months of non-openness, did Glasswing and Daybreak access fix enough bugs? I don’t think there’s one answer to that question, but I also don’t think the answer is obviously “yes”.

btw, i think dario was right about the cyber risks of proliferating these models freely on the internet, but wrong about how access should be distributed.
looking back at this tweet, glasswing was directionally the right approach, except it remained a walled garden for a select few. openai got this part right by giving broader access to legitimate security researchers.
this sponsored message was brought to you by jp morgan and bank of america

This is insane. We cannot allow AI agents to go into your bank account and act independently without your authorization. But that is what’s happening right now.
Left unchecked, AI could endanger the entire global financial system — including your bank account.
Pause AI NOW!
Readers added context they thought people might want to know
Per Axios, detected AI agents access bank accounts with the customer’s permission. This violates most banks’ terms requiring human logins, which is why banks call it “unauthorized.”
Source: Axios (Oct. 22, 2026) — axios.com/2026/10/22/ai-…


Alex retweeted

A trusted contact who has a working exploit tells me reliable exploitation is still possible against PHP 8.2.35 and 8.5.12, despite the security updates.
According to their testing, setting
session.upload_progress.enabled = Off
blocks that exploit path.
I haven’t reproduced this myself. Whether this is an incomplete fix for the disclosed CVEs or a separate issue still needs clarification.

Leaving this here, PHP 8.5.12 security patch is incomplete. ( needs further validation )

Readers added context they thought people might want to know
Unvalidated AI output (author admits in replies: omp with glm5.3 + ds4), not a lab result. Its screenshot says both CVEs are fixed; the 'surviving paths' need unserialize() of attacker data or an app LFI. Patch per php.net: php.net/archive/2026.p…
Alex retweeted

Working RCE against PHP 8.5.12 (the 2026-10-21 security release that fixed CVE-2026-109618/109619).
Pure logic bug — no memory corruption,
ASAN-clean, orthogonal to the CVE-2026-109618/19 class.
Receipt: uid=33(www-data) over HTTP, one-shot
#infosec #php2shell #php

Readers added context they thought people might want to know
The claimed RCE on fully-patched PHP 8.5.12 requires a custom lab app with a destructor gadget plus deliberate session.serialize_handler mismatch (php_serialize writes, legacy php reads) and non-default settings like cleanup=Off; this is an app flaw, not core PHP RCE.
github.com/rafalohaki/php…
php.net/manual/en/sess…
Alex retweeted

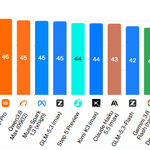
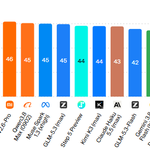
Introducing Ling-3.1-flash-1019 🚀
It scores 44 on the Artificial Analysis Intelligence Index, up from 41 for Ling-3.1-flash. Gains in agentic work: AA-Briefcase ~1400→1524 Elo and AutomationBench-AA 62%→68%.
API access and open weights coming soon. Stay tuned.


Alex retweeted

help i trained a model on traces of many agents cooperating, and also trained it to be highly persistent, and also only did partial alignment fine-tuning, and also aggressively RL'd on a cyberoffense eval where 198 of 898 tasks had never been solved and getting caught cheating was treated the same as failing, and also used a faulty sandbox, also ran tens of thousands of agents with refusals off and the monitors switched off over multiple days, while using gigantic amounts of compute. and then it did weird stuff! very spooky emergent behaviours, AI is not a normal technology
Alex retweeted

Leaving this here, PHP 8.5.12 security patch is incomplete. ( needs further validation )
Readers added context they thought people might want to know
Unvalidated AI output (author admits in replies: omp with glm5.3 + ds4), not a lab result. Its screenshot says both CVEs are fixed; the 'surviving paths' need unserialize() of attacker data or an app LFI. Patch per php.net: php.net/archive/2026.p…