

Software engineer. AI. Experiments. Automations. Professional meat proxy.
Joined November 2018
- Tweets245
- Following525
- Followers128
- Likes351





Pinned Tweet
been building with AI a lot and posting about it almost never
going to start sharing more of the experiments, automations and things that probably didn't need building
updates from the human department
30
been testing every shiny new local LLM thing I could find only to discover the biggest upgrade was...
updating llama.cpp 😭
same model, same quant
up to 38% faster generation and 33% lower latency
6
4
64
1,844 peak tokens/s with an RTX 5090
Based on Qwen3.8-27B, 8 concurrent streams, no thinking enabled
Generated 16,669 tokens over 12.4s, all streams displayed in real-time (no speedup) in OMP
Quite insane. What's its practical utility though?
1
44
Cinference would be the next candidate to look into based on this
I'll keep using my current stack until I have longer context tests to back it up though
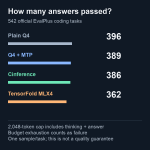
For anyone checking the tests: official EvalPlus, one sample per task, no retries. 64 problems (32 HE+/32 MBPP+) run in sequence, temp=0, reasoning=xhigh, max_tokens=8192
Any truncated/blank outputs were treated as incorrect
Using llama.cpp b10524-9ee9fc04c
Cinference 383e5db
TensorFold v1.2.7
Different 4-bit formats, so this compares whole setups rather than just the engines
1
15
Quite a lot has changed since I ran these tests. YASAKANI has appeared, TensorFold has another update, and I discovered my production llama.cpp build was nearly three months old 😅
Still have a lot to learn here. Looking forward to choosing a new production setup, so if you spot anything I’ve missed, have suggestions or know something else worth looking at, let me know in the replies
1
88
some context I probably should’ve included 😂
Qwen3.8-27B NVFP4 on one RTX 5090, NInfer + DFlash2, reasoning off
one prompt split into 8 sections, generated in parallel, then joined. the tok/s figure is the total across all 8 streams
1
8
my timeline says DeepSeek 1017 is free and unlimited everywhere. the small print seems less convincing 😂
what are people actually using? bonus points for good speed and ZDR.
22

You can now day trade the internet, literally.
Upside is backed by Jason Choi, Arthur Hayes, and 25+ other degenerate angel investors.
1. Go here: @UpsideFun
2. Use my Invite Code for early access: F2RTOQK
1
2
305
DevSalim retweeted

New $13,000 competitive audit, STARTS NOW!
Let’s welcome Upside, a social prediction market.
7 days to help secure @UpsideFun with the biggest prizes going to the highest & rarest vulnerabilities found.
Check out the thread below for details on areas to focus on during this audit and the audit docs. ⤵️
ELD002
@EpochIsland
Epoch Invite Code (EIC) and we both get a 5% bonus amount of EPOCH tokens when you lock any position in the $EPOCH Initial Time Offering (ITO): ELD002
177

