PhD student in robotics @Stanford | Ham radio (BI1NWO; AI6OT) | Prev @Tsinghua_Uni
Palo Alto, CA
Joined October 2013
- Tweets135
- Following250
- Followers447
- Likes802


Han Zhang retweeted

GR00T 2 is here! 🚀 A huge step toward general-purpose robotics, bringing together long-horizon autonomy, dexterous manipulation, and the ability to adapt across different robots!
Super proud of what we’ve built with DexUMI, pushing the boundaries of complex, long-horizon dexterous manipulation tasks in GR00T 2.
Excited to see what the community builds next!

Introducing GR00T 2: our most advanced, open System One model for robotics. It runs entirely on your robot’s onboard compute, fully untethered, and you own every weight of it. GR00T 2 features:
1. Long-horizon tasks: dexterous manipulation and whole-body control chained over 20+ steps and 5+ minutes, such as performing chemistry lab experiments or assembling model airplanes end to end.
2. X-Adapt: adapting from easy data sources (human wearables and simulation) and deploying zero-shot to diverse real robots.
3. Unified Cognition: native integrations with frontier agents for advanced physical reasoning, robust error recovery, and safety monitoring.
It's an open-source buffet! We are releasing not only the model weights and X-Adapt recipes (coming December), but also our agentic framework, simulation engine, annotation engine, hardware design, and even training data (100K hours, that's ~11 yrs of experience), all available today!
Everything that moves will be autonomous. Anyone can become a roboticist.
Lock in, build with us!
Deep dive in thread:
Han Zhang retweeted

Can more pretraining improve a robot policy’s success rate, yet makes it worse for porttraining? 🤔
In our new work, we find that it can. Continued supervised pretraining of generative robot policies can improve reliability at the expense of coverage, and this tradeoff affects downstream posttraining.
Read on to see why this happens and how we can preserve coverage. 1/n 🧵

Han Zhang retweeted

Can you believe these are open-loop rollouts?
Excited to introduce CARD 🃏 — Contact-Anchored Retargeting for Dexterous Manipulation.
Almost every method today is limited to kinematics alone as the 𝐢𝐧𝐭𝐞𝐫𝐟𝐚𝐜𝐞 between the human and the robot. With CARD, we track real world contact and forces alongside kinematics to perform unprecedented dexterous tasks through tactile reactive replay!
CARD is scalable:
📹 Multiple input sources
🤖 Multiple robot hands
⚡ needs no object models, no simulator, 10 Hz
Han Zhang retweeted

Transformer Transformer will be presented at #CoRL2026 🚀 See y'all in Austin!
Website: transformer-transformer.gith…
Video: youtube.com/watch?v=TTyjvPVF…
Paper: transformer-transformer.gith…
Han Zhang retweeted

When a robot learns a new behavior, what keeps it from forgetting the ones it already knows?
Prior work, especially on VLAs, shows that rehearsing past experiences can enable strong continual learning. But why does rehearsal work so well, and when does it fail?
We find that a small but ✨special subset✨ of rehearsed data largely determines whether old behaviors are retained or forgotten. We call these examples Memory Anchors. ⚓
Withholding just the top 10% of Memory Anchors from rehearsal increases forgetting by up to 4.5x. Increasing their presence, meanwhile, reduces task forgetting and enables a real robot to learn challenging task sequences.
Website: robot-adaptation.github.io/M…
Paper: arxiv.org/abs/2608.26545
Curious? Read on! 🧵👇 (1/9)

Han Zhang retweeted

Long horizon bimanual mobile manipulation requires reasoning in many coordinate frames: base, L/R hands, etc. In which frame would policy work best?
It really depends, so don’t pick. Mixture of Frames Policy: denoise in multiple frame in parallel.
🌐mofpo.github.io (1/9)
Han Zhang retweeted

LLMs learn new tasks in-context. It’s time robots do the same 🤖
Introducing Behavior Prompting: human shows one demo, and the robot adapts immediately. Turns out robot demos are great in-context prompts!
And the magic: no paired human2robot data needed
behavior-prompting.github.io (1/8)
Han Zhang retweeted

Manipulation happens through surfaces. To understand contact-rich dexterous interaction, motion alone is not enough. We also need to know surface properties and contact state.
Excited to share ART-Glove, an articulated tactile glove that captures contact-grounded information while preserving human dexterity. It provides:
- Known Geometry: 16 rigid functional surfaces
- Surface Motion: 22 anatomically aligned joints
- Tactile Contact: 2048 piezoresistive taxels
Huge thanks to my advisor Ding @zhao__ding, and to Yuxiang @yxyang1995, Maria @bauzavillalonga, Marissa, and Peide @peide_huang for the valuable advice and discussions.
Paper: arxiv.org/abs/2606.16370
Han Zhang retweeted

🤖Low-data post-training can teach a VLA policy a new robot skill. But it also makes it too attached to the training demos.
We call this lock-in🔒: the policy can execute the post-training task, yet fails to respond to seemingly obvious prompt changes.
DeLock preserves steerability using only the policy’s own pretrained knowledge. No extra supervision needed!🚀🚀🚀
#Robotics #AI #EmbodiedAI #VLA
Han Zhang retweeted

Can we learn whole-body mobile manipulation directly from human demonstrations?
Introducing Whole-Body Mobile Manipulation Interface (HoMMI)
Egocentric + UMI, 0 teleop -> bimanual & whole-body manipulation, long-horizon navigation, active perception
hommi-robot.github.io


Han Zhang retweeted

Toddy enjoyed his time in Seoul — his first big trip away from home!😆 He rolled around on wheels, showed off his pull-up skills (Cr: @li_yitang), spoke in the spotlight as a 1.5-year-old, and presented at the poster session.


ToddlerBot is accepted to CoRL, and we will bring Toddy (2.0 version) to Seoul for a trip. Come and say hi to Toddy if you're around😁! Our arxiv paper is also updated with more technical details in the appendix: arxiv.org/abs/2502.00893


Han Zhang retweeted

How do we unlock the full dexterity of robot hands with data, even beyond what teleoperation can achieve?
DEXOP captures natural human manipulation with full-hand tactile & proprio sensing, plus direct force feedback to users, without needing a robot👉dex-op.github.io/
Han Zhang retweeted

Collecting dexterous humanoid robot data is difficult to scale. That's why @mengdaxu__ and @DoubleHan07 built DexUMI: a tool for demonstrating how to control a dexterous robot hand, which allows you to quickly collect task data.
Co-hosted by @micoolcho and @chris_j_paxton
Han Zhang retweeted

Human hands are incredibly capable manipulators, but it's hard to get high-quality robot data for learning policies. DexUMI provides a solution: a tool by which you can naturally "puppet" a dexterous hand with your own, in order to learn skills that directly transfer to a robot. Learn more ->

Collecting dexterous humanoid robot data is difficult to scale. That's why @mengdaxu__ and @DoubleHan07 built DexUMI: a tool for demonstrating how to control a dexterous robot hand, which allows you to quickly collect task data.
Co-hosted by @micoolcho and @chris_j_paxton
Han Zhang retweeted
Full episode dropping soon!
Geeking out with @mengdaxu__ @DoubleHan07 on DexUMI: Using Human Hand as the Universal Manipulation Interface for Dexterous Manipulation dex-umi.github.io
Co-hosted by @micoolcho @chris_j_paxton
Han Zhang retweeted

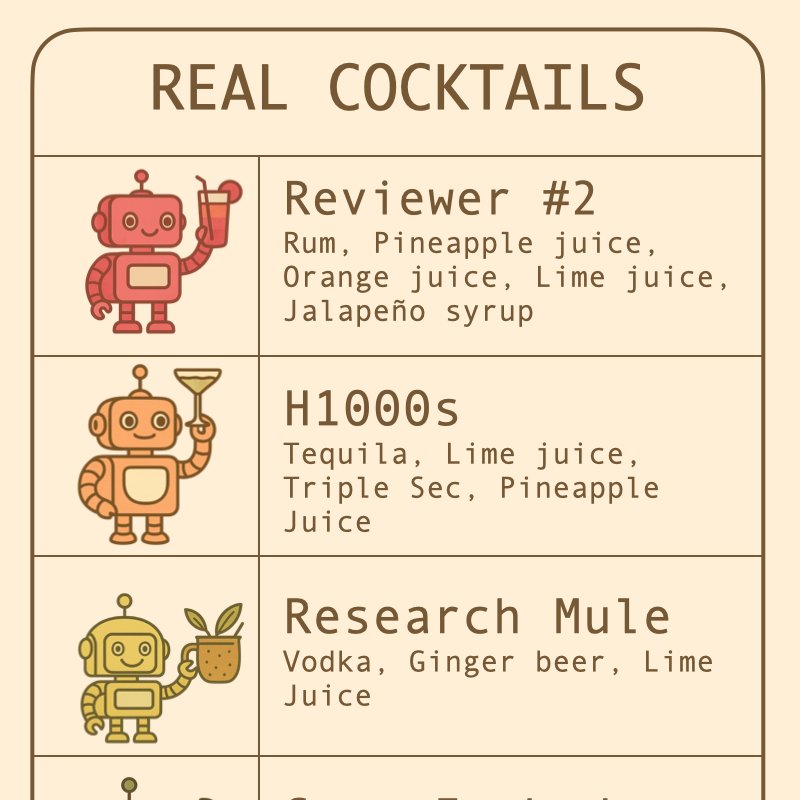
Our lab at Stanford usually do research in AI & robotics, but very occasionally we indulge in being functional alcoholics -- Recently we hosted a lab cocktail night, and created drinks with research-related puns like 'reviewer#2' and 'make 6 figures', sharing the full recipes here in case you are looking for a fun summer drink: