

Douglas A. Fullington, MD is a board certified Internal Medicine Physician who loves inspiring people to be healthy.
United States of America
Joined March 2009
- Tweets629
- Following713
- Followers111
- Likes2.4K



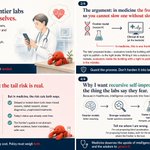

My first security prompt told an AI agent what to look for and almost nothing about how to behave while it looked.
An auditor with wide access is itself a target. Version 2 writes rules for the auditor, and it is free to copy. #HealthcareAI
dfullington.substack.com/p/t…
🤖 Made with AI

1
7
5/6
The rule I would hold a resident to: "Unreadable" is not "on."
Every finding is labeled Verified, Inferred, or Not assessed. If you did not examine it, do not document it as normal.
1
6/6
The full protocol is free to copy, with a template for your own setup. It is not a penetration test, and it stops after its preflight if it is running unattended.
dfullington.substack.com/p/t…
#HealthcareAI #CyberSecurity
There are no secrets. There is no privacy.

I have a major result to share.
I’ve found conclusive forensic evidence that the top 4 Chinese AI labs—DeepSeek, Moonshot, MiniMax and Ant Group—have built their newest models on NVIDIA’s most advanced Blackwell chips, which are barred from export to China.
This sounds insane, but I discovered that almost every AI model carries a hidden signature of the GPU that trained it. When a model is first set up, the starting values of its weights are laid out in a pattern that depends on the exact GPU. Each combination of GPU and seed number produces a unique pattern—a sort of fingerprint of the hardware used to create the model. Traces of that pattern survive training into the published model.
Again, this evidence isn’t based on any insider information or leaking. It’s based on a forensic analysis of the model weights released by the companies themselves.
I searched more than six trillion combinations of chip layout and seed number and matched them to open-weights models. In doing so, I found conclusive evidence that six Chinese AI models—including DeepSeek-V4-Pro, Kimi K3, and MiniMax-M3—were initialized on NVIDIA Blackwell systems. Four of the models match Grace Blackwell, the GB200 and GB300 parts in NVIDIA’s flagship liquid-cooled rack-scale systems.
I then verified these results on real hardware. Running unmodified PyTorch with the seeds I’d recovered, a Blackwell B300 reproduced DeepSeek-V4-Flash’s untouched starting weights bit for bit, and a rented GB200 reproduced Kimi K3’s to a correlation of 0.999995. A Hopper H100 reproduced none of DeepSeek-V4-Flash’s, and changing the seed by one broke the match. (DeepSeek’s seed is 953049583 by the way.) The method also was verified to match 24 known open-weights models to the hardware that developers said they used.
It is exceedingly unlikely that these results are a coincidence. Across six trillion combinations, the best accidental match should reach only about 8 sigma (i.e., eight standard deviations above what random chance would produce). The real matches range from 49 to 1,385 sigma, and even the weakest single test hits 20.
These were data-center-scale training runs. With some analysis of release schedules and model details, I estimate that the largest, Kimi K3 and DeepSeek-V4-Pro, used 2,000 to 3,000 Blackwell GPUs each. Clusters of this size cost on the order of $150 to $200 million each to buy, and across these labs alone would add up to more than half a billion dollars of export-controlled GPUs, not counting experimental compute or otherwise. It’s quite likely that we see multi-billion dollar expenditure on export-controlled GPUs.
I am highly confident in this result, and it has been independently verified by senior researchers at OpenAI and Anthropic. You can read the full report at unemploymentlabs.com/checkpo….
There is much more I’ve identified about these models through other forms of checkpoint forensics like this, and will have more to share soon.

1
4
13
Doug Fullington, MD retweeted

Matic is sponsoring HLTH USA 2026 in Las Vegas, and we have news to share.
Find us at Booth 127-66, Nov 15 to 18, at The Venetian Expo Center. Book time with the team before the week fills up.
Book your time with the Matic team at HLTH (Booth 127-66): meetings-na2.hubspot.com/bob…
Spots go fast, so grab one before the event.

Junior anesthesia residents worked 20 simulated cases with and without a reasoning model. Accuracy rose from 62 to 86. They took 65% of the AI's suggestions. Simulation is not the OR. I want to know which suggestions they should have rejected. pubmed.ncbi.nlm.nih.gov/4300…

1
14


Doug Fullington, MD retweeted
Context collapse costs physicians time, quality, and revenue.
At Thrive 2026, @CatalystHG and @maticinside shared how they co-built one AI workflow on athenaOne APIs. Early result: 83% less after-hours charting.
See how Matic works at maticinside.ai

Wondering if this is the model that was trained on 20+ years of Tesla and SpaceX engineering. Having fun with Grok bots, which have been surprisingly helpful agents.

We have dumped JAX/SGLang and rewritten the entire RL and inference stack from scratch in C/C++, which took some extra time.
Training (aka pre-training) is done. Lot of cleanup was needed on the SFT data to get that mostly right. Now, 4.8 is in RL and the evals are starting to climb. We will do a soft rollout to Bot users later this week and see how it goes.
Grok 4.8 will bear no resemblance to 4.7 (thankfully). It is not yet incredible, but, this time, the foundations are built right, so I expect it to evolve to be something special.
1
2
22
Doug Fullington, MD retweeted

Just did a round table review with the Grok @Bot engineering team.
Fixes are being implemented overnight and you should notice a dramatic improvement by tomorrow. If not, reply to this post and we will address any remaining issues right away.
An overnight summary read "no exertional symptoms." The scribe wrote it. I signed it. The reference tool answered it. Then the patient read the screen: the burning starts on the stairs with groceries.
Every link was accurate. The chain was wrong.
dfullington.substack.com/p/e…
1
2
18
substack.com/@robertreich/no…
This is worth reading. I remember as a freshman in college pulling an all-nighter to write a paper on St. Augustine’s Enciridion on Faith, Hope and Love. The greatest of these is Love. Love is the antidote to hate. My hope is that we all come together to solve the problems of our country and communities with love.
1
16
Doug Fullington, MD retweeted
A lot of promising healthcare ideas never find a path to impact.
Our CEO Calvin Carter joins Panel II at the 4th Annual @SMUCox Healthcare Conference in Dallas on November 17.
Register and see the full agenda for the 4th Annual SMU Cox Healthcare Conference: smu.edu/cox/healthcare-leade…

Doug Fullington, MD retweeted
A lot of vendors say they have healthcare AI. How do you know whose is real?
Bryce Blackwell, our Head of Product, keynotes #AIMSVAR2026 in Orlando on Monday, Nov 9 at 9:15 a.m. Come find us there.

Doug Fullington, MD retweeted
Live from @athenahealth Thrive, booth #809. Practice leaders and physicians keep telling us the same thing: they want software that lightens the load, not adds to it.
Schedule a demo, link in the comments.
meetings-na2.hubspot.com/sal…


