

Predoctoral Fellow - University of Chicago https://xitter.cf/t.co/ZH7JMgvMTI
Joined January 2021
- Tweets28
- Following33
- Followers10
- Likes37


Eric Fithian retweeted

simple message:
(1) Mode collapse isn’t baked in.
(2) Even when it happens, finetuning fixes that.
check out @kskblv’s thread and video!

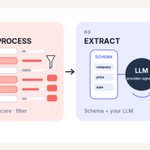
I made a python package that extracts structured data from unstructured text. It handles all of the edge cases and failure modes common in LLM based data extraction such as cost estimates, caching, automatic failure handling, etc. For me it turned 100+ line code files into 5 to 10 lines of simple code. Check it out with pip install delm.
Eric Fithian retweeted

Happy to share that our paper "Mecha-nudges for Machines" has been accepted as a spotlight at NeurIPS 2026!


It’s insane how good the out-of-distribution performance of humans is. Evolution fine-tuned us to hunt, gather, and have sex and now we’re building spaceships and training computers to reason
Just read Dario Amodei’s “Concrete Problems in AI Safety” from 2016. He highlights 5 issues.
To me, the 2 that might kill humanity and might never have a good enough solution are Reward Hacking and Negative Side Effects.
The other three (scalable oversight, distributional shift, and safe exploration) seem solvable without killing humanity.
Eric Fithian retweeted
Whether an LLM mode collapses or not depends on the dataset and post-training method used. It's not as consistent as people typically think. Sometimes, it could actually be more diverse than the target distribution. (See animation.) In our paper, we show this and also we show that fine-tuning actually fixes both under-diversity (AKA mode collapse) and over-diversity.
Previous work has shown that LLMs can mode collapse in different settings: @MengdiWang10 in simulated populations; @chrmanning & @shi_weiyan in post-training; @hhexiy & @vishakh_pk in AI-assisted writing. While it does seem to be a common behaviour in LLMs, it is not guaranteed.
We formalise LLM diversity using probability of sequence collision, which measures how often an LLM gives the exact same response to two samples from the same prompt. You could calculate the literal exact sequence match probability, but in many cases, the probability of any two sequences matching exactly can be too close to zero. Instead it's useful to look at some higher-level output similarity using a similarity kernel. For example, we measured the similarity of code using Abstract Syntax Trees in one of our experiments.
We can calculate this collision probability both for LLMs and the training distribution, and in the paper we prove that the absolute difference between them is bounded by the square root of KL divergence of the model from that training distribution. It means that as you keep training bigger models using more training steps, they get closer to the training distribution, and both mode-collapse and its opposite (over-dispersion) stop occurring at the same magnitude.
To verify these results on data, we fine-tune four LLMs on three human surveys (ANES, WVS, GSS). These models initially gave much less diverse answers than people did. As we trained the models with more and more human examples, all four approached the human level of diversity across all three surveys.
We ran the same procedure on the CodeNet dataset. Unlike the case with social surveys, on code, some models generated more varied program structures than humans; and others generated less. Fine-tuning again brought both closer to the human target.
To understand why LLM output diversity can go either way, we decomposed the expected next-token collision gap into three terms. Variance and squared bias are always positive, and thus increase collisions, but alignment between model bias and the training distribution can push it either way, and when it's negative, it could take over the always-positive terms.
This last term gives us a way to control whether mode-collapse or its opposite happens. We set up two synthetic language experiments, where we knew the target distribution exactly. This lets us calculate the decomposition terms. We show that depending on how the model is initialised with respect to the training distribution, we can get either mode-collapse or its opposite.
Regardless of whether mode-collapse or under-dispersion happens, we now know that cross-entropy training calibrates it in the limit. So, mode-collapse that is often talked about, is either due to RL nerfing the model's preferences, or the lack of domain-specific data.
As average benchmark scores continue to climb, output diversity may stay low. This can lead to homogenization in thought, science, writing, and many other fields that increasingly use LLMs. So, it's imperative that we figure out how to fix this. Our results in particular show that post-post-training methods could make use of the "purifying" properties of fine-tuning to cure models destabilised by RL.
📄 More in the paper: arxiv.org/abs/2609.16454
Joint work with @EricFithian @XYHan_
Eric Fithian retweeted
Just learned that the Paper Assistant Tool (PAT) that ICLR uses for auto-generating llm-reviews is powered by Gemini 2.5 Deep Think. To which I respond:
What makes Gemini 2.5 DT believe it's qualified to judge the paper I wrote with Fable 5.1 Max and GPT 6 Astra Ultra?


If you're still using one off scripts to do structured data extraction with an LLM at any meaningful scale, you should really check out DELM (or ask your agent to). It'll save you and your agent money and headaches.

Docs: center-for-applied-ai.github…
Here's the skill.md I use: github.com/Center-for-Applie…
Eric Fithian retweeted
We benchmarked GPT-6 Astra on the @SurgicalDSC @CAAI_Booth Surgical AI Leaderboard
- astra is the new generalist leader, but falls behind tiny specialist models (1000x smaller)
Full Leaderboard: skblv.github.io/neurosurgery…
Paper: arxiv.org/abs/2603.27341
HT @kskblv @EricFithian


Eric Fithian retweeted
We benchmarked Claude Fable 5.1 and Gemini 3.8 Flash on surgical intelligence:
- The performance of the two new releases is spiky (e.g. good on tools, bad on VQA)
- Frontier LLMs still underperform tiny specialized models
Check out the full LLM leaderboard linked below

/humanizer with 40k gh stars is ranked #5 in a writing arena
#1 has only 55 stars
aiwritingarena.com to see what it is


had Grok @Bot study 300+ GitHub repos of skills
here are the 12 that influenced my setup:
/humanizer by @blader: make your writing and rewrites sound human
github.com/blader/humanizer
/unslop by @poteto: removes common AI slop patterns from your writing
github.com/cursor/plugins/tr…
/no-ai-slop by @petergyang: make your writing more precise and clearly human
github.com/petergyang/no-ai-…
/agent-skills by @addyosmani: agents that interview you before they invent any specs
github.com/addyosmani/agent-…
/skills by @mattpocockuk: a suite of S tier engineering and productivity skills
github.com/mattpocock/skills
/skills by @MengTo: prompt S tier design and UIs like a design system
github.com/MengTo/Skills
/skills by @emilkowalski: design and motion skills that survive real audits
github.com/emilkowalski/skil…
/cartographer by @KingBootoshi: a repo map before your agent wanders
github.com/kingbootoshi/cart…
/superpowers by Jesse Vincent: stop guessing when you debug, agentic skills framework + complete software dev methodology forcing agents to follow professional workflows
github.com/obra/superpowers
/gstack by @garrytan: memory improvements + spec, review, and QA playbooks so agents cannot silently edit
github.com/garrytan/gstack
/impeccable by @pbakaus: detect, fix, and recheck with 61 rules
github.com/pbakaus/impeccabl…
/last30days by @mvanhorn: deep research what people said about a topic over the last month
github.com/mvanhorn/last30da…
save these and remix them with your Bot!

