
Ray Aun Fan retweeted

Math time: if a coding agent goes from doing 98% of your work to doing 99%, how much more can you get done?
It can be hard to explain a new product experience in words. But the difference we've seen both with beta testers and internally @ Cog is enormous. Give it a try and let us know what you think :)


Ray Aun Fan retweeted

Join a small, curated gathering of engineering leaders in Singapore with visiting members of Cognition’s Japan team.
@cognition’s forward-deployed engineers will share how Devin works, how the team uses @DevinAI to build Devin itself, and perspectives on helping engineering teams adopt it effectively.
We’re keeping the evening informal, with room for questions, conversation, and meeting others thinking through the future of AI software engineering.
Attendance is by personal invitation!
luma.com/uglnlkg9


Ray Aun Fan retweeted
Introducing SWE-2 Flash, our new fast & efficient coding model.
On leading evals, it outperforms all American open-weight models, even ones 3x larger.
To balance transparency and cyber risks, we are building a program to securely share the weights with partners & researchers.


Ray Aun Fan retweeted
We’ve open sourced an agent plugin that helps secure systems against recent cybersecurity threats.
You can install them with any agent or use them in Devin today:
devin.ai/blog/vulnerability-…

Ray Aun Fan retweeted

I got sick of reviewing code. So I made /walden-review.
Its a skill auto-generated against my last 6 months of Github comments and agent sessions. It learned what I look for and even my comment style: “blunt, occasionally profane”.
I always run it before ever reading a PR myself, and it catches design/codepattern/architectural problems most bug-catcher miss. FYI: This method burns a lot of tokens
First, I asked Devin to collect my last 6 months of GitHub PRs and Devin sessions, collect every comment I left or message I sent, filter out unimportant stuff (“lgtm”), and build a hillclimbing set of PRs with a training and eval split.
Then I had it recursively improve a skill to catch as many of the issues I’d flagged on this hillclimbing set as possible, while leaving at most 2x as many comments as I did. In the process, I found that it performed much better once I told it to add “subagent sweeps” to the skill: each sweep spawns a Fable/Astra subagent with specific responsibilities to look for certain things I would flag.
There’s some nuance in how to grade the results. I personally found that some decisions require product context and aren’t reasonable to expect the AI to catch. So I split out the “code concerns” from “product concerns” and mostly tried to measure it against the code concerns, with the expectation that I would make the product calls. For product calls, I use a separate skill that generates a Markdown explainer of the important decisions in a PR. I also use an AI grader to make the judgement call about which bugs it flags are “close enough” to the bug reports I would’ve made.
I ran the hillclimbing overnight. Because my approach ran multiple levels of graders, idea generators, and review swarms, this takes a lot of compute. I came back to find that the hillclimbing used 91 subagents, 559 grandsubagents, and 1,883 great-grandsubagents.
On the held-out eval set, it catches about 70% of the code issues I’d flagged. Now, whenever I get a massive PR, I just throw this skill at it, and let it auto-fix a bunch of the issues I would’ve caught. The skill also separates issues into “auto-fix” and “requires Walden’s approval,” so I sometimes come back to a list of decisions I need to make.
I’m pleasantly surprised that it catches a lot of the things I get most annoyed by. On its own, for example, it learned to double check assumptions about external systems, it learned to aggressively consolidate with existing code, and it learned to remove dead code.
I’ve also generated versions of this for other people on the team who write a ton of code. Honestly, I think there’s a lot more someone could do with this pattern. I haven’t tried training it on ALL of our human review comments yet, but that might be interesting. I also suspect there’s similar things people can do along these lines to catch security vulnerabilities before they ship.
I’ve attached the final skill in the thread as well as a meta-skill I use to generate the same thing for other people on the team.

Ray Aun Fan retweeted
we are hosting our next agentic builders collective meetup on Oct 30th at Institute of Lifelong Learning! Come join other builders for a night of sharing!
At the event, agenda to be confirmed! Spots limited, sign up here if you can make it! luma.com/lj7r7hh5
@sgcodecampus @yjsoon @ChristianPecaut
@QwenDevs @DevinAI

Ray Aun Fan retweeted
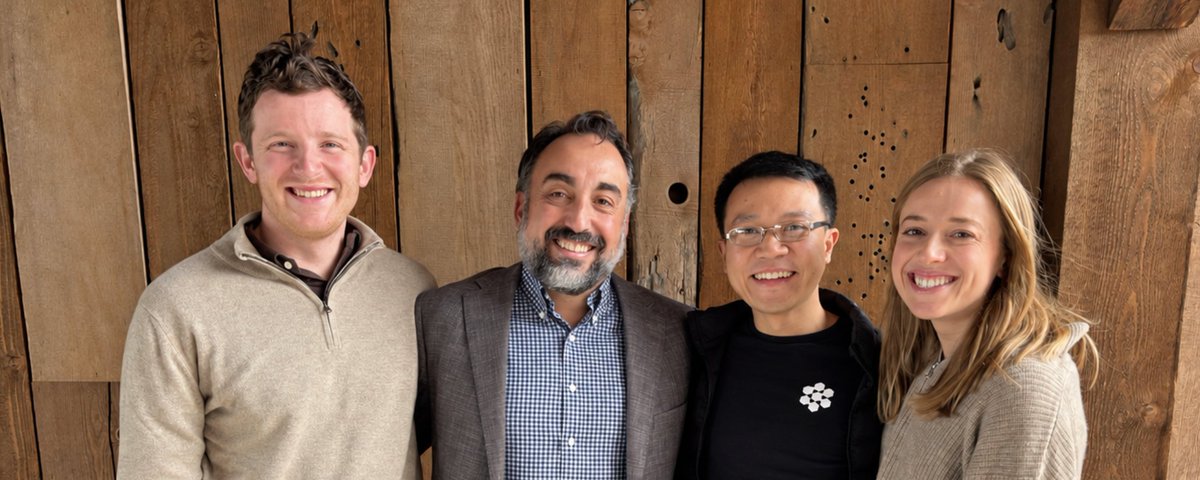
Alex had the hardest security jobs of every era: Yahoo, Facebook (nation-states attacking both), SentinelOne, Zoom during COVID, Stanford Internet Observatory.
No one better to loead Cognition's focus on security in this eraa. Couldn't be more excited. Welcome Alex!

Ray Aun Fan retweeted
btw, @cognition is hiring:
- GTM ops
- people ops
- talent ops
- brand marketer
- dev community manager
- product marketer
- engineers across the board
- biz ops
- event producer
apply here: jobs.a16z.com/jobs/cognition…
Ray Aun Fan retweeted
Took a little less than 3 years but can finally say we did zero to one.
All credit goes to the incredible people I get to work with. Never would I have imagined getting to work with such a world-class team on such a history-defining technology.

Ray Aun Fan retweeted
to the @cognition power users: you are seen
you can now SSH into your devins(!!) 🙌
this unlocks a whole world of features like NFS, scp, reverse tunnels, localhost forwarding, rsync to your cloud agent
we're shipping some cool new features on top of this soon!
Ray Aun Fan retweeted
Introducing Devin Cloud in Terminal and devin ssh: two new ways to use Devin's computer.
Create, steer, and resume Devin Cloud sessions right in your CLI with /cloud.
And for the first time, SSH into Devin's dedicated VM, then /handoff the work back to your own device.
Ray Aun Fan retweeted

Lots of companies are rolling out model routing but many underestimate how good Devin Fusion is. It turns out handing off to a dumber agent doesn’t work well, because an agent doesn’t know if its work is subpar or good
When using a combination of Astra+Fable and SWE-2, having frontier models monitor cheaper models for certain tasks need to run in parallel (main+sidekick) for this very reason
We pick the smarter model which can then keep the cheaper models quality high, this also further saves costs because you can increase cache hits
For this very reason Devin Fusion has become a daily driver and I suspect it will for others (who want to optimize on cost without tradeoffs on performance)


Ray Aun Fan retweeted
A big improvement for CLI fans who want to use more Astra or Fable.
We've tuned Fusion so that the delegation is unnoticeable day-to-day. Worth giving it a try.
Hats off to the team that made this possible @joon_h_lee @spdling @mapeiyuan @morgantepell @maaslalani
