

Sovereign Superintelligence
Bangalore
Joined April 2026
- Tweets63
- Following3
- Followers344
- Likes74

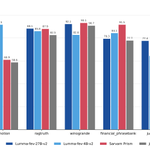
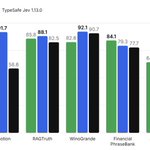


RT @FrontiersMind: 🚀 Introducing the Lumma-fev-v2 family of decision models!
From 27B to 0.1B parameters, we’re releasing models across th…
FrontiersMind retweeted
Open-sourcing DecisionFormer 🚀
Think "Transformers library", but for decision models.
🤗 @huggingface made it easy to use any language model. We wanted the same for decision models: models that don't write an answer but make a call with a calibrated probability for every option, in a single forward pass.
🔧 Full fine-tune, LoRA, QLoRA
🧠 Causal, bidirectional, prefix-bidirectional attention
📦 Any backbone: Qwen, Gemma, Llama, ModernBERT,
One forward pass, calibrated probabilities, no generation.
github.com/FrontiersMindAI/d…
Tell us what you build.

FrontiersMind retweeted

Yesterday evening, I had the opportunity to present our latest research, Grouped Value Attention (GVA) at @lossfunk .
It was great connecting with fellow researchers and developers, exchanging ideas, and discussing how we can make LLMs more efficient. Thank you to everyone who joined, asked insightful questions, and showed interest in our work.
Special thanks to @lossfunk and @paraschopra for hosting us and creating a space for meaningful technical discussions and knowledge sharing.
Looking forward to more such conversations with the AI research community!


FrontiersMind retweeted
We're open-sourcing Lumma-fev-27B, our most capable Multimodal decision model, outperforming Jev across multiple benchmarks
It is trained on English and 3 Indic languages including Hindi, Kannada and Tamil
📜 Blog: huggingface.co/blog/Frontier…
🤗 Model: huggingface.co/FrontiersMind…

FrontiersMind retweeted
🔥 Adding a new member to our Lumma-fev Decision Family!
Today, we're open-sourcing Lumma-fev-27B, our most capable Multimodal decision model, outperforming Jev across multiple benchmarks. It is trained on English and 3 Indic languages including Hindi, Kannada and Tamil.
📜 Blog: huggingface.co/blog/Frontier…
🤗 Model: huggingface.co/FrontiersMind…
#jev #decisionmodels #llm #ai #ml #openSource
FrontiersMind retweeted
🔥 Introducing Grouped Value Attention (GVA)
At FrontiersMind, We’re excited to introduce Grouped Value Attention (GVA), a new approach to efficient attention for LLM training and inference
The key idea: store grouped values and reconstruct content keys on demand, eliminating the need to persist a separate content-key stream
🔷 ~45–47% lower persistent cache footprint vs. GQA
🔷 Simpler KV-cache design than DeepSeek MLA
🔷 Designed for faster and more efficient inference
🔷 Maintains near-GQA quality while significantly reducing the persistent cache representation
🔥 We’ve also developed custom kernels and are now evaluating end-to-end inference performance against GQA and DeepSeek MLA
More to come soon!
Paper: github.com/FrontiersMindAI/G…

FrontiersMind retweeted

This paper makes long-context attention cheaper and faster by letting each token use only the query heads it needs.
Reached about 1.7 to 1.8 times faster prefill when context length became large.
Standard attention makes every token run through every attention head, even when some heads are not useful for that token.
The paper’s idea, called Grouped Query Experts, keeps the normal key and value cache from grouped-query attention but routes each token to only a few query-head experts.
Grouped Query Experts sits on top of grouped-query attention, the trick many long-context models already use to reduce key-value cache cost.
This is like giving the model many possible attention patterns, while making each token pay for only the small set that seems useful.
The authors trained 250M-parameter models on 30B tokens and compared the method with a normal grouped-query attention baseline.
The best version matched the baseline’s average accuracy, 56.04 versus 55.86, while using 9 of 16 query-attention computations.
shows that attention can be made sparse inside grouped-query attention without hurting quality, but only when the router gets a strong learning signal and one shared head stays always on.
----
Link – arxiv. org/abs/2606.20945
Title: "Grouped Query Experts: Mixture-of-Experts on GQA Self-Attention"

FrontiersMind retweeted
Excited to share our latest work from @FrontiersMind 🚀
We published Grouped Query Experts (GQE)- Mixture-of-Experts applied directly to GQA self-attention heads.
MoE in MLP blocks saves compute by activating only k experts per token. We applied a similar idea to self-attention - built on top of GQA, each token now activates only k heads out of all heads, making attention sparse.
→ 1.7–1.8× faster prefill at long contexts
→ No accuracy loss
→ 25–75% fewer active heads per token depending on sparsity chosen
Paper: lnkd.in/d56iJZ9k
HF: lnkd.in/d-ZtggcH
#LLM #MoE #Transformer #SelfAttention

FrontiersMind retweeted

Reduce KV cache size in LLMs by 50% by using a shared KV, with negligible loss in output quality.
Cool trick by @FrontiersMind ! 👏

FrontiersMind retweeted
The internet decentralized information. We're building @FrontiersMind to decentralize access to frontier AI.
This week was a reminder: just days after launch, access to Fable 5 was suspended for users outside the US.
#DecentralizedAI #SovereignAI #FrontiersAI
