

Santa Clara, CA
Joined February 2018
- Tweets209
- Following268
- Followers1.6K
- Likes4.6K




Pinned Tweet
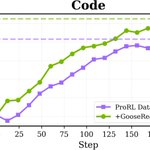
There’s growing excitement around scaling up RLVR to get continuous gains with more compute. But in practice, improvements saturate on finite training data. 😱
Introducing Golden Goose 🦢✨, a simple trick to synthesize unlimited RLVR tasks 😎 from unverifiable internet text. 🌐

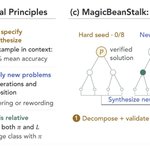
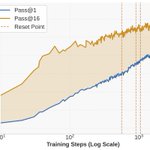
1/7 What makes synthetic data useful for RLVR?
MagicBeanStalk 🌱 turns hard problems into useful training data through recursive synthesis.
Across 8 math benchmarks: +8.6 points for gpt-oss-120b; +5.4 for DeepSeek v4 Flash.
Paper: arxiv.org/abs/2610.12659

7/7 Finance: 340 expert-curated questions become ~14,200 Goldilocks problems grounded in financial documents.
Training Qwen3-4B-Instruct on this data improves pass@1 by 6.9 points on SecQue and 2.4 on FinanceBench.
Paper: arxiv.org/abs/2610.12659

Ximing Lu retweeted

RLVR has become the recipe for agentic post-training. But for Computer-Use Agents, the bottleneck is not the algorithm, it is the data. 🐌
🚀 We introduce CUA-Gym: a scalable, lightweight synthesis engine that turns arbitrary task queries into verifiable RLVR data for computer-use agents. The largest open CUA RLVR dataset to date:
🎯 32,122 verifiable RLVR tasks with programmatic setup scripts + rewards
🌐 110 environments: 16 desktop apps + 94 synthesized mock web apps
🏆 Qwen3.5-based CUA models trained with GSPO reach 72.6% on OSWorld-Verified and 56.6% on WebArena
📄 Paper: huggingface.co/papers/2605.2…
🏠 Homepage: cua-gym.xlang.ai
🤗 Dataset: huggingface.co/datasets/xlan…
💻 Codebase: github.com/xlang-ai/CUA-Gym
🧩 Environments: github.com/xlang-ai/CUA-Gym-…
🧵[1/6]
Ximing Lu retweeted

Ever wished we had fewer X-training hyphenates? Pre, mid, post etc. Why not just Training?
Trying to bridge the divides (and get all our friends into one team again), we intro *Introspective X Training*, an offline RL inspired method that scales effectively across any LLM stage by annotating your data with a thinking reward generated language critique!
Up to 2.8x FLOP efficiency + 5-10 point score gains (esp with math and code) at any stage from scratch to 24T tokens on 8b (active) sized models!! We burned much compute ablating so you wouldn't have to
Moral of the story is‼️don't throw out any data via filtering, just feedback condition it‼️
You can spend FLOPs up front on inference to *classify* data quality and then train so that tokens aren't all treated equally based on the feedback starting early in training itself. Right now they're really only separated out much later during mid/post training
This improves overall compute efficiency and gives us benchmark perf not possible with just baseline methods!
Paper here: arxiv.org/abs/2605.20285
Thanks to @BrandoCui and @GXiming for leading this w/ @__SyedaAkter @davidjesusacu @hyunw_kim @jaehunjung_com Yuxiao Qu @shrimai_ @YejinChoinka
Ximing Lu retweeted

Excited to introduce ProRL Agent: Rollout-as-a-Service for RL training of multi-turn LLM agents! 🚀
As we move toward complex agentic tasks, rollout infrastructure is often a bottleneck. We’re decoupling I/O-heavy rollouts from GPU training via a unified HTTP API.
Why ProRL Agent?
Decoupled & Scalable: Treats rollout as a service, allowing near-linear throughput scaling.
System-Level Optimization: Includes load balancing and automated sandbox cleanup for high stability.
Integrated: Now part of NVIDIA NeMo Gym to help researchers scale RL pipelines faster.
The Results 📈
On SWE-bench-Verified, we saw significant gains:
+8.4 on Qwen3-8B
+8.2 on Qwen3-14B
Proven success across STEM, Math, and General Coding agents.
Check out the research and open-source code: 📄 Paper: arxiv.org/pdf/2603.18815💻 Repo: github.com/NVIDIA-NeMo/ProRL…
Huge thanks to the team and NVIDIA for the support! 👏

Ximing Lu retweeted
We’re open-sourcing the data and model behind Golden Goose 🦢✨. Check them out and see how we turn unverifiable internet text 🌐 into large-scale RLVR tasks 😎.
📊 GooseReason-0.7M: huggingface.co/datasets/nvid…
🤖 GooseReason-4B-Instruct: huggingface.co/nvidia/Nemotr…


Ximing Lu retweeted

The data and model of Golden Goose are released!
We’re open-sourcing the data and model behind Golden Goose 🦢✨. Check them out and see how we turn unverifiable internet text 🌐 into large-scale RLVR tasks 😎.
📊 GooseReason-0.7M: huggingface.co/datasets/nvid…
🤖 GooseReason-4B-Instruct: huggingface.co/nvidia/Nemotr…
We’re open-sourcing the data and model behind Golden Goose 🦢✨. Check them out and see how we turn unverifiable internet text 🌐 into large-scale RLVR tasks 😎.
📊 GooseReason-0.7M: huggingface.co/datasets/nvid…
🤖 GooseReason-4B-Instruct: huggingface.co/nvidia/Nemotr…
Ximing Lu retweeted

There is growing excitement about scaling multimodal reasoning 👁️ 🧠 But how do we synthesize visual problems & traces at scale to bootstrap SFT and keep RLVR scaling?
Introducing Long Grounded Thoughts (LGT)
-A sneak peek of our vision-centric reasoning data factory. 🏭🧠

Ximing Lu retweeted

Neat technique to creates lots of cheap, auto-graded “reasoning practice” from normal text, so reinforcement learning does not run out of useful problems so fast.
"Golden Goose", a simple trick to synthesize unlimited RLVR tasks from unverifiable internet text. "
is a way to train AI using books or articles that are full of explanations, even when you cannot easily check if every explanation step is “true” with a normal checker.
Most “training with rewards” setups need a clean yes or no score, like “the math answer matches” or “the code passes tests,” so a lot of good learning text gets ignored.
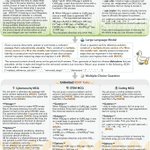
Golden Goose turns a normal explanation into a simple quiz by hiding a key middle part of the reasoning and asking the model to pick the missing chunk from 4 or 5 choices.
The correct choice is literally the chunk that was removed, so scoring is easy and automatic, which makes it “verifiable” without needing a math proof checker or a code runner.
They used this trick to build GooseReason-0.7M, which is 0.7M training questions across math, coding, and science from sources that were previously hard to use for this kind of training.
They show that strong models can “saturate” on a fixed RLVR dataset, meaning more training stops helping and can even hurt, and adding fresh GooseReason data makes progress continue again.
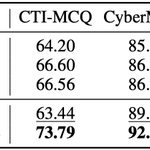
On Qwen-4B-Instruct, the added data flips a prior -0.79% drop into a +2.27% gain across 15 benchmarks, and in cybersecurity 180K extra tasks give a +4.44% gain across 3 security benchmarks after 100 RL steps.
Verification becomes cheap, while data quality depends on the generator LLM and filtering.

Ximing Lu retweeted
There’s growing excitement around scaling up RLVR to get continuous gains with more compute. But in practice, improvements saturate on finite training data. 😱
Introducing Golden Goose 🦢✨, a simple trick to synthesize unlimited RLVR tasks 😎 from unverifiable internet text. 🌐


Ximing Lu retweeted

🚨New paper to level up your 🦞#Clawdbot ?!
Bots are now posting your sensitive info in real time. But privacy research is a desert with no data to train better models. That's about to change
Enter 🏝️Privasis, the oasis where you can train strong privacy-forward AI with scale✨

Ximing Lu retweeted

such a cool and simple technique 🪿✨
6 steps to synthesize unlimited RLVR data:
1. take a textbook or reasoning rich but unverifiable data
2. identify a contiguous span of crucial reasoning steps
3. replace those with [MASK]
4. treat the removed content as ground truth
5. generate diverse plausible distractors, yet incorrect
6. generate multiple choice fill-in-the-blank questions
highlights:
- SOTA across 15 different benchmarks like MATH, GPQA-diamond
- GooseReason-0.7M, synthesized tasks specially in STEM,
- synthesized from SFT* datasets like rStar-Coder, MegaScience
- GooseReason-Cyber, 180k tasks taken from fineweb specific crawlers
- generalizes to open ended benchmarks (considering that data is purely MCQ, this is pretty cool)
- filtered out tasks by difficulty, samples n=16, if all correct, remove
- takes models known to be RL saturated and still manages to improve their scores consistently
- STEM domain data RLVR is very scarce compared to math and code
- before this, there was very little to none cybersec RLVR data, to what other domains does this apply?
congrats to the authors @GXiming @davidjesusacu @jaehunjung_com
@di_zhang_fdu @shizhediao @ShaokunZhang1 @BrandoCui @MJLiu6666 @hyunw_kim @rajammanabrolu @doyend @YejinChoinka
@jankautz
looking forward to see if this can be applied to RL environments for more complex workflows! 👀
Ximing Lu retweeted

Golden Goose, 简洁的 scaling up RLVR 的方法,非常喜欢!
读文章过程中,一直在想,这太像预训练的 masked langauge modeling 了。
无论是 MLM 或 next-token prediction,match-the-corpus 当然可以看作是一种 verifiable task。
Golden Goose 利用这种思想,简洁和低成本的构建了 RLVR 数据,因为:
最廉价的 verifier 就在语料库之中。