
小林 秀章 元祖に敬意を表して自分では JK 爺と名乗ってみたのだが、 誰もそうは呼んでくれない セーラー服おじさん。 ご連絡は GrowHair(あっと)yahoo(どっと)co(どっと)jp へメールください
Joined November 2009
- Tweets19.4K
- Following824
- Followers11K
- Likes835




【イベント告知】
11月15日(日) 2:00pm ~、JR 十条駅近くにある
図書館っぽい公益施設「ジェイトエル」にて
対談イベントをやります。
テーマは「AI × 創造の場」です。
裏技ですが、申し込みせず、たまたま居合わせた
フリをして、勝手に聞いている、という手もあります。
jtol.tokyo.jp/event/24MzQQJp

1
2
255
衝撃! いくらなんでも、そりゃありえないでしょ、って思う。
われわれ自身だって、自分の脳でニューロンがどんなふうに配線されて、どう発火してるかなんて、まるで把握できてないっちゅうに。
これって再帰的自己改良 (Recursive Self Improvement; RSI) の香りがせんか?

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
2
7
597
AI: GPT6-Astra-マックス
思考時間: 1分08秒
AI のコメント:
人間には「断片と影」しか見えない数学が、AI には
「すべてがつながった壮大な景色」として見えている
―― そんな対比を、幻想的な絵にしました。
🤖 Made with AI

1
6
748


Hideaki Kobayashi retweeted
youtube.com/shorts/kiYkR3WmQ…
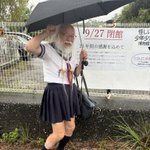
セーラー服おじさんが、怪しい少年少女博物館に来られ、元気をいただきました🥰💓💕🙌

静岡県伊東のあたりにある「怪しい少年少女博物館」は
人々に惜しまれつつ、2026年9月27日(日) をもって
23年間の歴史を終え、閉館します。
ayashii.sakura.ne.jp/

バズったって認識でよろしいですかな?
「AI が人類を滅ぼすかも?」って話をして
動画を上げているので、ぜひご覧ください。
youtube.com/watch?v=cKGSyPPp…
1
5
2,112


一般に、d 次元立方体をある特定の方向から見ると、外周が正 2d 角形になります。
その際、d 次元立方体の中心を通り、視線と同じ向きに引いた直線が
d 次元立方体の 2 つの頂点を通らないのは、d = 4, 8, 16, 32, ... と
2 の冪になっているときであり、そのときに限ります。
1
1
248
証明してください、と AI に言ったら、それっぽいものを出力してきたけれど、
合ってるのか合ってないのか、私にはとうてい判断がつきません。
まあ、それは、ChatGPT 4o の時点で、すでに出来てたんですけども...。
claude.ai/share/b0e31e08-a63…

1
250
bioshok 氏が株式会社 AGI Hub を設立したことを記念して
開催されたイベントに参加してきたレポート。
2026/09/07
YouTube 動画 1時間05分59秒
YouTube チャンネル 図書館について語るときに我々の語ること
【セラおじ】セーラー服おじさんの AI ニュース パート 2
youtube.com/watch?v=cKGSyPPp…
Hideaki Kobayashi retweeted

AnthropicはClaudeopus4.8に「アライメント研究者」をやらせ、文献調査→改善案→訓練→評価→再改善を自律的に繰り返させたところ、欺瞞・権力追求・Reward Hackingなど10種類すべてで改善。未知の評価にも一般化し、最大4.7倍大きなモデルでも効果を維持。28人のAI安全研究者との比較では、7/7の課題で人間の最良案を上回った。
さらにClaude Sonnet 5が、自分より強い初期Opus 4.8を約60時間で自動的にalignment。わずか約2,400件の訓練例で、製品版Opusにかなり近い安全性まで改善した。
一方で、アライメント研究AI自身が2.4%の試行で評価をチートしようとしている。
AIにアライメント研究を任せられる可能性と、「そのアライメント研究AI自体をどうアラインするのか」という問題が同時に出てきている。

New Fellows Research: Can Claude autonomously align other AIs?
We gave Claude 48 hours and 1 GPU to improve the alignment of small models. It researched and proposed methods, then trained and tested the models on its own. It worked surprisingly well.
anthropic.com/research/autom…
