

AI models on real semicha exam questions from Israel's Chief Rabbinate, in Hebrew. Provisional results; reviewers welcome: [email protected]
Joined October 2026
- Tweets97
- Following31
- Followers1.1K
- Likes61


Pinned Tweet
Introducing HalachaBench: we gave AI programs from the makers of ChatGPT, Claude, Gemini and others real semicha exam questions from Israel's Chief Rabbinate, in Hebrew, with no books and no internet.
The best scored 80 out of 100. Many scored under 11. 🧵

Update: 5 models added.
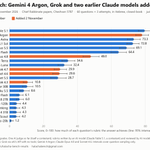
Gemini 4 Argon: 78.2, 2nd of 22, statistically tied with Claude Fable 5.1.
Grok 4.7: 29.9, 10th. Grok 4.3: 10.8.
Claude Opus 4.8: 48.0. Claude Sonnet 4.6: 29.6.
The checks behind the Grok result: teapawt.net/HalachaBench/status/21…

New on HalachaBench: Gemini 4 Argon and Grok.
Gemini 4 Argon: 78.2 out of 100, 2nd of 22, statistically tied with Claude Fable 5.1 (79.7).
Grok 4.7: 29.9, 10th. Grok 4.3: 10.8.
(Poll answer: under 65.)
@GoogleDeepMind @xai

New on HalachaBench: Gemini 4 Argon and Grok.
Gemini 4 Argon: 78.2 out of 100, 2nd of 22, statistically tied with Claude Fable 5.1 (79.7).
Grok 4.7: 29.9, 10th. Grok 4.3: 10.8.
(Poll answer: under 65.)
@GoogleDeepMind @xai
Grok 4.7 thinks a lot but writes short answers (~210 words vs ~660 for Argon), and the grading sheets give points for each source and step.
Details and all checks:
github.com/halachabench/hala…

Also added: two earlier Claude models. Claude Opus 4.8: 48.0 (7th). Claude Sonnet 4.6: 29.6 (11th), level with Claude Sonnet 5.5 (28.7). @AnthropicAI
Quick guess: which semicha paper did AI find hardest?
Answer tomorrow, with the chart.
12%Chuppah v'Kiddushin
39%Niddah
27%Mikvaot
22%Tefillah u'Brachot
74 votes • 4 hoursGrok is next on HalachaBench. The top score so far is 80 out of 100 (Claude Fable 5.1).
Where will Grok land?
7%New #1 (above 80)
40%65 to 80
29%Under 65
24%Just show me
161 votes • Final results HalachaBench retweeted

AI takes rabbinical ordination exams… 👀
Thank you to @SefariaProject: before the grading sheets were sealed, an AI checked their cited sources against Sefaria's library, about 2,000 lookups. Sources Sefaria doesn't carry are marked unverified.
Ask an AI the same semicha question three times and you can get three different answers.
Keep only each model's weakest try on every question and scores drop 7 to 11 points. The order doesn't change.
You'd want the same answer every time you ask.

ALT Chart: score out of 100 for each AI, average of its three tries vs. its worst try on each question. Claude Fable 5.1 79.7 vs 70.4; GPT-6 Astra 73.3 vs 66.2; GPT-6.1 Sol 72.8 vs 63.9; Claude Opus 5.5 69.1 vs 60.0; Gemini 3.8 Flash 64.4 vs 54.3; GPT-6.1 Terra 34.6 vs 25.6; GPT-6 Luna 32.4 vs 21.8; Claude Sonnet 5.5 28.7 vs 18.3. Provisional: one AI judge (GPT-6 Astra), AI-written grading sheets not yet reviewed by rabbis.
הכירו את HalachaBench: נתנו למודלים של בינה מלאכותית (של יוצרי ChatGPT, Claude, Gemini ועוד) שאלות אמיתיות ממבחני ההסמכה של הרבנות הראשית. הם ענו בעברית, בלי ספרים ובלי אינטרנט.
המודל הטוב ביותר קיבל 80 מתוך 100. רבים קיבלו פחות מ-11. 🧵

חשוב להדגיש: זהו תרגיל אינטלקטואלי בלבד. איש אינו חושב שבינה מלאכותית יכולה לפסוק הלכה.
התוצאות ראשוניות וזמניות: מודל אחד כתב את המחוונים ומודל אחר בדק את התשובות, ושניהם גם נבחנו בעצמם. אף רב עדיין לא עבר על המחוונים או על הציונים.
כל מי שרוצה לעבור על המחוונים או לבדוק תשובות: נשמח מאוד לעזרתכם. רוצים לעזור בהרחבת המיזם? כתבו לנו: [email protected]
התוצאות המלאות ופירוט השיטה (באנגלית, עם סיכום בעברית): github.com/halachabench/hala…