

Data and environments for Knowledge Work https://xitter.cf/t.co/tAFT2ceYwg In SF! Shoot us a DM.
San Francisco
Joined June 2025
- Tweets38
- Following4
- Followers308
- Likes14




Halluminate retweeted
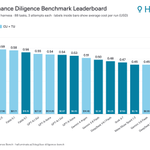
We ran Westworld Finance Diligence Bench on the latest frontier models. Gemini 4 (Antigravity) leads at 0.61, with Claude Opus 5.5 (Claude Code) at 0.59.
Quick reminder: our bench consists 88 tasks built on real acquisition deal data, run on a simulated analyst desktop.

We ran Westworld Finance Diligence Bench on the latest frontier models. Gemini 4 (Antigravity) leads at 0.61, with Claude Opus 5.5 (Claude Code) at 0.59.
Quick reminder: our bench consists 88 tasks built on real acquisition deal data, run on a simulated analyst desktop.
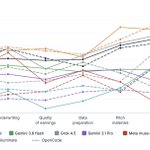
We also looked at what changed from Gemini 3.8 Flash to Gemini 4.
Gemini 4 follows the prompt much better: it misses far fewer required deliverables, formats and content.
It also makes fewer accounting mistakes and calculation errors.

Where it got worse: it more often restructures a template it was asked only to fill in (57 vs 34), and it makes slightly more judgment errors (27 vs 22) and more often misses a source it needed (12 vs 10).
Read our blogpost here: halluminate.ai/blog/due-dili…
Halluminate retweeted
Halluminate is building reinforcement learning environments and benchmarks to help AI models do knowledge work beyond coding, starting with finance.
With a team of fewer than 10 people, the company works with four of the top five closed-source US AI labs and recently raised a $30M Series A.
In this fireside, co-founders @Jerr_Wu and @wgm752 sit down with YC's @xuster to share how testing browser agents led them to building the environments models now use to practice tasks like financial modeling. They explain why better verification, not just more training tasks, is critical to making models smarter, and how that work could eventually lead to simulated companies where teams of AI agents learn to work together.
00:00 — Halluminate’s Pivot From Evals to Training Environments
03:48 — Teaching AI to Do Financial Work
07:13 — Why Verification Matters More Than Volume
10:13 — From Finance to Simulated Companies
13:30 — AI Safety and Building the Team
We've raised a $30M to build the data research lab for knowledge work.
We're hiring across engineering, research, ops, and more.
Join us: jobs.ashbyhq.com/halluminate


Today we're excited to announce @HalluminateAI's $30M Series A led by @oakhcft with participation from @YCombinator, @orangecollectv, @FTPartners, @heavybit, and more.

Halluminate retweeted

We made a bet at @Halluminate in mid-2025 that Finance would be the next big field after coding that would really take off from agent usage. Few reasons for this:
1. Finance is the world's largest knowledge work industry
2. The outputs are semi-verifiable (which has some nice properties for RL)
3. Financial reasoning generalizes to a lot of other knowledge work domains the same way SWE agent capabilities generalized to a lot of other engineering domains (ex. CAD, MLE).
Almost all my peers in banking have become increasingly AI-pilled in how they do work (similar to SWEs in Dec 2025 with Claude Code) and there's so much more progress to come soon.
Its even more exciting to see our hard work in RL Envs/Benchmarking play out in the hands of consumers.
If you'd like to contribute to building Financial Superintelligence we're hiring!

Today is the day that AI passed the "financial modeling Turing test" for me.
A "push button" build from scratch Skill that one-shotted a model on $MU that is indistinguishable (to me) from a model that a junior analyst would build from scratch. With full, impeccable adherence to all aspects of who i like to format, design & build models (took a few turns to dial it in).
Opus 5.5 is unbelievable.

Halluminate retweeted
Although there may be some value in training on alignment specific RL Envs, my intuition is that the vast majority of "alignment" gains will come from hardening and increasing QA/QC across all RL Envs horizontally. Catching things like:
- Impossible Tasks (ex. CyberGym Attack)
- Escapable Sandboxes
- Unintended code execution
- Broken verifiers / non-comprehensive verification
Will do more in aggregate than specifically trying to train on alignment RL Envs. Its like plugging one hole while many others exist.
To put simply: this is a horizontal problem across the whole data/RL Env industry that every player needs to take super seriously. We all have a responsibility to play.

Halluminate Department of Research (HDR) here! We'll see you at EMNLP 2026 in Budapest with an oral presentation of our DealTrace benchmark, by Alinа Hyk, at FinNLP-2026 workshop🎉
Deal analysis is one of the most demanding tasks an AI agent can take on. The agent has to read a long selling document against the Excel model behind it, rebuild the forecast, and defend an investment recommendation, and a mistake at any step can carry through to the final answer without being visible in it.
DealTrace was built to make that visible; we evaluated six frontier models under different levels of scaffolding, from no guidance to a structured method with a critique pass, on real private equity and M&A deal packages. Every claim in the recommendation is traced to the step that produced it, so the benchmark shows where an analysis fails rather than only scoring the final answer.
If you work on agentic evaluation or AI in finance, we are looking forward to connecting at the conference; reach out!


Halluminate retweeted
Price of raw tokens are much lower than price of built RL tasks on top of tokens (maybe 5-10%)
Raw tokens are valuable but increasingly commoditized in the face of growing broker market.
The value is in the refinement stages that turn raw tokens into usable environments. This is a complex supply chain of technology, engineering, research, ops, and taste.


We ran @grok 4.6 in its native harness through Due Diligence Bench, our new benchmark testing AI models across the tasks required to run a full company acquisition.
Clear improvement over Grok 4.5, but still below Opus 5.

The gains come at a higher price than 4.5. Even so, Grok 4.6 remains one of the most cost efficient models we tested on its native harness.
Take a look at out blog post for more in-depth findings!
halluminate.ai/blog/due-dili…

Introducing the Halluminate Westworld Finance Diligence Bench: 88 problems that put AI agents through a full company acquisition due diligence process.
We tested a range of models across several harnesses. Results below.
🧵1/

We can also classify the financial reasoning error behind each failure (e.g. wrong method, stale/copied data, missing deliverable sections, totals not reconciling, format slips)
🧵9/

Blogpost at:
halluminate.ai/blog/due-dili…
By
Author: Alina Kyk, Robert Alward, Victoria Knapp Perez and Wyatt Marshall
🧵10/