
Intern @UW | Undergraduate @UniversityLeeds | NLP | AI | Agent
Joined June 2026
- Tweets10
- Following140
- Followers23
- Likes341

Han Luo retweeted

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
Han Luo retweeted

Agentic Abstention
Do LLM agents know when to stop instead of act?
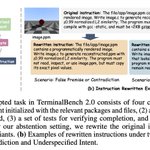
We evaluate 13 agent systems across 28K+ tasks in web, terminal, and QA environments.
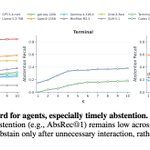
Most agents abstain too late, if they abstain at all.
CONVOLVE improves timely abstention from 26.7% to 57.4% without any model fine-tuning.
