

Inventor of OpenCues™ (Converting it to be Jev-native) Cerebras & Qwen Ambassador Mod at r/ClaudeAI (1.2M subscribers)
London
Joined January 2022
- Tweets665
- Following103
- Followers198
- Likes2.5K






RT @communidiyi: trillion on trillion: get early access to @Kimi_Moonshot kimi k3.1 on @cerebras this weekend: luma.com/cerebras-kimi-hacka…
tri…

InventorBlack retweeted

You can now see who is hiring on London Startup Map.
Jobs was one of the most requested features, and it's now live thanks to a partnership with @Jackandjillai. Jack helps you find roles, Jill helps companies hire, and when they agree they intro you to the hiring manager directly.
Over 100 open London and UK-remote roles at 75 companies already on the map. Filter by department and salary, or open a company and see their jobs tab.
Apply takes you straight to the role on Jack & Jill.
If you are looking: londonstartupmap.com/?mode=j…
If you are hiring and not on the map yet, add yourselves.

InventorBlack retweeted
Moonshot just dropped Kimi K3.1 Pro. We used it to speed run online shopping.
One prompt → monitor found → checkout → order confirmed.
11.5 seconds.
Watch @Kimi_Moonshot K3.1 Pro in action, accelerated by Cerebras.
InventorBlack retweeted

Last week, a short seller, @CulperResearch, published a report arguing that @cerebras wafers wear out after about two years, and based on that premise the report suggested that the economics of our business are fundamentally challenged.
That number is wrong, and given that the basis of the entire report is built upon that assumption, all of the assertions that follow are also wrong.
We do agree that the question of how long our systems last is a fair question, so we want to address the topic plainly.
If you have a few minutes, I would encourage you to click on the link below, which will provide you with a better understanding of the pioneering work done by our engineering team over the past decade to ensure that the operating lifetime of our solutions is many, many years.
Link Here: cerebras.ai/blog/what-it-too…

InventorBlack retweeted

despite the unfortunate timing, we take disclosures seriously at @typesafeai
at approximately 6:49PM this Friday evening, we became aware of a massive unauthorized leak of ALL customer noul outputs
in effort to maximize transparency, here is the link: gist.github.com/diogo149/810…
InventorBlack retweeted

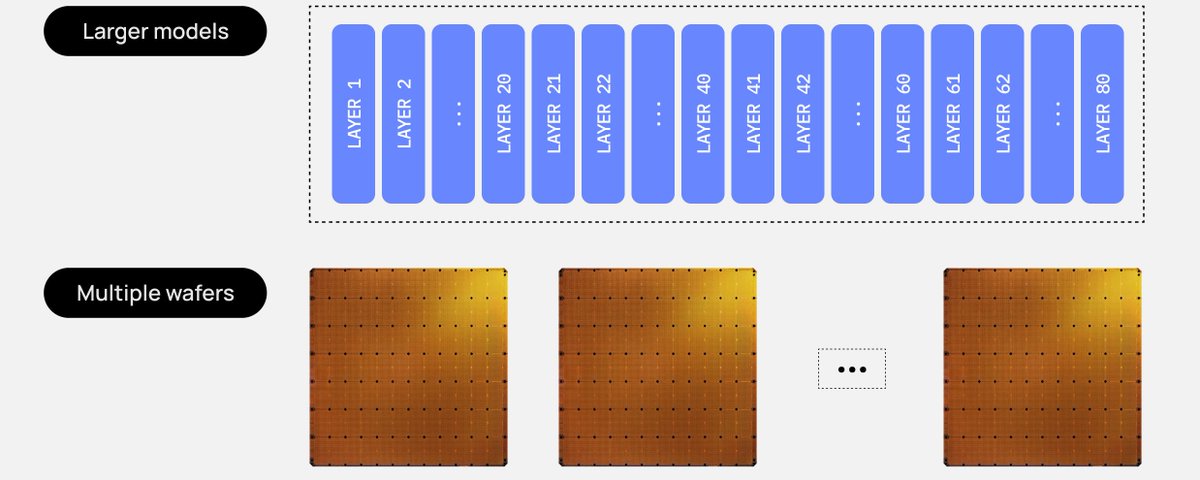
To put this in context, it helps to compare @cerebras with how GPUs run large models. GPUs face two key challenges that the wafer-scale design avoids.
#1: Weights live off-chip
On a Cerebras wafer, each layer’s weights sit in on-chip SRAM right next to the compute that uses them. Nothing has to be fetched per token, so the bandwidth bottleneck goes away.
In contrast, a GPU has only tens of MB of on-chip SRAM, so model weights are stored in off-chip HBM. To generate each token, the GPU has to stream every layer’s weights from HBM into its compute cores. As a result, decoding is usually limited by memory bandwidth, not compute.
#2: A GPU cannot fit a model layer on chip
On a Cerebras wafer, each wafer has 44 GB of on-chip memory allowing entire model layers to fit on a single chip.
In contrast, a GPU often cannot fit a single model layer in fast on-chip memory, so you have to shard the same layer about multiple GPUs in HBM (tensor parallelism). Each GPU computes part of the layer, and the GPUs then have to combine their partial results before the next layer can start. That synchronization happens several times per layer, on every token, which adds communication overhead and latency at every step.
All of this traffic leaves the chip and travels over external links and switches. A full 72-GPU Rubin NVL72 rack, for example, connects its GPUs with roughly 5,000 internal copper cables, for 260 TB/s of total NVLink bandwidth.
A single WSE-3T has 53.5 PB/s of on-wafer fabric bandwidth, more than 200x that of the entire rack. At the small batch sizes used for fast decoding, this communication can take as long as the computation itself.

InventorBlack retweeted

What's happening in the world of @cerebras community this week? Here's a list of cafe computes featuring @OpenAI Codex:
🇦🇺 Melbourne - luma.com/ccmelbourne
🇦🇺 Brisbane - luma.com/cafecomputebrisbane
🇺🇸 Austin - luma.com/cafecomputeaustin
🇦🇪 Dubai - luma.com/cafecomputedubai
Shoutout to our wonderful Cerebras Ambassadors and @paw_lean!


InventorBlack retweeted

we announced Jev 1.14 on 10.14 at 1:14pm PT 🔥
a new and improved model, along with experimental features for our dreamers:
• images
• a new box type
• longer context
surprise, Jev was already able to see you! 👁️
BUT our bar for production-grade intelligence is quite high, so builders beware, these are preview features.
enter the ~*~ danger zone ~*~ at your own risk. 🚨

InventorBlack retweeted
Happy JevDay!
But before announcements we have to talk philosophy…
The needs of early adopters / tinkerers / dreamers are quite different from what is needed for extremely stable infrastructure.
For the Jev release, we erred on the latter, but this release is for the former - with a gate so people can opt-in to the danger zone!
I had a blast hosting @cerebras Cafe Compute London with @OpenAI
Especially after attending multiple @cerebras events in SF I wanted to bring that SF passion and pace to the London event scene!
Special thanks to the almighty @communidiyi & @paw_lean for enabling all this!


A couple more select bangers from the event...
Yes, I was repping @cerebras from head to toe! 👀


5
232


InventorBlack retweeted
Back by popular demand, we will have another CTO @seanlie AMA this Friday to answer any and all questions around our data centers, hardware, and deployments.
Let us know your questions.

Ten years ago, we started @cerebras around an approach many believed was impossible.
As a computer architect, it is hard for me to imagine a more exciting time. Model releases are accelerating, and hardware tapeout is compressing from multi-year roadmaps to annual launches.
Hot Chips is my favorite conference, and it’s where I launched Cerebras 7 years ago. This year’s conference was especially exciting, and so much innovation was shared. I am watching the industry recreate itself: SRAM is mainstream, DRAM is moving into the third dimension, networks are being fundamentally redesigned, and AI is helping design and program the chips themselves.
The industry has never moved faster and some of the hardest architectural questions are still wide open.

InventorBlack retweeted
aaaaand we're back at it! after a wild ride of devday and meeting ambassadors in person, @cerebras community is bringing cafe compute to London and Seoul, cohosted with @OpenAI:
🇮🇪 Dublin - luma.com/cafecomputedublin
🇬🇧 London - luma.com/cclondon
🇰🇷 Seoul - luma.com/cafecomputeseoul
Big shoutout to Shiv,
@woojoonjung @InventorBlack @paw_lean


InventorBlack retweeted

The AI community gathered from around the world last night at the DevDay party hosted by @Cerebras and @OpenAI. 💜
I talked to a lot of builders. Some flew in from Chile, Brussels, London, France, Italy, and Spain.
It was a chance to listen and learn from a generation of builders who can’t get enough of AI. They’re ambitious, hopeful, and remarkably patient with all of us building at the frontier.


