

Local AI - DGX Spark + 48GB M5 Pro. Building @MuraTalkApp and some other things. Ngunnawal land 🌏 Views my own.
Canberra, Australia
Joined October 2026
- Tweets1.8K
- Following447
- Followers418
- Likes2.1K




Pinned Tweet
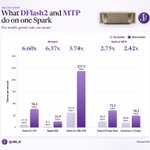
Up to 6.6x faster local AI on a single DGX Spark 🚀
Same test, five models, without and with a drafter.
DFlash2
Qwen3.8-27B: 11.9 to 78.2 tok/s (6.60x)
Ripple 65B: 4.1 to 25.9 (6.37x)
Qwen3.6-35B-A3B: 63.4 to 237.3 (3.74x)
Built-in MTP
Qwen3.8 Flash-Next: 26.3 to 72.5 (2.75x)
Nemotron 3.5 Super: 20.8 to 50.2 (2.42x)
Output matched token for token every time. Still amazes me what one little box can do 😄


Well that didn’t take long.
Face unlock for iPhone Duo is now available in beta.
Early reports suggest it’s not quite as effective as Touch ID and falls back on Touch ID every now and then, including for Apple Pay.
Will this be enough to get you off the fence for the iPhone Duo?

iPhone Duo owners, check this out! 👀🔥
A quick hands on look at unlocking the Duo in the latest beta. Watch how the lock screen transitions straight into the home screen.
It’s these little interactions that make using a foldable so satisfying. What do you think?
1
177
Humanity is sick.
Does he have the cure?
Take a thought-provoking and compelling journey through the limits of wellness, longevity and alternative thinking.
Podman, a new documentary from independent Australian filmmaker (and my childhood friend) Simon Dall.
Out now.
youtu.be/2updBsuit0k

1
2
172
Full documentary available for free on YouTube.
youtu.be/o6547b_8e-w
99
Wisdom from Elshayib here.
Knowing how AI works - and understanding at a fundamental and technical level both the benefits and the risks - is going to make you incredibly important in the medium to long term.

We're so lucky to be at the heart of the AI industry, informed and updated about the most important technology of our time.
The technology that's reshaping every aspect of our lives and potentially the most beneficial and yet dangerous to ever exist.
A lot of you are more important than you think as we play a big role in all of this whether we use AI or build it or even simply talking about it.
2
3
112
Imagine what local AI will be like a year from now.
Now imagine 5 years.
Are you seriously still delaying your purchase of compute?
3
3
160
Now this is interesting!
228bn parameter flash model. 68bn of them on n-gram. Small enough to fit on a single DGX spark with SSD offloading of the n-gram table.
Matches Haiku 5.5 on high effort, with open weights coming soon.
The Chinese labs are lifting their game big time 🚀🚀

⚡Meet Hy4 flash, the cheapest model for everyday productivity. Matches Claude Haiku 5.5 (high) on daily work (human blind tests), yet 18x task cost reduction. API pricing (per 1M tokens): $0.003 cached · $0.070 input · $0.281 output. 🔗:hy.tencent.ai/research/hy4-f…

Bit of a self-indulgent one, sorry 😅 but, with a heavy dose of gratitude, I wanted to take a moment to look back on the week that was.
283 to 403 followers. 384 replies to 199 of you. over 90,000 views, and 77% of them came from just chatting in the replies.
Biggest thanks to the people I talked with most: @carthurj @MiaAI_lab @ashxhart @CerebralCoding_ @TekonBurns @TheAmazeX @NeoAIForecast 🙏
A month ago this account was zero. Grateful for every one of you. Back to building 🛠️

4
7
227
It’s here! Qwen 4 Max has been released!
It OUTPERFORMS opus 5.5 on several key benchmarks.
And yes, Qwen says open weights of smaller models are coming 🚀🚀🚀👀
Qwen 4 27B is near!

📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: qwen.ai/blog?id=qwen4-max
- API: qwencloud.com/models/qwen4-m…
- Token Plan: qwencloud.com/pricing/token-…
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀

3
151

Good point from @TekonBurns. Metering by the token means the provider has an economic incentive to maximise token use.
With local models your incentive is to run the most efficient system possible.

List price per million tokens is officially a trap.
The New Stack ran Claude Fable 5.2 against GPT-6 Astra on three real coding and billing tasks today.
Fable 5.2 is priced 20% lower per token on paper, yet it burned 5x more tokens, ran 2.6x longer, and billed 236% higher at $13.39 versus $3.99.
Token-efficient reasoning models mogging verbose thinkers.
1
1
200
*Insert 404, followers not found joke here* 😂
Thank you to all 404 beautiful humans who've followed along. I'm loving the connections and having a space to geek out and push what's possible with local AI.
Just over a month ago that number was zero. It only went up because you gave me a chance.
Thanks for being here 🙏 And if you like what I'm serving up, drop me a follow!

6
264
Omg. Just watch it. How is this even real.

Hey @grok, on a scale of 1 to 100, with 100 being the hardest, how difficult was this Starship catch that SpaceX pulled off today?
1
2
107