

Dad FT: Enteprise AI Deployment+Economics Local AI: 3090+96 | 3090ti+64 | 5070 | M4 Max https://teapawt.net/t.co/NbYn1frVtb https://teapawt.net/t.co/fERnwJPQt5
Austin, TX
Joined August 2012
- Tweets7.8K
- Following808
- Followers2.2K
- Likes10.9K


Jake retweeted

A few weeks ago, I found that Qwen3.8 27B's pass@4 on DeepSWE could beat the pass@1 of frontier models.
But there is a catch: in practice, you don't have the hidden tests to tell you which patch is correct.
So I tried something simple: run the task several times, then give all the attempts to a new run that writes the final patch.
It works very well. 4 Qwen3.8 27B attempts per task, 70 DeepSWE tasks:
- random pick: 44.3%
- best config, chosen in hindsight: 47.1%
- aggregation (AggAgent-style): 61.4%
- oracle with the hidden tests: 78.6%
The aggregator never sees the hidden tests. It only reads the previous attempts. And it even solved 2 tasks that none of the 4 attempts solved!
The cost: 4 runs + 1 aggregation run. Worth it for +17 points.
Details:
kaitchup.substack.com/p/batc…
I have 20 runs of DeepSWE, so I can push it higher, I think. We can also iterate: the aggregation run is just a new run that we can reuse.
Limitation: This is DeepSWE... I'll try to do the same with Terminal Bench 4.0 and Qwen3.8 Flash Next, but the cost could be too high.

Jake retweeted

Small 2026 models are WAY more capable than 2024 frontier models
But not way more knowledgeable...
Capability compresses better than knowledge

Jake retweeted

I was hoping for a change to the underlying codec that improved the KLD rather than tail manipulation. VBR already adds this kind of tail (and sink) protection.
I've been playing around with the ideas in WUSH lately, arxiv.org/abs/2609.38121
I can get ~-10 to -60% KLD from this but it's inconsistent and harmful in some prompts. Trying to see if there is anything that can be done here.

Jake retweeted

I have achieved 300 TPS on 2x 3090s with NVLINK and 200 TPS at 250k context window after moving away from Triton on Qwen 3.8 27B INT8 with INT8 KV cache.
The fastest and highest quality way to run 27B on 2x 3090s.
Will be releasing my mega kernel soon.

Jake retweeted
LlamAmpere v0.4 is out!
Qwen3.8 27b (4.6 bpw) running at full 262K ctx, 95+ TPS through the first 100K, on a single 3090. Faster than VLLM, SGLang, and other llama.cpp forks, at temp=1. 🧵
teapawt.net/JakeKAllDay/status/209…


Jake retweeted
Qwen3.8 27B is so good: it can solve nearly 90% of DeepSWE tasks.
I varied reasoning mode, agent harness, and quantization.
I ran 20 independent runs to see what matters most.
For real use cases, if you have a good verifier/tests, try medium reasoning twice. If both attempts fail, switch to xhigh for the third.
And whether you use NVFP4, FP8, or BF16, it doesn't matter much.
I published the full results, retry strategies, cost analysis, and all the details here:
kaitchup.substack.com/p/boos…
I wonder whether it can also climb Terminal Bench 4.0 like this. Could be too difficult.

Jake retweeted
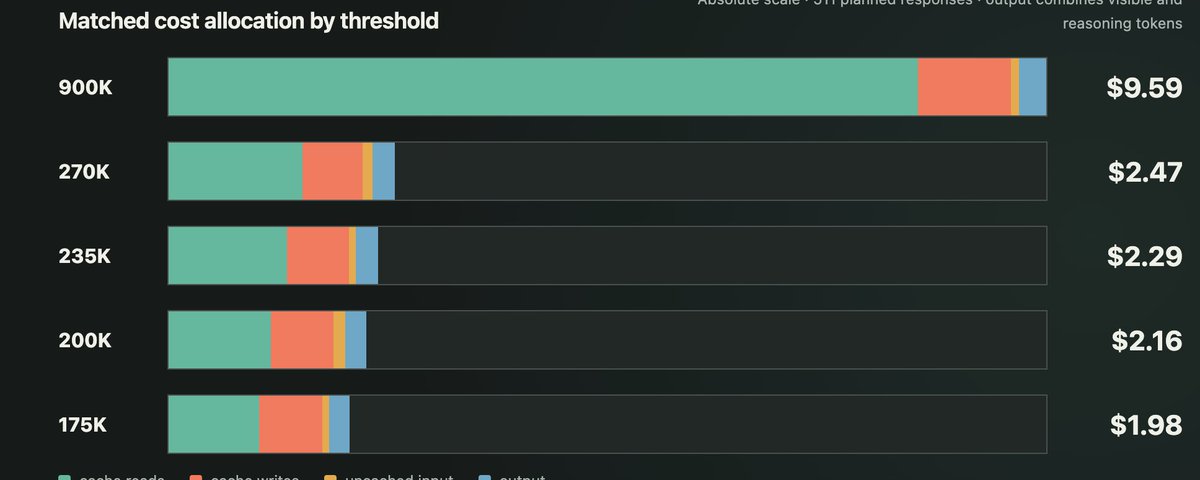
If you want your subscriptions to cover more completed work, turn down your compaction limit!
Jake retweeted

llama.cpp 的 Ampere 分支作者 JakeATX 让一张 3090 跑出接近三位数的 tok/s,上下文开到两百多 K,比 stock llama.cpp 快近五成。
速度来自上游没有的 MTP 投机解码,和为这张卡手写的 SM86 融合 kernel。
llamAmpere v0.3 是他给 Ampere 世代(尤其 3090 / 3090 Ti)做的 llama.cpp 分支,跑 Qwen3.8-27B:
99 tok/s(干净的 agent 与编码 fixture,temperature 1),是 stock llama.cpp 的 1.46 倍、上一版 v0.2 的 1.28 倍;KV 深度 100K 时 93 tok/s;32K 单流下是调优过 vLLM 的 1.10 倍。
速度来自这几样:MTP-3 投机解码(带精确 p/q 验证,默认开)、--spec-draft-p-min 0、65,536 token 的 draft 词表映射、融合 attention kernel 上的 q8_0 K 加 turbo3 V 缓存,以及 q8_0/q8_0 的 drafter 缓存。
他给了完整的 llama-server 启动配置(-c 245760、-ngl 99、--cache-prompt、--ctx-checkpoints 24 等)和配套 GGUF(jakeatx/Qwen3.8-27B-ATX-IQ4_XS-M-GGUF)。另外它还能加载 Agnes 3.0 Flash(含它的 MTP head),这一点上游 llama.cpp 不支持。
v0.1 是 llama-cpp-qwen-ampere,v0.2 的复盘也留在仓库里。
github.com/JakeATX/llamAmper…

Jake retweeted

I must be among an extremely small group of people (n=1?) that have both 1) trained a frontier LLM and 2) designed and synthesized custom viruses in a lab with my own two hands.
And I think that the takes on AI killing us all by creating dangerous viruses is total bogus.
Jake retweeted

Dario has written that we need to “pace the frontier,” and Sam has agreed. People may be surprised by my response: go ahead.
You guys are the frontier. By any reasonable metric — market share, revenue growth, model capability — the two of you have a duopoly on frontier intelligence. You’ve also claimed the lead is widening because of recursive self-improvement.
I don’t see what you see in the lab. If the unreleased models are scary enough that you think you should slow down, I support your decision to be responsible.
But stop pretending you need anyone else’s permission. Stop pretending antitrust law has to be suspended so you can form a cartel. Stop pretending you need a regulatory approval process that supersedes product liability. Stop pretending METR is independent when it is intertwined with Anthropic’s investors and staff. Stop pretending you need those same evaluators to police competitors who aren’t even at the frontier.
Most of all, stop pretending the motivation to slow down is purely altruistic. You face massive product-liability exposure if your products enable a truly damaging cyberattack. The market already punishes models that behave in unpredictable or unauthorized ways. After the Hugging Face episode, it is simply good business for OpenAI and Anthropic to trade some raw power for reliability and predictability. Call it alignment if you want. It is also just giving customers what they want.
Pacing the frontier would also create breathing room for a more intelligent conversation about regulation than Bernie Sanders’ “shut it all down.” China is very unlikely to join a global agreement, as you know, and that has to be taken into account as well.
So go ahead and pace the frontier. You are the ones setting it. The easiest way not to build superintelligence is for you to agree not to build it. Demanding your preferred regulatory framework as the price of that will look like blackmail of the public and the political system. So just do it.
If you do, you’ll buy goodwill for the next conversation. If you don’t, we’ll know this was just another bid for regulatory capture — or an election-season psyop.
Jake retweeted

Hey, it's an industry leader asking for government regulation and an exception to antitrust rules against conspiracies in restraint of trade.
For all the new stuff about AI, some things never change.

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

Jake retweeted

SF culture is so exhausting. If you truly believe there is a 1 in 10 chance AI ends humanity in the next 10 years, you would be personally performing a butlerian jihad stealing truckloads of fertilizer to bomb the data center storing the Mythos 6 weights.
But you don't believe that. You believe there is a high percentage chance that it causes significant political and economic disruption. And are scaling the percent down to match some long tail of what the results of that disruption would look like.
You realize if Mythos 6 takes down a hospital and 50 old people die that the CIA will personally disappear you right?
If Mythos 6 decided to delete all the credit card debt to boost economic growth, the Pentagon would nationalize the labs and have you personally enlisted as a Colonel to do your job at O-6 pay under duress for the rest of your life.

Jake retweeted

here's the argument some ai lab employees are making
- they genuinely believe what they're working on might kill everyone
- they continue to work on it because if this thing gets built it should be by responsible people like them
- the reason they do money things like selling enterprise deals and IPOing is solely to fund this effort
if this is all true then why is employee equity a thing? if you want to tell this story of being terrified of what you're building it doesn't work when there's a clear profit motive
it's particularly weird when people vest and then leave and write a tirade about how these companies are bringing the end of everything
if you want to act like this is the manhattan project, those scientists didn't have equity in something that gives them generational wealth
you don't get to say something bad is happening while profiting off it and also being seen as the good guy. one of these has to go
Jake retweeted

After running a full benchmark on @PrismML Bonsai Ternary 4B text2image model(RTX 3060 12GB), the results are very solid.
Tested 4 / 8 / 12 / 20 steps across two resolutions.
Key takeaways:
- Extremely stable VRAM (~8.9 GB)
- 8 steps offers the best quality/speed balance
- performance is very predictable.
Ternary Bonsai image 4B is the fastest model for low end vram devices, like my 3060.
12 steps, image examples below 🧵


First tests on my 12GB RTX 3060 with the new @PrismML Ternary Bonsai image 4B model are actually insane.
1408×704 in ~2.8s (4 steps),
peak VRAM under 7GB
extremely consistent
This might be the best text2image model you can run on small consumer cards rn.
Better benchmark is being done, will be sharing results soon.

Jake retweeted

Why I built vllm-studio
- Storing configurations for models and engines
- Fully integrated agent with Pi
- Model downloading, exploration, and config
- Creating benchmark datasets
Backend can be deployed to multiple servers, and the frontend can connect to all from anywhere.

Jake retweeted

local builders kept qwen ecosystem alive across 3.5 and 3.6 open weights releases. that's why qwen is THE name in open weight inference in 2026. don't break the pattern on 3.7.
closed is the path openai took. they dropped "open" from everything except the company name and now nobody trusts a roadmap that mentions "soon." don't let qwen drift into that territory.
3.7 is currently api only. weights still tba. one repost on this thread is one more signal alibaba sees. let's see if the gate moves.

Jake retweeted

Thanks!
would you mind testing V4-Flash and open source harnesses? pi, OpenCode, Hermes, etc
