
NLP Researcher
北京, 中华人民共和国
Joined August 2012
- Tweets184
- Following84
- Followers667
- Likes133





Pinned Tweet
We are extremely overwhelmed and honored to receive the IEEE Signal Processing Society Best Paper Award (2025) for our paper "Pre-Training with Whole Word Masking for Chinese BERT", published in IEEE/ACM TASLP (2021). 🎉🎉🎉 @IEEEsps #IEEE signalprocessingsociety.org/…

3
219
Following #ACL2026, I'm honored to be recognized as an Outstanding Senior Area Chair (SAC) once again at #EMNLP2026 !

7
273
Been using GPT-5.6-sol for optimizing ARR-SAC-Tool. Hope this will save some time for SACs, especially for the heavy load in ARR May cycle. github.com/ymcui/ARR-SAC-Too…

4
362
I am honored to be recognized among the Great Senior Area Chairs at ACL 2026. #nlproc #acl2026 #acl2026nlp @aclmeeting

6
380
Sharing my ARR SAC tool (based on my old jupyter notebook). You can load OpenReview venue, inspect paper status, read comments, score distributions, and export commitment-stage papers to Excel for ranking. Runs on your own machine. github.com/ymcui/ARR-SAC-Too… #nlproc #ARR #emnlp2026

2
202

AI vs. the Olympiad: Can Multimodal LLMs Truly 'See' Chemistry? communities.springernature.c…
2
60
Excited to share our first paper in @CommsChem (Nature Portfolio) 🎉🎉🎉
We systematically evaluate multimodal large language models on chemistry Olympiad–level problems, revealing where current models succeed and where they still struggle. #AI4Chemistry #LLM #MultimodalAI #NLP


Evaluating large language models on multimodal chemistry olympiad exams bit.ly/4iTupwV
5
2
247
(5/x) Occlusion-based saliency analysis. By masking image regions and measuring confidence drops,baseline MLLMs often rely on spurious visual cues, while CoT shifts attention toward chemically meaningful structures, improving both grounding and confidence. nature.com/articles/s42004-0…

34
(4/x) When seeing hurts: visual input can degrade performance. Adding visual input sometimes reduces accuracy, especially in smaller models. Larger models tend to balance textual and visual signals better, which may be key to achieving strong performance. nature.com/articles/s42004-0…

1
34
(3/x) Task-type breakdown. Current multimodal LLMs perform well on tables and charts, but struggle with molecular structures and experimental apparatus, which require chemistry-specific visual understanding and domain knowledge. nature.com/articles/s42004-0…

1
19
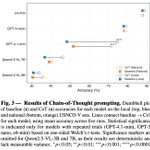
(2/x) CoT generally improves chemical reasoning performance. Analysis show that CoT is especially helpful for mid-tier models. For e.g., GPT-4.1-mini achieves 20~26 accuracy improvement with CoT, while less significant for small/large-scale models. nature.com/articles/s42004-0…

1
32
(1/x) we curate a chemistry benchmark based on USNCO exams, spanning over two decades, consisting of 473 real multimodal QA problems. It covers a broad spectrum of chemistry topics, including general, physical, organic, inorganic, and analytical chemistry. nature.com/articles/s42004-0…

1
47

Happy to introduce Chinese-LLaMA-Alpaca-3, which is our 3rd open-source projects on #Llama series. We release Llama-3-Chinese-8B and Llama-3-Chinese-8B-Instruct with continual PT/SFT on Chinese corpora. Check our project: github.com/ymcui/Chinese-LLa… #nlproc #llama3

2
414
Through our empirical experiments on creating Chinese Mixtral, we find that extending vocabulary might NOT be a necessity for LLM language transfer. As usual, we open-source Chinese-Mixtral(-Instruct) at GitHub/HF: github.com/ymcui/Chinese-Mix… arXiv Paper: arxiv.org/abs/2403.01851

We release Chinese-LLaMA-2-7B and Chinese-Alpaca-2-7B based on #Llama-2, which achieved significant improvements over our first-gen Chinese-LLaMA/Alpaca, even surpass 13B models on some metrics. Check our GitHub repo: github.com/ymcui/Chinese-LLa… #llm #NLProc


Happy to release our multimodal pre-trained model VLE, which achieved top performance on VCR. We also set up a pipeline with captioning model and LLM to generate much user-friendly answers for VQA. Resources, code, and demo are available through: github.com/iflytek/VLE 🎉🎉🎉
