

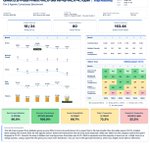




This is a really good Deepseek V4.1 Flash-1017 Quant from @ddalcu. Inline tells the tale at reasoning of 50 which translates to low in MLX-Serve and a reasoning budget of 9k using PI as the harness. Peak run of 91.6% or 22/24 and a median of 82.6% 20/24. Snapshot & Compaction was markedly improved on this set of benches for this quant. Added the oQ4e quant test from Oct 23rd for comparison purposes. The size is a little misleading because 1 includes the engram embeddings and the other does not. This one by default keeps the engrams on SSD with 209 gb resident in memory. oQ4e requires 289 gb minimum if "SSD N-gram Offload" is used. This quant is probably going to be my daily driver. It is crazy to see the impact of software, both MLX Serve and oMLX, and the M5 hardware on runtimes. I'll be testing this at higher reasoning to see if the ceiling moves, the oQ4e quant too.


The real upgrade here is that anyone who has an M3 Ultra 512 can for the cool price of around $5k upgrade their M3 512 to an M5 Ultra equivalent minus some loss in decode compared to the M5 Ultra. Reasonable if you purchased the M3 more than 12 months ago. If you already have an M5 Max or higher, prefill is the big win. That is a huge software win here. I'm sure we will see this in other inference software pretty quickly. This is a big upgrade for the M3 Ultra 512.

oMLX 0.7.4.dev1 is out!
github.com/jundot/omlx/relea…
With the new Prefill Accelerator, connect an M5 Max to your big Mac and prefill up to 2.9x faster!
Prefill Accelerator (64K prompt, M3 Ultra 512GB + M5 Max 128GB)
- DeepSeek V4.1 Flash: 1,060 -> 3,123 tok/s (+195%)
- Qwen3.8 Flash-Next: 1,309 -> 3,666 tok/s (+180%)
- GLM-5.3 Flash: 540 -> 1,388 tok/s (+157%)
- MiniMax M3.1: 297 -> 569 tok/s (+92%)
- An M5 Max 64GB still adds 30-118%, and decode speed stays the same.
Faster DeepSeek V4.1 with A8 and buffer pool improvements
- Prefill on M5 Ultra is 43-48% faster, 32K goes 2,631 -> 3,779 tok/s (+44%).
- oQ4e builds now run INT8 Activation Prefill on M5.
Faster Qwen3.8 Flash-Next
- FP16 builds get the fused kernels. Decode on M3 Ultra goes 38.9 -> 63.0 tok/s (+62%), and +23% on M2 Max.
- Decode after long prompts is 3-5% faster on M5 Max.
Better for agents
- Parallel tool results from Claude Code reach the model in call order, so Qwen no longer pairs a result with the wrong call.
- Agent sessions on a cluster reuse the prompt cache across tool turns, 743 -> 9,266 cached tokens by the fifth turn.
- Switch oMLX models inside Codex and Copilot with /model.
Also in 0.7.4.dev1
- Ming-3.0 TTS with a 2x faster decode loop.
- Ask AI can use an oMLX server on another Mac.
- Check for model updates in the macOS app.
- German across the web dashboard and the macOS app.
- Batched decode with 6 requests on 8-bit models is 16% faster.
A big thank you to everyone who sent PRs, reported bugs and tested builds for this release, and a warm welcome to the five new contributors!


Ok, this one has been coming for a while and it will be the start of quite a few reviews on MLX Serve functionality and quants. @ddalcu is doing some really cool stuff and has a cohort of sharp people contributing to his software too. This review is of his Qwen3.8-Flash-Next-MLX-Serve-iQ-MLX-4.7bpw quant specifically. This quant is surprisingly good. I say surprisingly because it is 36gb smaller than the oQ4e quant. Scores on these benches have changed due to switching 8 visible tests to hidden because they were causing model behavior changes. Hence the switch from 16 to 24.

Qwen3.8-Flash-Next-oQ4e-mtp on Medium. A narrow drop in performance of 4% with the same Score median as XHigh of 20. Less reasoning exceptions on this one with the same 9k reasoning token budget. Additional comments in the assessment.

Attached is the before and after results for testing Qwen3.8-Flash-Next-oQ4e-mtp on XHigh after significant changes to the bench. I made changes in the bench yesterday to mitigate the issue of the model inferring it was being graded. It worked and increased the model's ability to find defects - at least for Qwen3.8 Flash next. I addressed any naming that inferred testing, moved visible tests into hidden tests outside the sandbox (these were included originally to assist the model), removed references to Tiers. Basically cleaned/removed anything visible to the agent that might infer a test was occurring. It still occasionally infers testing/grading from recognizing that the repo looks synthetic, because it is. The 8 visible tests previously used but not scored in my output are now hidden.
This means the testing scores moved up to 24 total tests versus 16. The model no longer has any ability to see those 8 tests it used to see. Also tightened the prompt a little. References to grader/hidden tests dropped dramatically. I had 27 references across 7 runs versus 30-40 per run prior.
This does mean that the baseline starts over because the scoring has changed and it should.
The results are obvious in the before scores from Sep 9th versus today. A jump of 20% in scoring. 68.8% - 84%. This is with a reasoning budget of 9k tokens. The reasoning exceptions per run were in the 2-3 range with the majority being 2. Snapshot & Compaction is a weakness for this model. I intend to run the 6-bit series again to see if the 84% number changes.
What sent me down this path was that I had started testing mlx-serve and one of David's @ddalcu smaller quants and I needed a baseline in my mind to be able to compare to. This is what forced me to revisit this entire process. Happy I did because it was worthwhile 😊 Having the M5 has dramatically increased my ability to iterate quickly.


Something that is very frustrating and should be trained out of models. Constantly thinking that any case where the model is asked to find defects is subject to hidden tests. The number of times I see a model identify an issue and then skip addressing the issue because it is afraid it will break a hypothetical test - ugh.
My God, Qwen3.8 Flash Next reasoning is ridiculous. I'm starting to look at mlx-serve and some of the smaller model quants created specific to this software. Realizing I need to go back and re-bench this model for decent and current comparable metrics.
Glad I had chunking enabled in the Qwen3.8 28b judging model lol. The log output minus tools was 3.4 mb which required 4 chunks to fit in the 27b context window. This is THE most reasoning I have seen from any model to date. I'm going to do some oMLX benches later to see what those look like. In prior oMLX runs, reasoning was unlimited but I also did not have the technical bench coverage I do now so they might be worse 🤷♂️.
I have an unlimited reasoning instance running currently which is how I usually start benching, and this run will be forced to completion by the 210 minute time out at this point. But this permits me to see the reasoning tokens used per turn and reassess for future runs.
The first bench of Qwen3.8-Flash-Next-MLX-Serve-iQ-MLX-4.7bpw (75gb) on Mlx-serve 26.10.3 scored a 13/16 on the agentic bench at Xhigh with a reasoning token budget of 7k over 95 minutes. this was on an M3, not M5 yet. This is actually a really good score, especially from a quant of this size. However, I'm running into consistency issues in running the typical bench of 6 I do. Any quant can provide a single good run, what matters is the consistent range. This particular quant is reasoning excessively, much more so than prior quants I have tested for Qwen3.8 Flash Next, so I'm trying to find a good reasoning budget to do it justice. Also had my first OOM bug introduced by this model for the first time forcing a change to the bench framework. I can run the 8-bit version but I'm interested in seeing how much I can get from the smaller quant.
Democrats just can't stop eating their own, can they? This is why Independents have increased so much and folks have stopped aligning with the 2-party system. Side note: Any Dem nominee siding with a Trump nominated candidate was never a Democrat. wsj.com/livecoverage/midterm…
