
Student researcher exploring AI infrastructure, hardware, and how tech companies create value. Substack: https://teapawt.net/t.co/nAojxfbQWh
Silicon Valley
Joined June 2025
- Tweets331
- Following790
- Followers37
- Likes55



Pinned Tweet
If AI is going to reach software-like margins, the economics cannot depend on the lab paying for every token forever.
Local LLMs are not just a privacy story. They are a margin story.
New essay on Substack: kylezz.substack.com/p/the-fr…

Kylezz retweeted

Vision foundation models like DINO and SigLip now power much of robot learning.
But they are built for RGB. What about depth?
Introducing DeFM: a foundation model for depth images, built for robotics.
🌐 de-fm.github.io
Weights, code, and demo are out today 🧵
Kylezz retweeted

Quick video showing some of the "Reactivity & Recovery" capabilities of Instant Robot Learning at @Machenta_:
1. One real demonstration: putting blue object in grey box and closing box.
2. Robot reacts in real time when object and box are moved around, with a closed-loop end-to-end policy.
3. Robot recovers when object is pulled out of gripper, and re-grasps it.
4. Robot notices that object is removed from box, and places it back in.
5. Robot notices that box lid is opened, and re-closes it.
The important part:
1. None of this reactivity and recovery needed to be shown in the demonstration: it all comes from the intelligence of the pre-trained model.
2. Model has never seen these objects before. It is trained 100% in simulation, and these objects were not in the simulation.
machenta.com/blog/instant-ro…
Kylezz retweeted

Meet MatAnyone-E: high-quality video matting, much faster. ✂️
Compared with MatAnyone 2 at 4K:
⚡ ~7.4× faster inference
💾 Just 7.6% of the peak GPU memory
✨ Comparable matting quality
Runs at 73 FPS at 1080p and 29 FPS at 4K on a single NVIDIA H200.
Project: shuyun-wang.github.io/projec…
Paper: arxiv.org/abs/2610.35724
Code (coming soon): github.com/Shuyun-Wang/MatAn…
Kylezz retweeted

Wrote up how agent tool calls interact with GPU memory and scheduling in inference serving.


Kylezz retweeted

Introducing 𝑨𝒕𝒕𝒆𝒏𝒕𝒊𝒐𝒏 𝑹𝒆𝒔𝒊𝒅𝒖𝒂𝒍𝒔: Rethinking depth-wise aggregation.
Residual connections have long relied on fixed, uniform accumulation. Inspired by the duality of time and depth, we introduce Attention Residuals, replacing standard depth-wise recurrence with learned, input-dependent attention over preceding layers.
🔹 Enables networks to selectively retrieve past representations, naturally mitigating dilution and hidden-state growth.
🔹 Introduces Block AttnRes, partitioning layers into compressed blocks to make cross-layer attention practical at scale.
🔹 Serves as an efficient drop-in replacement, demonstrating a 1.25x compute advantage with negligible (<2%) inference latency overhead.
🔹 Validated on the Kimi Linear architecture (48B total, 3B activated parameters), delivering consistent downstream performance gains.
🔗Full report:
github.com/MoonshotAI/Attent…

Kylezz retweeted

AI weather models see the world on a grid. One cell over the Alps says 24°C, but inside it, the peaks are 12°C and the valleys 36°C.
Big labs fix this by building bigger, higher-resolution models. We tried something cheaper.
Keep the global model, and train a small model on top that learns how mountains, valleys and coasts shape the local weather.
We trained it in 1 hour on a single GPU. It takes forecasts over France from ~28 km to 5.5 km, and gets closer to what weather stations actually measure, especially in the mountains.
You can read more about how we trained the model on our blog post: huggingface.co/blog/EmmaScha…
and try the model yourself on our demo space: huggingface.co/spaces/EmmaSc…
Kylezz retweeted

Context isn’t just what you put in a prompt. It’s also what stands between a robot and its goal. Robot policies in everyday environments must generalize not only across objects, but also across the spatial contexts in which they appear.
Excited to share COWBOY 🤠 (CoRL 2026) — our sim-to-real recipe for contextual whole-body manipulation. One generalist grasping policy coordinates base, arm, dexterous hand, and active vision end-to-end, adapting its motion and grasps to object and scene geometry. Trained in simulation, deployed zero-shot in the wild.
w/ @JasonJZLiu @LiuMuxinl
🧵(1/N)
I bet such flow and local decisions models will soon be integrated into operating systems


A good overview. TBH you could just change the final layer of an LLM and its activation function to build your own Jev. It will likely be absorbed into LLMs in the next few months. Definitely something very suitable for local.

Kylezz retweeted

A full MIT course on visual autonomous navigation.
If you work on robotics, drones, or self-driving systems, this one is worth bookmarking‼️
MIT’s Visual Navigation for Autonomous Vehicles course covers the full perception-to-control stack, not just isolated algorithms.
What it focuses on:
• 2D and 3D vision for navigation
• Visual and visual-inertial odometry for state estimation
• Place recognition and SLAM for localization and mapping
• Trajectory optimization for motion planning
• Learning-based perception in geometric settings
All material is available publicly, including slides and notes.
📍vnav.mit.edu/
If you know other solid resources on vision-based autonomy, feel free to share them.
—-
Weekly robotics and AI insights.
Subscribe free: 22astronauts.com

Kylezz retweeted

Brilliant paper by NVIDIA.
they found a way to make KV cache transferable between models.
the target model skips prefill entirely, and the conversion runs 2.7 to 25x faster than processing the context again.
let's understand why this is so important today.
LLM APIs are stateless, so every turn sends the entire conversation back to the model. the model reads it again before generating a new token, and all of it is billed as input.
prompt caching lets providers hold the KV cache for a stable prefix and bill cache hits at roughly 10% of the base input rate because that compute was already done.
this 90% reduction is one of the biggest levers in LLM serving.
but the cache only works on the model that produced it. since keys and values depend on that model's weights, another model cannot directly reuse them.
this becomes a problem with LLM routing.
if traffic moves to another model for cost or capability reasons, the accumulated KV cache becomes invalid.
the entire context must be processed again and billed at full rate.
NVIDIA's recent paper treats this as a representation problem.
prefill's main output is the KV cache, so transferring it means converting one model's cache into the representation another model expects.
they first checked whether this conversion had enough structure to exploit.
for Qwen3 14B → 32B, a linear regression from a single source layer reconstructed 56% of the variance in the target model's keys.
because models can have different layer counts, there is no natural one-to-one layer mapping.
so, for every target layer, they rank the source layers by predictive power and use the top eight together.
that pushes reconstruction to 79%.
the mapper has three parts:
> each target layer and head gets its own linear map, solved in closed form instead of with gradient descent.
> cross-layer selection chooses the source layers that best predict each target layer. their ablation shows this contributes the most.
> RoPE adds a position-dependent rotation to keys. they remove it, fit the mapping in position-free space, then apply the target model's rotation again at inference.
across six model pairs from Qwen3, Llama 3.1, and Ministral 3, four retain 73 to 98% of the receiving model's standalone accuracy.
conversion is also 3 to 25x faster than processing the context again.
prior cross-model KV reuse methods either train a neural adapter for every pair or require architecturally identical models.
this approach is closed-form and training-free, but there are still important limitations.
every tested pair belongs to the same model family, such as Qwen → Qwen or Llama → Llama.
cross-family transfer is still future work.
the tested pairs also share KV head count and per-head dimension. mismatched configurations remain untested.
and the work currently covers dense full-attention models only, not sliding-window or attention-recurrent hybrids.
link to the paper: arxiv.org/abs/2608.03893
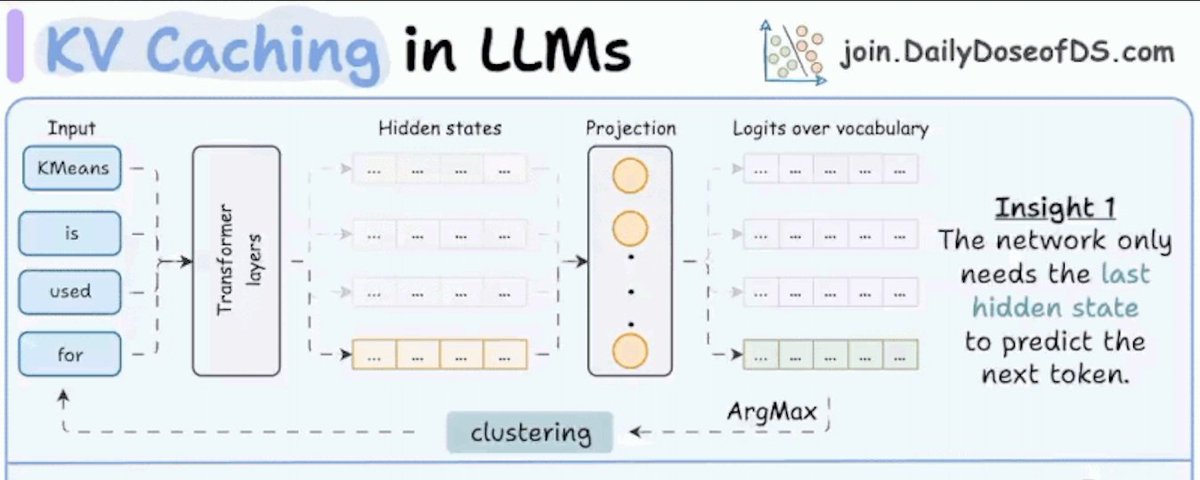
i wrote a first-principles breakdown of how KV caching works
the article is quoted below.
Kylezz retweeted

Chinese researchers did it again!
Moonshot AI proved that 95% of attention computation is completely wasted..
They’ve open-sourced the exact attention mechanism powering Kimi's long context.. and it's 16x faster.
It’s called MoBA (Mixture of Block Attention).
Every time you feed an AI a massive prompt, every token desperately tries to look at every single token that came before it.
The math scales quadratically ($O(N^2)$).
It’s like reading a 500-page book and re-reading the entire thing from word one every single time you want to understand a new sentence.
Moonshot looked at this waste and said: No.
Instead of forcing full, brute-force attention across everything, MoBA applies the principles of Mixture of Experts (MoE) directly to the attention layer.
How it works:
• It chops the context history into discrete blocks.
• A lightweight dynamic gating mechanism lets each query token instantly "vote" and route only to the specific blocks that actually matter.
• It achieves up to 95% sparsity on long contexts without sacrificing performance.
The results are staggering:
It maintains full-attention accuracy on 1-million-token contexts while slashing massive compute overhead.
We are watching the structural efficiency barrier of long-context AI get smashed in real-time.
While Western labs argue about how to afford million-token context windows, Moonshot open-sourced the blueprint to make them radically cheap.

I have been playing with freetoken for the last two weeks and was really impressed. It figured out a clever way of caching the experts in MOE models by automatically trading off system memory bandwidth and VRAM bandwidth. Local AI exploitation is imminent now!

Qwen3.8-Flash-Next now runs on a single RTX 5090 at 68.3 tok/s — no extreme quantization, no speculative decoding.
· Production-level checkpoint: GB300-validated NVFP4 checkpoint from RadixArk
· 63GB host RAM — less than what 1-bit quants of this model need
· The 51GB n-gram table? It lives on your NVMe, at ~0.5% throughput cost
In the video: one prompt → a playable minecraft-style world, then FreeToken on my 5090 desktop fixing a real FreeToken bug in 10.5 minutes.
Meet FreeToken 🧵
I thought I had to stick with Q3 and 60k q8 context on my 5080. This is really cool

🤯 So you can actually get a 100K context & ~50 tps on one 16GB GPU.
Putting Qwen3.8-27B onto an RTX 4070 Ti super is the kind of localmaxxing I ❤️ to hear about.
Recipe 👇
🧠 Qwen3.8-27B
🎮 RTX 4070 Ti SUPER — 16GB
📚 100,000-token context
⚡ 47–50 tok/s
💾 15.93GB VRAM
This recipe stacks several optimizations:
✧ 13.5GB hybrid GGUF
→ attention stays IQ4_XS
→ FFNs compressed to IQ3_S
✧ BeeLlama.cpp instead of stock llama.cpp
✧ KVarN compressed KV cache
→ K = kvarn5
→ V = kvarn4
✧ Last 1,024 KV tokens kept at higher precision
✧ MTP-2 speculative decoding
Changing the KV cache from kvarn5/kvarn5 → kvarn5/kvarn4 alone reportedly freed another ~6% VRAM and pushed context from 88K → 100K.
🎯 So this is what they did …
Weights → selectively quantized.
KV cache → selectively compressed.
Recent context → kept high precision.
Decode → speculated.
⚠️ This uses BeeLlama.cpp, a llama.cpp fork, not stock llama.cpp/LM Studio, and the 47–50 tps number is a community report.
Links 👇
🔗 Reddit r/LocalLLaMA/comments/1w1lq7u/qwen_38_27b_at_50_toks_with_100k_context_on_a/

I have been playing with the Freetoken project in the past week and was really impressed. It trades off the GPU and CPU memory bandwidth and cache the most frequently used experts in moe models on GPU allowing to run large moe models much faster github.com/FlashML-org/FreeT…

Kylezz retweeted

Instead of watching 2 hours of Netflix tonight, watch this Stanford lecture. It’s the clearest end-to-end explanation I’ve seen of how ChatGPT and Claude are actually built.
From tokenization and BPE all the way to the transformer architecture, training pipeline, and next-token decoding.
Whether you’ve never written a line of AI code or you’ve been shipping agents every day, this 2h 34min session will click things into place that most people take years to figure out.
Bookmark it and clear the time this weekend, because this might be the single most valuable thing you learn all month.
Kylezz retweeted

Updated CS 8803 "Large Language Model" class at @GeorgiaTech this year for 2026!
The reading list spans pretraining, MoE, reasoning, RL & self-play, agents, long-context, test-time scaling, diffusion LMs, safety, interpretability, and more.
👉 cocoxu.github.io/CS8803-LLM-…
🔗 docs.google.com/spreadsheets…


