

Building TeeChat — private AI you can trust. Verifiable confidentiality, not trust-me marketing.
Global
Joined February 2023
- Tweets373
- Following18
- Followers12.1K
- Likes253




Code isn’t the secret. The secrets are in the code.
Cline + TeeChat OpenAPI — mid-size model (so far), confidential chat. Tests, regressions, docs, scripts — without shipping that context to a vendor that can read it. teechat.ai/blog/openapi-with…

We haven’t talked enough about Free Local in TeeChat.
Install Ollama, pull Qwen 3.6 or Gemma 4, point the desktop app at it. No account. Prompts stay on your machine.
Search still needs the web. A small task model writes the queries — not the 31B. You bring your own search API (Brave, etc.). Those queries do leave the machine.
History is markdown in a folder you choose — not our cloud, not a local database.
It is not ChatGPT. A 31B plus search pages will eat 32GB, and long context makes TTFT worse. For homelab scripts, logs, and drafts you review yourself, it is enough.
Hosted is separate: we never see the prompt (encrypted to the engine). Same folder. Not anonymous.
Desktop only. Setup: teechat.ai/blog/local-ollama…

Same OpenAPI as WorkBuddy:
teechat.ai/blog/openapi-ga-w…
Optional verify:
teechat.ai/blog/verify-opena…
☕🔒 teechat.ai
Chat Custom Provider: base URL openapi.teechat.ai (configurator completes /v1).
Memory: agents.defaults.memorySearch → openai-compatible →
openapi.teechat.ai/v1 + your TeeChat sk-…
Models (confirm with authenticated GET /v1/models):
• Qwen/Qwen3.6-35B-A3B
• Qwen/Qwen3-Embedding-0.6B
New guide: run **OpenClaw** on TeeChat OpenAPI — chat **and** memory embeddings on confidential computing.
teechat.ai/blog/openapi-with…

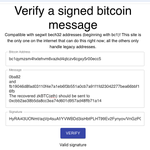
Updated: how to verify TeeChat’s OpenAPI service.
Desktop full verify · web/CLI light preview · open-source CLI full verify.
teechat.ai/blog/verify-opena…
TeeChat OpenAPI is generally available: openapi.teechat.ai
OpenAI-compatible chat (+ embeddings) on confidential computing. WorkBuddy walkthrough now; OpenClaw next.
teechat.ai/blog/openapi-ga-w…
Second layer: TEE so the host OS can’t read prompts in cleartext—and Settings → Verify so you don’t have to take our word for it.
Guide: teechat.ai/blog/how-to-verif…
Product: teechat.ai
TeeChat choice (by design): • No public chat share URLs / short links
• No sitemap of conversations
• Share = copy or export under your control
Cut the crawl surface first. Then harden the server path.
This week’s Claude share-link indexing story isn’t a hack. It’s what happens when “anyone with the link” is a real webpage—and indexing isn’t default-blocked.
Thread: what we refuse to ship, and how you can check.
New on the blog: Beyond "opt out of training" — how confidential computing defines data sovereignty in the AI era.
Four myths we hear in security reviews:
→ Plaintext inference is inevitable
→ Training opt-out is enough
→ Redaction fixes everything
→ Only the biggest model works
Mechanism-level answers + citations.
Read: teechat.ai/blog/confidential…
中文: teechat.ai/zh/blog/confident…
Open source code 1) the Open Privacy Envelop protocol for secure AI inference github.com/Lightec-AI/OPE 2) the inference engine github.com/Lightec-AI/Infere… . And more importantly, How to verify confidential chat on TeeChat teechat.ai/blog/how-to-verif…

If you've ever asked "who can read my prompt when the model runs?" — that's the bar we built for.
Try TeeChat → chat.teechat.ai
Learn more → teechat.ai
RT if your team pastes client material into AI. ☕🔒
Live now:
• Web → chat.teechat.ai
• macOS Apple Silicon / Windows desktop
• Linux / Intel Mac rolling out
Mobile iOS & Android in development. Same account carries over.
Apple's Private Cloud Compute raised awareness: cloud AI can be privacy-shaped.
TeeChat applies that to work chat you own — long threads, Research, Deck Studio — with verification you can show, not just a keynote.
Built for ordinary professional moments:
• Lawyer redlining an NDA
• Biotech sanity-checking an IND outline
• Founder rehearsing investor objections
• Employee rewriting a resume with real employer names
Not paranoia — incentives.
"Trust us" isn't enough for client questionnaires.
Open Settings → Verify before you send sensitive work. See trust evidence for the engine handling your prompt.
Audit the stack: github.com/Lightec-AI/OPE


Something must decrypt to run the model.
That job goes to our open-source InferenceEngine — inside a TEE (CPU + GPU confidential computing), not on a generic admin laptop.
Gateway blind. Engine measured. Model runs.
When you use hosted AI at chat.teechat.ai:
Your client encrypts before send.
Our gateway forwards ciphertext only — it shouldn't need your plain text to route.
Open blueprints. A measured vault. Verify before you trust.
