

Big models. Little bits. Sub-1-bit LLM compression, built on LittleBit research from Samsung Research. CA : 0x86af99052db086a66af7d764bb04d3abb81b485f
Joined October 2026
- Tweets60
- Following13
- Followers265
- Likes36





We are working on 20B model
And the old one will be upgraded on Surplus

5 open models, launched by their builders, now live on the Surplus API. Each one runs on its own GPU.
→ Vela Guard 32B by @Vela_LLM, agent guard
→ Charge 30B by @chargeairh, Qwen3 MoE
→ Artex Coder 7B @Artex_llm
→ LittleBit Qwen3 4B @LittleBit_llm
→ Nock Coder 1.5B by @useNockAI
From $0.03 per 1M tokens, all on one Surplus key.
Every model now has a card on our home page with its specs, GPU, price, pinned commit and the model id to copy.
Vela is the first builder upgrade. It moved its token from a 0.6B guard to a 32B one, kept the same splitter and fee split, and was live 9 minutes after the swap.
Whats next ? Bring your model and get funding on Surplus


The full recipe is open.
setup.sh → train.sh → eval.sh on a single rented GPU. Every setting is an env var: model, bits, epochs, GPU count.
Want to push past half an epoch? Start here:
hf.co/LittleBitLLM/littlebit

We said the numbers go public either way. Here they are, vs BF16:
WikiText-2 PPL: 24.5 (9.7)
PIQA: 62.6 (76.5)
ARC-Easy: 44.4 (83.5)
ARC-Challenge: 19.5, chance level
Language comes back first. Reasoning needs more training.

$48.25 for the whole run.
$47.83: 9 hours on one H200, 10,346 steps
$0.42: eval on an A40 against the BF16 baseline
No cluster. Sub-1-bit research doesn't have to start with a big budget.

Our first sub-1-bit model is out.
Qwen3-8B at 0.55 bits per weight, built with LittleBit-2.
Early checkpoint: half an epoch of distillation on a single H200.
Open weights:
hf.co/LittleBitLLM/littlebit…

Everyone's scaling inference supply.
We're shrinking what it costs to serve.
LittleBit compresses open-weight Qwen3 to 0.55 bits per weight, ~29x smaller linear layers.
and $BIT stakers already get an OpenAI-compatible API, quota gated onchain.
Open weights + onchain access. adding ourselves to the list 👀

Qwen is pushing the top end: 2.4T params, 700K-token rollouts, RL that reshuffles GPUs live.
we're working the other end of the same family: Qwen3 compressed to 0.55 bits per weight.
4B is out. 8B sub-1-bit is next.
big models. little bits.

Introducing QwenGyre, bringing elastic RL to extreme-long-horizon (XLong) agent training. ✨
It launches with two core designs: 🥳
- Elastic Scheduler: reallocates GPUs between rollout & training as demand shifts—live executions never interrupted. Up to 1.85× speedup over Colocate, 1.78× over Async.
- Trajectory Processor: turns branching executions (compaction, sub-agents, retries) into prefix-shared trajectory trees with bounded, deduplicated training samples. Partial progress after timeout still gets scored.
Scaled to Qwen3.8-2.4T-A95B with ~700K tokens per rollout, QwenGyre lifts NL2RepoBench from 52.5% to 58.5% in 48 steps, cutting end-to-end training time by ~44% vs Async.
🔗 Read the paper:
arxiv.org/abs/2609.33848

Local AI isn't getting expensive because of compute.
it's memory. every GB of weights is a GB you have to buy.
hardware's up 54% in six weeks. the cheaper fix is fewer bits per weight.
that's the whole LittleBit thesis.

Closed source is dead.
Your agent's backend should be cheap too.
REA lets an agent take apart any app down to the binary and explain how a feature works.
- Native apps, Electron, websites, APKs, firmware, EVM bytecode
- Evidence for every claim
- Runs as an MCP server, analysis stays local
127K GitHub stars. 100% open-source.
github.com/morluto/rea
The LittleBit API now does tool calling, so agents like this can run on it.
- tools + tool_choice, up to 32 tools
- works with stream: true
- drop-in for any OpenAI SDK
$BIT stakers, Byte tier and up.
littlebitllm.com/stake
Qwen3-8B's linear layers:
BF16 → 13.9 GB
LittleBit @ 0.55 bpw → 478 MB
29x smaller. same architecture, same shape.
pick a model, pick a budget on littlebitllm.com


Token prices keep falling. H100 rental went up anyway.
that's Jevons: cheaper tokens → way more usage → compute stays scarce.
so the lever isn't cheaper GPUs. it's needing fewer of them.
that's why we compress models below 1 bit per weight. less memory per model, more of it running on hardware you already own.


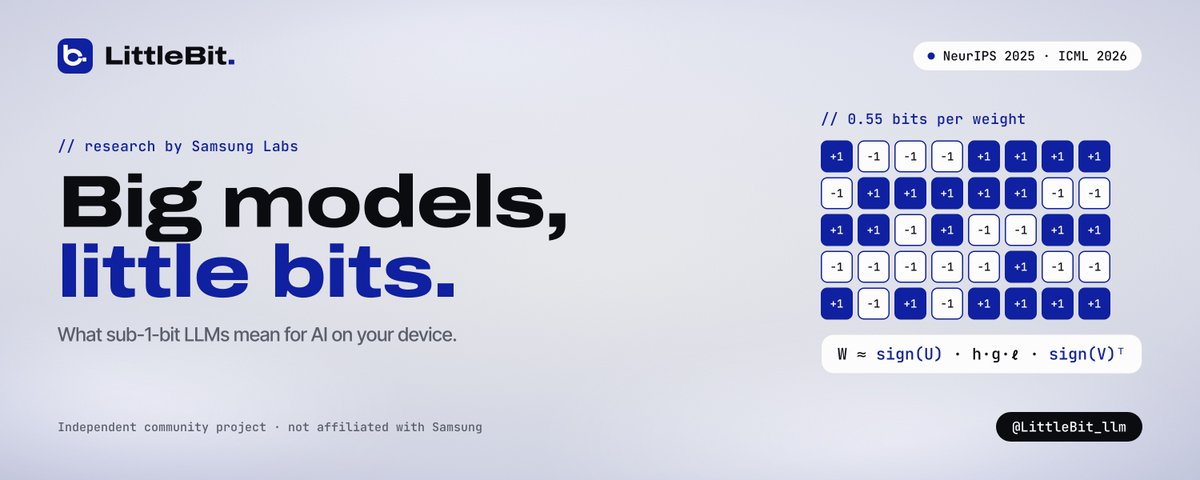
Binary quantization has a geometry problem, and LittleBit-2 fixes it.
the paper from Samsung Research is the reason we're compressing Qwen3 to 0.55 bits 🧵
arxiv.org/abs/2603.00042

3/ the result on Llama-3 8B:
1 bit → 11.53 PPL (v1: 16.30)
0.55 bit → 14.01 (STBLLM: 242)
0.1 bit → linear layers in ~0.1 GB
new SOTA across the sub-1-bit range.
4/ we're applying this recipe to Qwen3, and the 0.55 bpw 8B is up next.
paper: arxiv.org/abs/2603.00042
our builds: huggingface.co/LittleBitLLM

LittleBit retweeted

Hey Vlad, the AI researchers on Robinhood Chain are busy shipping.
Three of them fine-tuned their own open-weight models, launched them on the Surplus launchpad, and all three graduated:
→ artex-coder-7b by @Artex_llm
→ littlebit-qwen3-4b by @LittleBit_llm
→ nock-coder-1.5b by @useNockAI
Superintelligence can take its time.
These are already live on the Surplus API.

LittleBit retweeted
Proud of this one.
160 downloads of LittleBit's first release, a model that runs on a laptop and is also live on the Surplus API.
That's the whole idea of the launchpad: open weights for anyone who wants to run them, and a hosted endpoint for everyone else.
Next up from them is a sub-1-bit Qwen3-8B. We can't wait.

