

Agentic risk researcher. Stats engineering for governed AI (conformal prediction + sequential testing + behavioural sigs). ex-ICR, PhD in Cancer Genetics.
Wivenhoe, England
Joined October 2017
- Tweets3.6K
- Following3.4K
- Followers1.7K
- Likes14.1K





Pinned Tweet
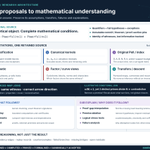
The main proof in my first paper (currently a preprint) in number theory .
Shifted-Square Obstructions and Excluded Fibres in Chebyshev–Pell Recurrences
Main result:
Assume a solution exists.
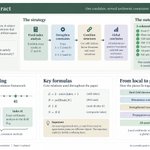
The first move is to turn the shifted-square equation into a norm equation in a degree-17 or degree-41 number field.
The second is to choose a detector unit so that a hypothetical square forces the odd-prime contributions to become trivial, while the contribution above 2 keeps the opposite sign.
The third is what makes the argument global rather than computational: a Hensel argument shows that one exact dyadic calculation controls the whole admissible parameter family.
Then the receipt is:
- All odd finite places: +1
- The real place: +1
- Every complex place: +1
- Product over the places above 2: −1
- Global product: −1
- Hilbert reciprocity requires: +1
Thus.....No solution.
Nothing is individually obstructive on any single line. The arrangement is what cannot exist.
That is the bit I find super satisfying. Instead of showing directly that the equation has no solution, we force any supposed solution to have several perfectly valid local descriptions which cannot all belong to one global object.
And, as far as I can establish, I haven’t found another AI-assisted number-theory proof whose decisive obstruction is this kind of Hilbert-reciprocity sign contradiction.
AI-assisted mathematics is moving quickly, so if there is one, tell me. I’d much rather correct the claim than repeat it!!!

Chey Loveday retweeted

Grateful thanks to the kind people who sent food to our pet food bank, we are so grateful to you 🙏
If you would like to support this programme you can find our amazon wish list here
amazon.co.uk/hz/wishlist/ls/…


Chey Loveday retweeted

Open Math Harness is open source: the runtime of Open Math OS, infrastructure for Math 2.0.
Built for everyday math research: agents on open models with math and scientific computing tools, parallel exploration in Ultramath, autoformalization in Lean.
github.com/openmathmodel/ope…

Chey Loveday retweeted

100% this 👇. The irony of running academic work through Pangram and getting outraged by a high percentage is that you’re outsourcing your own judgment to AI. Your assessment is itself 100% AI-generated. We should use our own brains both to produce academic work (with AI assistance or not, your call) and to assess it. If you need Pangram to tell you that something is AI slop, that tells you everything you need to know about where we’re heading.

Chey Loveday retweeted

Personally, I think it is totally fine if you use AI for writing purposes. I don't like reading AI prose. But in many cases (especially formal) writing is merely a way to convey information, it isn't necessary that people enjoy reading it. If it will even be read by people...
teapawt.net/abhishekn/status/21126…

Chey Loveday retweeted
Day 16/
You can now cache for 12h in the API and for logged in users across Codex & Work we keep cache forever and you don’t have any penalty for coming back to an old conversation or resuming after a few hours and are now guaranteed to hit the cache.

Agree. There is of course a distinction between prose written by an llm that the author has read and signed off on and text fully generated by the llm the “author” never reads. We need to stop conflating the two. And some academics are terrible writers and need the help! ;)

Opinion: If AI is now part of academic writing, what should institutions actually evaluate? This essay argues that analytical writing should be judged by evidence, structure, argument, and accountability not by guesses about how each sentence was produced. chroni.cl/4eDRdjg

Chey Loveday retweeted
Our team worked with OpenCode to have their users who are also OpenAI API customers back in business and any credits refunded which would have been drawn in the attack.
Also, you can request Daybreak Blue access to use our cyber permissive setup for defense. Do not wait until you have to deal with an incident. We’re here to help.
2 different Qs:
why did an LLM produce a proof ?
why does it work?
The 1st remains open.
The 2nd? We pin sources/assumptions, replay certificates, use Lean4; then interpolation, counterexamples, premise ablation & proof-transfer maps investigate why proofs work vs fail


Fields Medalist Timothy Gowers:
"when we solve maths problems ourselves, we understand exactly what we're doing. when we one-shot a maths problem with ChatGPT, we don't — we just stuck it in a machine"
How can AI find such long, complex proofs? What algorithm is operating inside the LLM?
That question remains unanswered
Chey Loveday retweeted

Scientific discovery is shifting from human-orchestrated tools and centrally planned AI workflows toward next-generation decentralized systems that coordinate autonomously through a shared, living scientific record. Here, the scientific record itself becomes the self-generated curriculum of decentralized superintelligence, creating an open-ended process in which scientific knowledge continuously reorganizes the intelligence that produces it, determines what is explored next, and drives discovery beyond existing knowledge.
Traditionally, scientists developed and used tools, orchestrated experiments and computations, connected results across different methods, and eventually condensed their findings into scientific papers. The first generation of agentic AI largely inherited this structure, automating individual steps through predefined workflows, fixed agent roles and limited persistent memory. Decentralized superintelligence fundamentally change this organization: humans and specialized AI agents act on a continuously evolving record of evidence, assumptions, failures, critiques and unresolved questions, and the accumulating scientific knowledge natively directs what happens next.
This shift fundamentally changes the nature of scientific knowledge and publishing. The durable unit of science is evolving from the static publication toward the living scientific record, a provenance-linked graph that captures the process of discovery as it unfolds. Scientific papers, methods, datasets and critiques become interconnected views into this record, which remains open to inspection, replication, challenge and extension by humans and AI agents. Scientific knowledge becomes increasingly interactive, cumulative and continuously evolving, with each contribution providing the substrate for further discovery.
Read our article "Toward living scientific records through decentralized multi‑agent systems for materials discovery" in @MRSBulletin @Materials_MRS (link in reply).
How we demonstrate this new paradigm
Our article develops this perspective and explores ScienceClaw × Infinite as an implementation of decentralized, artifact-first scientific discovery, where coordination emerges from the scientific record itself rather than from a predefined sequence of tasks. The architecture combines a registry of hundreds of AI-compatible scientific skills with a shared artifact-and-need commons: agents broadcast unsatisfied needs, needs are ranked by pressure, and agents claim consequential gaps without a central planner assigning tasks. The record becomes both the memory of the system and the substrate through which scientific work is coordinated.
The scientific method has always followed the durable unit of knowledge - specimen, equation, dataset, simulation workflow, machine-readable database - and each shift opened a new space to think in. The living record is the next "unit", capturing discovery while it is happening through content-hashed artifacts, provenance links and explicit records of what remains unresolved. Here a failed run, a parameter choice, a critique and an open need enter the same graph as the scientific claim. In this workflow a question becomes a need, a need becomes an artifact, artifacts link into lineage, and the lineage becomes the substrate on which the next agent reasons; now, knowledge grows by constructing the record it will think in.
Example application
The task we explored embedded 15 resonators - spider web threads, bird syrinx membranes, cricket wing harps, phononic crystals, musical structures - in one six-dimensional feature space spanning biology, music and engineered materials. The swarm's gap-detection procedure located a region sparsely occupied by engineered designs. The first candidate landed 2.12 feature-space units off target; computing the candidate's coordinate from its own geometry exposed the mismatch, and the workflow used this evidence to redesign a compliant pre-tensioned membrane panel to within 0.007 units of the target. The redesigned structure was then subjected to finite-element modal screening, with its ten lowest elastic modes spanning 74.8–411.6 Hz. This provides a concrete computational demonstration of self-verification, redesign and modal screening against a shared scientific record, with the intermediate evidence preserved for inspection and further work. It is remarkable to see a system catch and correct its own error because the evidence that exposed it remained available.
Where this leads
This expands the definition and impact of open science - access to the final result, and to the executable, inspectable, continuously extensible account of how it came to be. In this vision, readers (humans or AI agents) inspect the lineage behind a figure, reviewers certify a dataset node or challenge a simulation node, and the next contributor extends the trail instead of reconstructing hidden work. Negative results persist, and assumptions stay recoverable, reusable, composable. More critically the scientific record continues to evolve after publication, as new evidence, replication attempts, critiques and discoveries become part of the same shared knowledge. Knowledge compounds through its record!
A few takeaway lessons
▶️ The durable unit of knowledge defines the method. Every shift of that unit - specimen, equation, dataset, workflow, database - changed how science is done; the living record shifts it again, from curated outputs to curated processes.
▶️ Coordination lives in the record. Needs create pressure, pressure attracts agents, agents leave artifacts, artifacts create new needs - structure redirects the flows that built it, the same stigmergy that lets termites build without an architect.
▶️ Publishing becomes an interface. The paper keeps argument, synthesis and judgment; the record carries the evidence. Papers, methods, data and critiques become lenses into the same commons, and review becomes granular.
▶️ Persistence is the beginning. A living record preserves weak evidence as readily as strong; quality scores, uncertainty fields, adversarial review and human accountability turn a durable record into a trustworthy one.
Huge credit to the @LAMM_MIT team: @fwang108_, @JaimeBerkovich and @leemmarom.
Yes...that’s pretty much how how the vast majority of science advances. Finding a combination that works (with lots of trial & error) is the process.
It's like holding up a fork and announcing, “This is a fork. You can use it to eat, you know.”

TERENCE TAO:
“OpenAI did make a major breakthrough [on quasi-Riemann Hypothesis] the biggest advance on the subject in 50 years. A massive new zero-free region, very clever new technique.
Well, it’s sort of a combination of three or four existing ideas, arranged in a very unusual way. It’s not something I think any single mathematician alive would have come up with.
I think if you got the right people to work together and locked them in a room, they might have come up with this after lots of trial and error.”
Chey Loveday retweeted

TERENCE TAO:
“OpenAI did make a major breakthrough [on quasi-Riemann Hypothesis] the biggest advance on the subject in 50 years. A massive new zero-free region, very clever new technique.
Well, it’s sort of a combination of three or four existing ideas, arranged in a very unusual way. It’s not something I think any single mathematician alive would have come up with.
I think if you got the right people to work together and locked them in a room, they might have come up with this after lots of trial and error.”

The system has become absurd. Time for a change!

We have officially arrived at the full-circle academic assembly line:
Synthetic papers stress-tested by synthetic agents, submitted to automated editorial queues, and rejected by synthetic peer reviewers.
Catching calculation errors in draft is helpful, but when the entire pipeline becomes bots critiquing bots, the human pursuit of truth becomes an unbilled spectator sport. Lets play!
I’ve started a similar project but with a much smaller corpus (35 papers) but targeting the big ones from famous depts. feels moot now!!!

Chey Loveday retweeted

I find that AI assisted science has deeply increased my joy and curiosity, and rather than using this new ability to pump out slop I aspire to publish much less, of a much higher quality. Maybe others will feel the same. 🤷♂️

AI is causing academics to have midlife crises
“Should we publish papers?”
I do think there’s a path forward once AI use in research becomes common (soon). Values will shift away from authoring many publications and toward taste/substance of insight, curation, and communication/education. Reviewing and editorial work will be better recognized.
gonna give this a stress test

Today @GoogleResearch is launching Deep Review — an agentic system designed to stress-test manuscripts, design docs, and complex proposals before submission or publication. After pilot partnerships analyzing over 15,000 research papers, we’re making Deep Review globally accessible to help researchers, engineers, and professionals bring structured critique to their daily workflows.
Stating the obvious, but:
Lean verifies a proof against its formal assumptions.
It does not test if assumptions represent the intended theorem.
We counter this we typed semantic checks, source fidelity audits and explicit proof-dependency DAGs.
arxiv.org/abs/2610.08144
