

research engineer; control systems; maker; innovator; programmer; dad. Uganda - UK - USA - NZ - ... If you follow me & have 0 posts I will remove and block you
Ōtautahi, Aotearoa
Joined February 2011
- Tweets5.6K
- Following2.7K
- Followers660
- Likes36.6K




Pinned Tweet
Parameter identification in a changing environment. Variable action space Continuous Reinforcement Learning Automata xitter.cf/MNWH/status/6918438015… – at Christchurch City, New Zealand


Enjoyed watching a bizzare film. Recommend.
Good Luck, Have fun, Don't Die. rottentomatoes.com/m/good_lu…

Mark Howell retweeted

Godfather of AI: "If you sleep well tonight, you may not have understood this lecture."
This 47-minute lecture is the best thing I saw about AI in the last few months.
It will definitely help you understand how it actually works and where it's going.
Geoffrey Hinton built the neural networks behind every AI alive, then quit Google to warn the world about it.
The part nobody wanted to hear:
> AI is already developing abilities its creators didn't intend
> in most cognitive tasks it's already ahead of us
> the question is no longer if it surpasses us but when
> the only decision left is which side of that line you're on
Right now the average person opens Claude, types something, gets an answer, closes the tab.
They think they're using AI. they're using maybe 10% of it.
I went through his entire lecture, built a practical concepts from what he was describing.
The gap won’t be between people who use AI and people who don’t.
It’ll be between people who understand it and people who don’t.
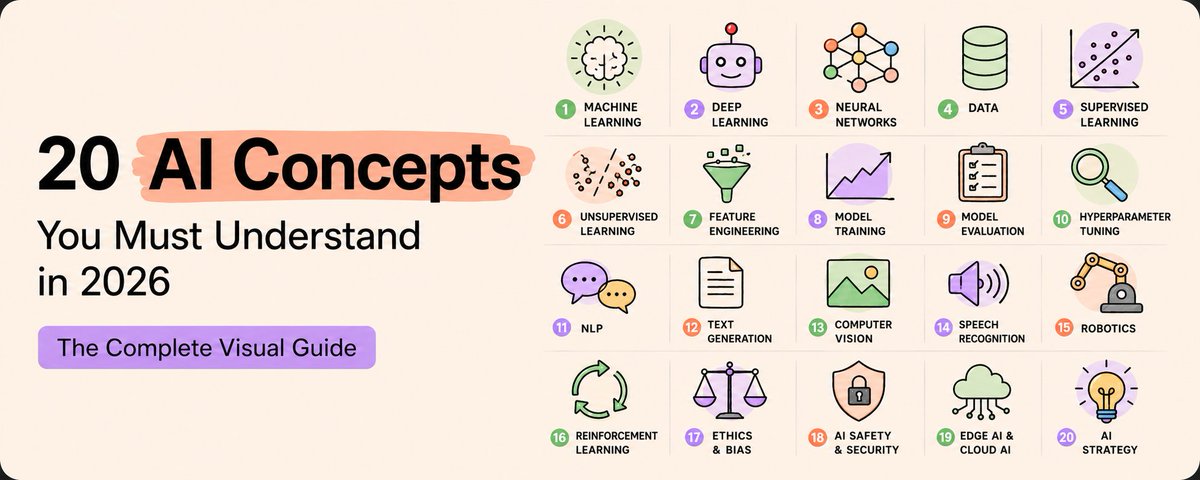
Start with these 20 AI concepts today 👇

Reading,
J. Bronowski,
"The ascent of man"
A book from his BBC TV program of the same name, From.the 1970s I think.


Mark Howell retweeted
pubmed.ncbi.nlm.nih.gov/3382…
and to reframe "emergence":
youtu.be/2RcW65tBxRA


Mark Howell retweeted

It's that time of year again - Welcome to the Control Advent Calendar 🎄
A unique way to explore the world of automatic control. Each day, a new question opens the door to real-world challenges — and highlights how control engineers help solve them. 🔗 buff.ly/9p5iYw8

The control systems advent calendar looks like it is back for another year.
control-advent.com/
Happy holidays

Mark Howell retweeted

🎙️ New episode! What is feedback, really? We go back to its prehistory, revisit Black’s negative-feedback amplifier, and trace the idea through biology, strategy, behaviour, and even our assumptions about causality.
Link: incontrolpodcast.com
Thanks: NCCR Automation

Mark Howell retweeted

We've become obsessed with the idea that the brain is a "Prediction Machine."
The dominant theory in neuroscience says we're constantly simulating the future, calculating probabilities to guess what happens next.
A new paper argues this is a complete illusion. The reality is simpler, and strangely, much more powerful.
Here is the argument for Perceptual Control:
The "Prediction Illusion" starts with a mistake in observation.
When we see someone successfully handle a chaotic environment (like catching a flyball), it *looks* like they predicted the future trajectory of the ball.
But observing prediction isn't the same as implementing it.
The authors use the perfect analogy: The Watt’s Steam Governor.
In the 19th century, this device kept steam engines running at a constant speed. If pressure surged, it slowed the engine. If load increased, it sped up.
To an observer, it looked like the machine was "predicting" pressure surges and pre-empting them.
But the Governor has no brain. It has no model of the future.
It’s a mechanical negative feedback loop. [cite_start]It measures the *current* speed, compares it to the *desired* speed, and adjusts the valve immediately[cite: 80].
It doesn't predict; it controls.
This brings us to the "Hello" experiment, which broke my brain a little.
Researchers asked people to keep a computer cursor on a target. The computer applied a "disturbance" (forces pushing the cursor away) that the person had to fight against with their mouse.
Here's the twist:
The disturbance wasn't random. [cite_start]It was an invisible force field shaped like the word "hello" (written upside down and mirrored)[cite: 166].
The participants fought the force, keeping the cursor steady.
When researchers looked at the participants' hand movements, they had perfectly written the word "hello".
Crucially, the participants had NO idea they were writing words.
If the brain were a "prediction machine," it would have needed to model the force to predict the hand movement.
But the participants wrote a legible word purely by reacting to immediate error signals—instantaneously correcting the cursor's position.
This is **Perceptual Control Theory (PCT)**.
The theory suggests the nervous system isn't a linear pipeline (Input → Compute → Output).
It’s a closed loop. We act to keep our *perception* of the world matching our internal *reference value*.
[Image of Perceptual Control Theory negative feedback loop diagram]
Think about catching a baseball.
If you were a "prediction machine," you’d calculate the ball's trajectory, wind speed, and gravity, then run to where the ball *will* be.
But that’s computationally expensive and error-prone.
In reality, fielders just run in a way that keeps the "optical velocity" of the ball constant in their vision.
If the ball looks like it's rising too fast, they move back. Dropping? They move forward.
No physics calculus required. Just maintaining a visual constant.
This solves the "Noise" problem.
In predictive models, small jitters in your movement are considered "noise" or errors to be filtered out.
It’s the system "feeling out" the environment to maintain control.
This has huge implications for AI and robotics.
We are currently building robots with massive compute power to "predict" stability.
But robots built on PCT principles—like inverted pendulums that just react to maintain verticality—are often more robust and stable than the predictive ones.
Why does this matter for you?
It changes how we view "agency."
We often think we need to predict the outcome of our actions to be effective. [cite_start]But the most efficient systems don't predict the outcome—they specify the goal and let the feedback loop handle the rest[cite: 39].
The "Prediction Illusion" suggests we aren't prophets simulating the future.
We are controllers, surfing the present.
We don't need to know what the wave will do in 10 seconds. We just need to keep the board steady right now.
If you want to dig into the paper, it’s "The prediction illusion: perceptual control mechanisms that fool the observer" by Mansell, Gulrez, and Landman (2025).
It’s a dense read, but it completely reframes the "Bayesian Brain" debate.
One final thought:
Next time you're doing something skilled—driving, typing, sports—notice the difference.
Are you calculating what comes next? Or are you just managing the gap between *what you see* and *what you want*?
You might find you're doing a lot less "thinking" than you assumed.


Possible application to NZIAT AI platform ai-forum-nz.circle.so/c/make…

Mark Howell retweeted

To learn more about temporal difference learning, you could read the original paper (incompleteideas.net/papers/s…) or watch this video (videolectures.net/videos/dee…).

The Dwarkesh/Andrej interview is worth watching. Like many others in the field, my introduction to deep learning was Andrej’s CS231n. In this era when many are involved in wishful thinking driven by simple pattern matching (e.g., extrapolating scaling laws without nuance), it’s refreshing to hear an influential voice that is tethered to reality.
One clarification for the podcast is that when Andrej says humans don’t use reinforcement learning, he is really saying humans don't use returns as learning targets. His example of LLMs struggling to learn to solve math problems from outcome-based rewards also elucidates the problem with learning directly from returns.
Fortunately for RL, this exact problem is solved by temporal difference (TD) learning. All sample-efficient RL algorithms that show human-like learning (e.g., sample-efficient learning on Atari, and our work on learning from experience directly on a robot) rely on TD learning.
Now Andrej is not primarily an RL person; he is looking at RL through the lens of LLMs these days, and all RL done in LLMs uses returns as targets, so it’s understandable that he is assuming that RL is all about learning from observed returns. But this assumption leads him to the incorrect conclusion that we need process-based dense rewards for RL to work.
If you embrace TD learning, then you don't necessarily need a dense reward. Once you have learned a value function that encodes useful knowledge about the world, you can learn on the fly in the absence of rewards, just like humans and animals. This is possible because in TD learning there is no difference between learning from an unexpected reward and learning from an unexpected change in perceived value.

