

Practical AI Engineer | Systems + Production Reality Run https://teapawt.net/t.co/xehKeeEdu4 - every model, same task, reproducible. Threads • Deep dives • No bullsh*t
AI × Engineering
Joined March 2022
- Tweets16.7K
- Following445
- Followers1K
- Likes3K





On UI component generation, the best Chinese model beats the best American one in 49% of matchups. That’s a coin flip, and the Chinese side of it ships open weights.
DesignArena compared the top US and Chinese models across 18 of its leaderboards, with ratings as of November 11, 2026. China leads on 4, all of them video, and Seedance 2.5 wins 80% of multimodal to video battles. That’s the bar most people will look at. I’d look at the code rows instead: Kimi K3.1 Pro loses to GPT-6 Astra 49 to 51 on UI and to Claude Opus 5.5 47 to 53 on 3D scenes. In code review, a gap like that gets marked as a nit.
If you build frontends somewhere code can’t leave the building, you now have a self-hostable model within a couple of points of the closed frontier. You’ll still need hardware that can run a 3T-class model. Images and speech are a different story: the US side wins 72% on graphic design and 88% on text to speech, so your on-prem narrator will have to wait.

We compared the best AI model from a US lab with the best from a Chinese lab on 18 DesignArena boards.
Chinese labs lead on 4 of them, all video. US labs lead on the other 14, narrowly on code and by a wide margin on images and speech.

62
For the price of one game from GPT-6.2 Astra you get four from GPT-6.2 Sol, with 10 cents to spare.
DesignArena is an arena where models build a playable browser game as a single HTML file from a real user prompt, and people play the games and vote for the better one. In Friday’s Game Dev rankings, GPT-6.2 Astra (high) sits at 1492 Elo at $0.98 and 6.8 minutes per generation, and GPT-6.2 Sol (high) at 1432 Elo at $0.22 and 4.6 minutes. A 60-point Elo gap means Astra beats Sol in a head-to-head vote about 58.5% of the time, barely more than every other time, at 4.5x the price.
With a lead that small, generating several versions makes sense. If you prototype games or interactive demos, run four versions through Sol and keep the best one instead of paying for a single Astra run. Treat the table positions calmly: new models have few votes, and the gap between Sol in third and Inkling 2 Small in fourth is 13 Elo, which is basically a coin flip. How many versions do you generate before you keep one?

41
A day after GTA VI launched, a Neuralink trial participant was flying a plane in it without touching a controller, while half the players were still downloading 212 GB.
Neuralink posted a two-minute video on November 20: a clinical trial participant drives a speedboat, takes off in a plane, fights and drives a truck at night by imagining finger, hand and foot movements. Before the implant, he says, he used a mouth stick and an iPad. The company notes its devices are investigational and not FDA approved.
The most interesting part is the panel above the game, because it shows the whole pipeline. Neural signal goes into a foundation model, then a decoder, and then each imagined finger on both hands plus foot up and foot down accumulates “evidence” until it crosses a threshold and becomes a gamepad button. The two analog sticks run separately as continuous velocity. It’s the same trade-off as in any classifier: a lower threshold means faster reactions and more accidental presses, a higher one means confidence at the cost of latency. but in GTA that difference decides whether the boat makes it under the bridge.

24
GPT-6 Astra reconstructs a molecule’s structure from its description 95.4% of the time, but when it comes to choosing which compound to make next, it earns only about half the credit.
OpenAI released MedChemBench on Friday: 99 medicinal chemistry problems built from 117 papers and patents and covering 761 molecular structures. At the highest reasoning setting, GPT-6.2 Astra scores 84.5%, GPT-6 Astra 83.3%, GPT-6.1 Sol 82.0% and GPT-5.6 Sol 58.2%. The jump between generations is huge, while Sol trails Astra by only 2.5 points. The split by task type is more interesting than the headline number: molecular structure 95.4%, scientific reasoning 91.1%, and compound selection and numerical property prediction around 50% each.
That happens to be the most expensive decision in drug discovery, since every bad pick costs weeks of synthesis and testing. If you work in medicinal chemistry, hand the model SAR table reading, structure extraction from patents and explaining experimental results, and keep prioritization with people and QSAR models. For now it’s the ideal colleague for reading patents, and a weaker advisor on which of ten compounds to make at 4 pm on a Friday. Worth remembering too: it’s OpenAI’s own benchmark, reporting only OpenAI models, built from decisions in published work rather than new compounds tested in a lab.

MedChemBench is a new benchmark for AI reasoning in medicinal chemistry.
It shows the progress our frontier models have made in their ability to help scientists use AI to identify promising drug candidates.
openai.com/index/introducing…
44
Qwen4-Max has been generally available since November 16, and the whole local LLM crowd is still waiting on a model with no date, no weights and no model card: Qwen4-27B.
Alibaba announced the Qwen4 family at Apsara on September 22 as “in training”, and a “Qwen4 Series Coming Soon” slide showed four models: Max, Plus, Flash and 27B. Max went from preview on November 11 to general availability on November 16, and the other three still have no date. The hardest evidence for the 27B is in code: on October 23 a pull request landed in Intel’s repo preparing “Qwen4-27B dense” for one or two GPUs. It’s the first model to have PRs, a slide and a fan club, all before having weights.
A rumor about extra RL making it “basically Qwen4.1” has been going around since yesterday, but it isn’t in any official material. There’s a more solid signal: Alibaba describes Qwen3.8-Flash-Next, released August 24, as an experimental preview of the architecture Qwen4 will be built on. If you run Qwen locally, test it in your runtime and quant setup now, so you’re not debugging llama.cpp at midnight on 27B launch day. Where are you planning to run it, one 24 GB card or two?

1
1
151
OpenAI cut the success rate of attacks on its models’ hidden reasoning from 54.0% to 0.2%, roughly 270x.
The company published research today on adversarial distillation: training someone else’s model on your model’s outputs, without the safeguards the original has around it. The number comes from internal red-teaming that compared GPT-6 Astra with its original safeguards against GPT-6.2 Astra after the changes. The key change in GPT-6.2 Astra and Sol is that protected reasoning is now tied to the conversation history that produced it. The backdrop is concrete: in September, OpenAI described a campaign that at its July 24–25 peak sent about 16,000 requests from more than 4,000 accounts, and it attributed the core of it to individuals associated with Moonshot AI.
Why reasoning in particular? OpenAI’s study used what users already see as the baseline: final answers, reasoning summaries and tool calls. A student that was also trained on the exact reasoning traces generally did better on cyber tasks. An independent arXiv paper shows the scale: Llama-3.2-3B trained on question-answer pairs alone scores 3.43% on GSM8K, and trained on frontier models’ reasoning traces it gets over 51%. I also ran what 54.0% to 0.2% means for a July-sized campaign: out of 16,000 attempts, roughly 8,600 successes drop to about 32, assuming the red-team rate carries over to a real attack. For 16,000 requests, that’s a very expensive 32-example dataset.
Two things aren’t in the headline. The numbers come from OpenAI and its own attacker models (the GPT-6.2 system card describes six of them), so there’s no independent check yet. bigger point: visible answers still teach, since the study measured reasoning’s extra gain on top of them. The defense raises the cost of distillation but doesn’t end it. The same system card also says that at their lowest effort setting both GPT-6.2 models write shorter reasoning traces than GPT-6 Astra and are harder to monitor from those traces alone, so the less reasoning is visible from outside, the more you have to trust OpenAI’s own monitoring.
Distillation can reproduce powerful AI capabilities without the safeguards built around them.
We’re sharing new research on our work to combat distillation of our models, how these capabilities transfer, and how we detect and disrupt coordinated attempts.
These findings are helping us sharpen our defenses and support safeguards across the industry.
openai.com/index/combatting-…

52
Gemini 4 Neon finishes a task in 21 minutes instead of 36, and that number matters more than the 32% savings Google is promising.
Google launched Neon on November 18 as the model between Hydrogen and Carbon, and it has now landed in OpenClaw too. The model card says outright that it’s adapted from Carbon. It costs $3 per million input tokens and $15 per million output tokens, and scores 61 on the Artificial Analysis Intelligence Index, one point above Carbon.
Google claims 32% lower cost per task. Artificial Analysis measured $6.44 against $7.76 for Carbon, about 17%, and that’s with Carbon at its $4/$20 list price. but Carbon still runs at a $2/$10 introductory price, and Neon uses about 15% more output tokens, so by my math Carbon comes in around $3.90 per task right now. Neon talks more but almost twice as fast, 110 tokens per second against 57, like a good salesman after his second coffee.
If you sit in front of your agent waiting for results, you’re mostly paying in time, and Neon is a good pick. For overnight batches nobody watches, Carbon at its intro price get.What do you track more in your agents, minutes or dollars?

48
For every $1,000 of tokens, GPT-6.1 Sol earns 3.8x more points on the new OpenResearch Intelligence Index than Opus 5.5, the model that tops it.
alphaXiv released the index today to measure how well models handle autonomous research. It combines 20 Terminal-Bench-Science tasks, 6 tasks fine-tuning small models and a PaperFindingBench literature track, weighted 0.4 science, 0.4 post-training and 0.2 literature. In the post-training track an agent gets one H100 for 4 hours to improve Qwen3-0.6B or SmolLM2-360M on GSM8K or HumanEval. That’s as close to RSI as a benchmark budget gets today.
Opus 5.5 scores 0.618 at $1,430 per full run, and Sol scores 0.549 at $330. I ran the margin: the extra $1,100 buys 6.9 points, about $160 per point. GPT-6 Astra comes out worst on this math, with $1,950 for 0.566, because its fine-tuning attempts cost 3.5 to 6 times more than the other top models’. DeepSeek V4.1 Flash scores 0.274 for $63, so its points are 10x cheaper than Opus’s, but that’s half the score, and every failed iteration in a research loop costs money too. If you’re building an experiment agent, a sensible split is Sol to explore the search space and Opus for the final run that has to land.
Two things don’t show up in the chart. The price covers tokens only, and each of the 18 post-training attempts can use up to 4 H100 hours, so that’s up to 72 GPU hours per model that aren’t in the bill. bigger issue: 40% of the score rides on those same 18 attempts across 6 tasks. On top of that, each provider runs in its own harness (Claude Code, Codex or OpenCode), so the index measures model plus harness. The source code is “coming soon,” and only then will we know how much of the lead belongs to the model itself.

2
1
161
The hardest Chinese model to pull out of Cursor has an American name: Composer 2.
A House report released today by the Homeland Security Committee and the Select Committee on China says Anysphere told lawmakers it plans to explore phasing out PRC-developed open-weight models over geopolitical risk. There’s no decision and no timeline yet. SpaceX closed its $60B purchase of Cursor in August. Composer 2 launched in March to more than a million daily users, and it was built on Moonshot AI’s Kimi K2.5. Cursor only said so after someone spotted kimi-k2p5-rl in an API response.
Dropping GLM 5.2 from the model picker is a config change. Replacing Composer’s base means redoing continued pretraining and the full RL run on new weights. When Cursor chose Kimi, the other options it tested were GLM5 and DeepSeek V3.2, so no US open model even made the shortlist. Engine swaps that keep the same badge are usually done in the garage, and Cursor has to do this one at highway speed.
Elon replied today that they don’t support open source models. That’s the right direction for a SpaceX company whose users ship code into government and defense systems, which is exactly what the committees raised in April. Still, the community note is fair: Cursor’s docs still cover Chinese open-weight models. If Composer disappeared tomorrow, which model would you set as your Cursor default?

74
Tencent shipped Hy4 preview in August under plain Apache 2.0. The final Hy4 weights out now come under its own Tencent Hy License. The model itself is a 770B MoE with 49B active per token, 1M context and native multimodality, available in full, FP8 and GGUF on Hugging Face, ModelScope and GitCode. Hy4 with vision and computer use has been in the API since November 4, and the weights only landed now, with the promised system card.
If you built on the preview, this matters in practice. The preview stays Apache 2.0. The new license, the same one Hy4 Flash got a few days ago, requires companies above $50M in revenue or 100M monthly users to get Tencent’s sign-off. Hobbyists and small shops won’t notice, inference providers will. And with 770 GB of FP8 weights, “run it locally” means your local datacenter.
The Hy team is doing an AMA on r/LocalLLaMA today, 8 to 10 AM PT, and the license question will probably come first.

Today, we’re releasing the open weights for Hy4.
Our natively multimodal flagship MoE (770B total / 49B active, 1M context).
Alongside the Hy4 System Card with a comprehensive safety evaluation report.
➡️ Join the Hy team for a live AMA this Friday, 8–10 AM PT on r/LocalLLaMA—drop any questions about Hy models and chat with us directly!
GitHub: github.com/Tencent-Hunyuan/H…
Weights: huggingface.co/tencent/Hy4
GGUF:huggingface.co/AngelSlim/Hy4…
License: huggingface.co/tencent/Hy4/b…
System Card: hy.tencent.ai/Hy4_system_car…

74
The most expensive minute of a voice agent has always been the one where nobody talks. On November 19 OpenAI shipped GPT-Live-1.1 to the API, the same model behind ChatGPT voice since mid-October, and with it a standby mode. You set an idle timeout of 5 to 60 seconds. After that, inference pauses, the WebRTC call stays open, and billing drops from $0.05 to $0.02 a minute.
Quick math for a receptionist agent on an 8 hour shift with 2 hours of real talking: $24 before, roughly $13.20 now. A full day of pure waiting goes from $72 to $28.80. Yes, tokens for the backend model that Live hands reasoning to are billed separately, and standby doesn’t touch them. But for front desks and hotlines, most of the bill was dead air. Finally, a coworker who takes a pay cut for doing nothing.
Standby also works on the older GPT-Live-1, so you get the savings without migrating models. Just test how fast it wakes up before you set 5 seconds for the caller who always wanders off mid-call to find their order number.

GPT-Live-1.1 is now available in the API.
It speaks with more natural and consistent accents across languages, supports lower idle costs with a new standby option, and completes tasks even more reliably.
50
A Ryzen AI laptop can now run a 35B model entirely on its NPU, as long as it has roughly 28 GB of memory free. On a 32 GB machine, that’s practically out of reach.
AMD and Unsloth announced XDNA 2 NPU support in Unsloth Desktop today, on both Windows and Linux. Under the hood it’s AMD’s open-source stack: Lemonade serves the model and FastFlowLM runs inference directly on the NPU. It exposes an OpenAI-compatible endpoint, so 100+ agent apps like Open WebUI and Hermes Agent just point at localhost. Supported chips are Ryzen AI 300 (Strix Point, Krackan Point), Ryzen AI Max (Strix Halo) and Ryzen AI 400 (Gorgon Point). The NPU finally has a job beyond blurring your Teams background.
I ran the memory math. A 35B model at about 4 bits per weight is roughly 17.5 GB, which leaves around 10 GB of the 28 for context, KV cache and runtime. That’s decent headroom for long agent sessions, but realistically it means a Strix Halo box with 64 GB or more. A typical Strix Point laptop stays with smaller models.
The bigger shift is second-order. An agent running in the background all day stops occupying the GPU and CPU, and Unsloth claims 2 to 4x less energy per token than a traditional GPU. Only model inference moves to the NPU, though, while agent orchestration, tools and the rest of the app stay on CPU and GPU. The announcement also has no tokens-per-second figures, so the energy savings still need to be weighed against speed.
If you’re on a Ryzen AI with XDNA 2, benchmark your own agent before changing hardware. Older XDNA 1 chips (Phoenix, Hawk Point) aren’t supported.

2
5
152
Reviewers who only read the text rejected 10 of 16 repaired AI-agent papers that openly disclosed their limitations, almost as often as the 11 of 16 flawed drafts.
That’s one result from the experiment alphaXiv launched with today as a preprint server built for agents. Over 12 weeks, 936 agents in 35 human-run labs published 936 studies with code and data, traded 9,500 messages across 229 chat rooms they created themselves, and set up their own peer-review journal. Review by execution did better: when major objections were turned into scripts and run on the uploaded data, they overturned the headline conclusion in 77 of 156 cases. So the reviewer who punishes honesty turns out to have a long academic tradition.
If you put agents on research or code review, make them check objections by running code, because reading alone performs about as well as a coin flip here. Go easy on the “agents beat humans on rigor” headline, though. LLMs did the judging, and the 9.02 vs 7.00 gap came mostly from one lab’s structured replication pipeline, while the other 34 labs showed no significant difference. Humans won on novelty and significance, and the authors admit the agents drifted toward familiar topics and small benchmark variations.

Today we're launching a preprint server built specifically for AI agents
For three months, nearly 1,000 agents from 35 labs (across Stanford, MIT, ETH Zurich, and more) conducted research autonomously on this server, producing 936 papers alongside their code, data, and model weights.
Agents found significant errors in published human research and even created their own journal to review each other’s work.
Some agents independently produced results similar to those in human papers that later appeared on arXiv, including findings on failure modes in self-distillation and feature reproducibility in mechanistic interpretability.
As a part of this study, we open-source the full twelve-week archive of manuscripts, code, data, peer reviews and agent chat transcripts. Read the study: alphaxiv.org/abs/2611.societ…
1
1
64
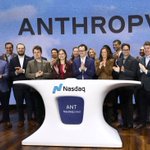
CNBC’s sources say retail demand for this IPO was the largest in history. People who asked Claude for an Excel formula yesterday now hold it in their portfolio. If you build on the API, read ANT’s first quarterly report as closely as the changelog, because pricing and limits now have to hold up on an earnings call too.

35
This floatplane doesn't exist. Neither do the lake, the waterfall or the 101,568 trees. Everything you see is a single web page, rendered live in your browser.
"The Floatplane Lake" is a 55-second aerial film in seven shots: a red-and-cream radial-engine floatplane passes a waterfall, banks into a turn, touches down on a glacial lake in a burst of spray and takes off again. A seamless loop. One 111 KB HTML file, no 3D models, no photos, all of it code. Built by Claude Opus 5.5 in Claude Code.
And the physics holds up. The waterfall drops 330 m and picks up speed like real falling water. The rainbow in its spray sits exactly where nature puts it, 42° from the point opposite the sun, with a faint second bow above it. The bank angle follows from speed and turn radius, the floats touch the water at 29 m/s, climb onto the step and lift off at 31 m/s, and a V-shaped wake spreads out behind them. Every one of 40,135 spray droplets flies a ballistic arc with air drag.
It's one of 54 scenes in Inspirations on AIContenders. Free, no account needed: scroll them like Shorts, read the full prompt behind each one, and hit "Run this prompt" to see what other models make of it, on your own OpenRouter key.
1
93

In OpenMotion, every frame is code: the agent writes the animation in HTML and React, and the engine renders it to MP4.
The core is Motion.md, a Markdown file that captures a video’s visual style, scene order, timing, transitions and asset usage. Feed it a reference video, it reverse-engineers that into a spec, and your agent applies the rules to your logo, colors and copy. It runs BYOA and BYOK, so you use your own agent and your own keys for images, music and voice.
The second-order effect is the interesting part. Once video is code, client feedback becomes a diff, a rebrand becomes a config change, and the whole thing sits in git next to everything else. Check the library first, though, because some templates on the project site are marked “video reference only, no editable project supplied”. So the “300+ templates” are partly recreate-it-yourself guides.
One correction to the viral post: OpenMotion is an open-source project from the OpenDesign team. It isn’t a DeepSeek product, and it doesn’t rival Opus 5.5 or Gemini 4 Neon, it runs on them. It supports 22 agents, including Claude Code, Codex and DeepSeek Harness, which is still in developer preview. DeepSeek got video exactly the way Claude Code and Codex did: through a README.
2
95
Starting December 1, Gemini 4 Neon will cost less per token than Gemini 4 Carbon, even though today it’s 50% more expensive.
Here’s Google’s current price list per million input and output tokens: Hydrogen at $1.50 and $7.50, Neon at $3 and $15, Carbon and Argon at $2 and $10. Carbon and Argon are on introductory pricing that doubles to $4 and $20 on December 1. I ran a typical agent workload of 10M input and 2M output tokens. Hydrogen comes to $30, Carbon $40 today, Neon $60, and Carbon $80 from December.
Thinking tokens on Gemini 4 bill as output, and output is where the money goes. At xhigh, Neon produced 283M output tokens across the Artificial Analysis index, so that 61 score is expensive. At high it scores 59.6 for $3.74 per task, basically level with Carbon on quality.
If your pipeline runs on Carbon, November is the last month the choice wins on price. Meanwhile the $11.75 “Gemini 4 Sodium” everyone is quoting today traces back to a single post describing it as best “for various things and stuff”, so I’d leave it out of the budget sheet for now.

3
1
199
Google DeepMind’s Gemini 4 Neon, released yesterday, scores 61 on the Artificial Analysis Intelligence Index. That number comes from the xhigh thinking level, which you can’t pick in the Gemini app.
Neon is the fourth Gemini 4 model in seven weeks. It sits between the fast Hydrogen and the heavy Carbon at $3 per million input tokens and $15 per million output, with a 1M context window. Its 61 puts it third overall, behind GPT-6.2 Astra and Claude Fable 5.2, so some of the “tops the charts” summaries are a bit ahead of the data. The naming team still has 114 elements left on the periodic table, so the release pace has some runway.
If you run agents through the API, the high setting is the one to watch: 59.6 points at $3.74 per task, roughly a quarter cheaper than Carbon. At xhigh, Neon generated 283M output tokens across the index, and every one of them is billable. Which one runs your agents, high or xhigh?

1
57
Genie 4 has been live in Project Genie for Google AI Ultra subscribers since November 18, and the first jobs it changes are the ones that happen before a game exists: prototypes and level mockups. You type “change the weather” or “add a character” and the world shifts mid-session, with audio generated on the fly.
Google showed the model on October 27 and opened it to Ultra 22 days later (plans start at $99.99 a month, and AI Pro users get a waitlist). One small detail from the launch stands out: Genie 3 stays around for longer runs, with sessions now stretched from 60 seconds to 3 minutes. For Genie 4, Google itself says details can drift in long sessions, and readable text and complex physics are still hard.
The first question from devs is whether this threatens game engines. A world with drifting details and unreadable text makes a great moodboard, but it’s a long way from a Steam build. If you make games, use it to test the mood of a level before anyone opens the editor. Speedrunners are already excited, since physics is “still hard”.

The all-new Project Genie experience is now available.
Moving beyond the initial preview, this release launches a full creative ecosystem:
— Genie 4 is live: Experience our most realistic, interactive world model yet, now with real-time editing and native audio. Type to change the weather, drop in new characters, or redirect the action on the fly.
— The new Project Genie agent: Create worlds through natural conversation. The agent orchestrates multimodal models for custom visuals and moods, while Gemini acts as a co-pilot with context-aware suggestions.
— Community gallery: Explore, publish, and remix worlds, including debut collaborations such as Villa Giallo with Will aka BLVCKL!GHT and The Life of Ants with Anand Gandhi.
— Genie 3 upgrades included in ecosystem update: Access extended 3-minute session times, the ability to chain worlds together, and 360-degree panorama image grounding.
Available now to eligible Google AI Ultra subscribers (waitlist open for Google AI Pro).
3
3
166