

Computer Vision PhD student at University of Maryland College Park Website: https://teapawt.net/t.co/7rfVPC9ZUS
Joined June 2022
- Tweets24
- Following14
- Followers159
- Likes18

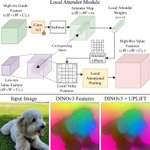



We’re looking forward to presenting UPLiFT at #CVPR2026! Efficiently extract pixel-dense features from pretrained backbones like DINOv3.
We’ll be at the final poster session on Sunday (6/7) from 3:30-5:30pm at Poster 474, so please come by!
Website: cs.umd.edu/~mwalmer/uplift/

Matthew Walmer retweeted

Diffusion models be like:
“this image is 97% noise… better process all 256×256 pixels anyway”
If very noisy diffusion states contain no more useful information than a tiny downsampled image,
Then why run expensive full-res computation on them?
🧵

Excited to announce that UPLiFT has been accepted to #CVPR2026!
You can also try out UPLiFT right now to extract pixel-dense DINOv3 features with our pretrained models linked below!
Code: github.com/mwalmer-umd/UPLiF…
Paper: arxiv.org/abs/2601.17950
Website: cs.umd.edu/~mwalmer/uplift/

We’re excited to announce UPLiFT, our lightweight, pixel-dense feature upsampler. UPLiFT boosts feature density, preserves semantics, and has better efficiency scaling than recent SOTA methods. See all links in the thread below.
Coauthors: @_sakshams_ @AnirudAgg @abhi2610
🧵[1/6]


We demonstrate the versatility and effectiveness of UPLiFT for both predictive and generative tasks, including semantic segmentation, depth estimation, image super-resolution, and efficient T2I generation.
🧵[5/6]

10
573
Through this approach, our method maintains linear-time-scaling with respect to the number of visual tokens. Meanwhile, cross-attention-based upsamplers have quadratic scaling. This allows UPLiFT to scale and make denser features for larger images.
🧵[4/6]

7
614
UPLiFT uses iterative feature growing, which avoids the high computational costs of recent cross-attention-based methods. We also present a new Local Attender feature-pooling module, which reformulates local attention using operations based on relative directional offsets
🧵[3/6]

6
741
Today we are also releasing our UPLiFT code and 3 pretrained models for DINOv2-S/14, DINOv3-S+/16, and SD1.5 VAE. We also include torch hub support and training code.
Paper: arxiv.org/abs/2601.17950
Code: github.com/mwalmer-umd/UPLiF…
Website: cs.umd.edu/~mwalmer/uplift/
🧵[2/6]

Matthew Walmer retweeted

🎉 Excited to share our paper "Trokens: Semantic-Aware Relational Trajectory Tokens for Few-Shot Action Recognition" has been accepted to #ICCV2025!
Equally co-led with @ShuaiyiH — we advance few-shot action recognition via smart point tracking.
🔗 trokens-iccv25.github.io
🧵👇

Matthew Walmer retweeted

We are happy to release our LiFT code and pretrained models! 📢
Code: github.com/saksham-s/lift
Project Page: cs.umd.edu/~sakshams/LiFT
Here are some super spooky super resolved feature visualizations to make the season scarier 🎃
Coauthors: @MatthewWalmer @kamalgupta09 @abhi2610


We introduce LiFT, an easy to train, lightweight, and efficient feature upsampler to get dense ViT features without the need to retrain the ViT.
Visit our poster @eccvconf #eccv2024 in Milan on Oct 1st (Tuesday), 16:30 (local), Poster: 79. Project Page: cs.umd.edu/~sakshams/LiFT

Matthew Walmer retweeted
We introduce LiFT, an easy to train, lightweight, and efficient feature upsampler to get dense ViT features without the need to retrain the ViT.
Visit our poster @eccvconf #eccv2024 in Milan on Oct 1st (Tuesday), 16:30 (local), Poster: 79. Project Page: cs.umd.edu/~sakshams/LiFT
Just a reminder we’ll be presenting this evening at the Tuesday 4:30pm poster session at #CVPR2023. Hope to see you there!

We’re looking forward to presenting our work “Teaching Matters: Investigating the Role of Supervision in Vision Transformers” next week at #CVPR2023! We’ll be in the Tues-PM poster session at board 321.
Links and some key results below.
@_sakshams_ @kamalgupta09 @abhi2610
[1/5]
1
115
We’re looking forward to presenting our work “Teaching Matters: Investigating the Role of Supervision in Vision Transformers” next week at #CVPR2023! We’ll be in the Tues-PM poster session at board 321.
Links and some key results below.
@_sakshams_ @kamalgupta09 @abhi2610
[1/5]

Even though MAE has no CLS objective, we find evidence that it learns to embed semantic information in the CLS token even before fine-tuning. Through CKA analysis, we find some similarity between MAE, DINO, and MoCo CLS token representations.
[4/5]

3
116
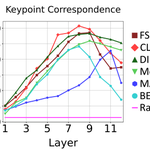
Did you know that ViTs learn to use offset local attention heads? These heads attend locally, but to a position that is one off in one direction. The existence of these heads may actually demonstrate a strength of CNNs over ViTs.
[3/5]

3
78
We compared ViTs from 6 different supervision methods and identified key similarities and differences between them. We examine: attention, features, and downstream performance.
Paper: openaccess.thecvf.com/conten…
Website: cs.umd.edu/~sakshams/vit_ana…
Code: github.com/mwalmer-umd/vit_a…
[2/5]

4
115
Matthew Walmer retweeted
Excited to share our work "Teaching Matters: Investigating the Role of Supervision in Vision Transformers" which has been accepted to #CVPR2023!
Work done with: @MatthewWalmer, @kamalgupta09 and @abhi2610
Website: cs.umd.edu/~sakshams/vit_ana…
Code: github.com/mwalmer-umd/vit_a…

Matthew Walmer retweeted

Before I forget, I'd like to summarize some interesting papers that I found at #CVPR2022.
Dual-key multimodal backdoors for visual question answering
arxiv.org/abs/2112.07668
1. This paper proposes an interesting Trojan attack method.
To start, what exactly is a Trojan attack?
