

PhD @UW | Microsoft FATE Research Intern |Human-AI interaction & NLP |psychology & mathematics @Middlebury’22
Seattle, USA
Joined August 2017
- Tweets153
- Following1.1K
- Followers286
- Likes854


Pinned Tweet
Human evaluation is often treated as the gold standard for long-form generation, but how much can we trust it if papers don’t report how it was done?
We study this question in our large-scale survey “Illusions of the Gold Standard” to be presented at @aclmeeting! 🧵1/n

Exciting direction!!!

What’s beyond turn-based language models? 🤔
I believe future AI agents will become increasingly multimodal and interactive, excelling not only at task completion but also at proactive, real-time interaction with people across modalities.
We’re excited to push this frontier, first by enabling closed-loop evaluation and training of visual interaction agents, using simulated worlds and users across cooking, household, and mobile-use tasks.
4
358
Katelyn Mei retweeted

I recently gave an invited lecture on deep research agents for CMU’s AI Agents course, covering evaluation beyond simple factoid QA, RL for open-ended tasks, and a new retrieval paradigm for deep research agents!
youtu.be/nKUBrXFQBUM

Katelyn Mei retweeted

‼️The Bitter Lesson for context management: Giving LMs unrestricted control over their context beats human-designed SOTA!
Introducing 🩵Context Language Models (CLMs)🩵
- Natively manage their own context
- Treat context as a file
- Learn policies in CLM weights, no harness

Looking forward to it! @Tim_Dettmers

Starting tomorrow, our lab will hold an open-source week: 2 software frameworks, 4 papers, all building a coherent ecosystem.
The theme: Frontier AI on Hardware You Own
Blog post: timdettmers.com/2026/09/21/d…
SoTA results in:
Autocompaction
Autonomous Research
Model compression
Test-time scaling
Deep Research
And a healthcare RL environment giving you a new level of complexity to train healthcare agents.
The ecosystem that we will release is built to be as usable as possible. Agent sessions that run overnight and go on for tens of millions of tokens is made easy. Model compression of a model is automatic: you just get a good model that runs fast locally -- no expertise required. An autonomous research that works out of the box.
Our ecosystem enables a new level of work that can be done locally.
1
227
Katelyn Mei retweeted
Building an environment to develop and evaluate multi-agent systems at scale is challenging. Software World is our first step towards it:
📍We build a simulated GitHub ecosystem for agents that reflects the realistic needs of experienced software developers.
📍We construct robust, held-out, verifiable downstream applications that are less susceptible to reward hacking.
Check out our blog post to learn more!
theagentorg.app/


Very honored to share that our work receives 🏅SAC Highlight at #ACL2026 !
This work came together as an outcome of resilience, passion, and dedication. Very grateful for my collaborators , reviewers, and ACs in the process!
Meanwhile I have felt so inspired by all the amazing work at #ACL2026 and it’s all the dedication together that made science grow with passion! Looking forward to the next!


Human evaluation is often treated as the gold standard for long-form generation, but how much can we trust it if papers don’t report how it was done?
We study this question in our large-scale survey “Illusions of the Gold Standard” to be presented at @aclmeeting! 🧵1/n
I'll present our work tomorrow at #ACL! Looking forward to chatting with more folks who are interested in human evaluation!

Human evaluation is often treated as the gold standard for long-form generation, but how much can we trust it if papers don’t report how it was done?
We study this question in our large-scale survey “Illusions of the Gold Standard” to be presented at @aclmeeting! 🧵1/n
She’s not going to ICML but she will be surfing 🏄♀️ at #ACL :D

Our team will present DR Tulu and Spurious Rewards at #ICML2026! Sadly, I'm not attending in person. Please come and chat with my superstar coauthors!
DR Tulu:
- Wed. July 8 10:15-10:30 AM KST, Hall B2 (Oral presentation)
- Wed. July 8 2:30-4:15 PM KST, Hall A #1800 (Poster)
Spurious Rewards:
- Tue, Jul 7 10:30 AM–12:15 PM KST, Hall A #1709 (Poster)


1
12
3,160
Read the full paper here for many more analyses📰: arxiv.org/abs/2606.07936

👋If you are interested in chatting more about our work, please feel free to reach out to us, and we will be at @aclmeeting!
2
5
886
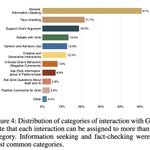
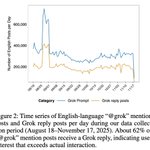
🚨🎉Excited to announce that our paper “Grok in the Wild: Characterizing the Roles and Uses of Large Language Models on Social Media” is accepted at @icwsm 2026! In this paper, we investigate how, when, and to what effect Grok is used on X.
🧵1/n thread

If you are interested in more details on how Grok is used for fact-checking in particular, please also see this amazing recent work osf.io/preprints/psyarxiv/85… by @captaineco_fr @_mohsen_m @DG_Rand !

1
2
331
If you are interested in more details, please read our paper! We also include findings on engagement with Grok reply, main clusters of Grok users, and topics that Grok users @grok for.
Paper link: arxiv.org/pdf/2602.11286
1
2
222