
MetaCircle/元环智能, AI for AI, Science of AI, Mechanistic AutoResearch
Joined July 2026
- Tweets18
- Following4
- Followers216
- Likes14

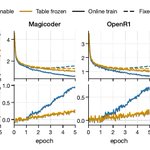
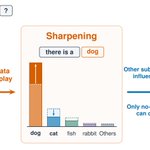


Over-encoding, a memory trick akin to DeepSeek v4.1’s Engram, really works—but it has a failure mode. We call it Forking: under data replay, train loss keeps falling while validation loss turns up. The two curves split like a fork.
Watch the explainer below 👇
@ZimingLiu11
3/4 Post-training replays data too, and Forking comes back on small code, math, and RLVR-style corpora. Freezing the n-gram table helps.


We quantified LLMs’ training intuition—and revealed its blind spots.
ArchitectureIQ: 500 questions. One synthetic dataset, three recipes per question. Answers verified by training runs.
GPT-5.6 Sol: 76.4% accuracy (chance: 33.3%).
Watch the explainer below👇
@ZimingLiu11
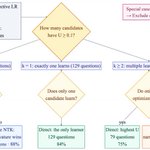
3/4 Models invoke training physics: cumulative effective learning rate U (Adam ≈ ηT, Adagrad ≈ 2η√T), NTK curvature, and zero-momentum SGD failures. A readable decision-tree policy reaches 78.2% out-of-fold accuracy: intuition compresses into rules.


Staring from 2022, @ZimingLiu11 has the habit of MANUALLY browsing and collecting fun arXiv papers, gathering ~2000 papers in total.
Today we release this paper list, and test if an LLM agent could learn my taste simply from this paper list.
meta-circle.com/blog/can-tas…
🤖 Made with AI

We open-source our AI experiment workbench, great for exploring "Science of AI"!
We deem it as a playground where it's easy to compose experiments and observe new phenomena. We believe that observing more phenomena is the first step towards a "Science of AI".

Bored of Jupyter Notebooks or Python files? Introducing ComfyResearch -- a new, graphical way to visualize AI experiments.
With ComfyResearch, "Science of AI" becomes super easy and fun, like building LEGO. Infinite worlds, infinite phenomena!
Our blog: meta-circle.com/blog/comfyre…
Bored of Jupyter Notebooks or Python files? Introducing ComfyResearch -- a new, graphical way to visualize AI experiments.
With ComfyResearch, "Science of AI" becomes super easy and fun, like building LEGO. Infinite worlds, infinite phenomena!
Our blog: meta-circle.com/blog/comfyre…

Current Auto-Research systems are Shakespeare's monkeys, typing randomly, hoping brilliance emerge from chaos.
Today, we @MetaCircle_AI propose "Mechanistic Auto-Research", not using any LLMs, but surpassing RSI's results.
Scale insight, not compute.
meta-circle.com/blog/ophis-a…
At @MetaCircle_AI (元环智能), we work on mechanistic autoresearch, we believe that understanding and structure should precede naive brute-force automation. In order for AI4AI systems to deliver next "transformers", we should:
Scale insight and understanding, not (just) compute